
Count Nodes That Are Great Enough - Solution & Explanation
Problem Statement
You are given a root to a binary tree and an integer k. A node of this tree is called great enough if the followings hold:
- Its subtree has at least
knodes. - Its value is greater than the value of at least
knodes in its subtree.
Return the number of nodes in this tree that are great enough.
The node u is in the subtree of the node v, if u == v or v is an ancestor of u.
Example 1:
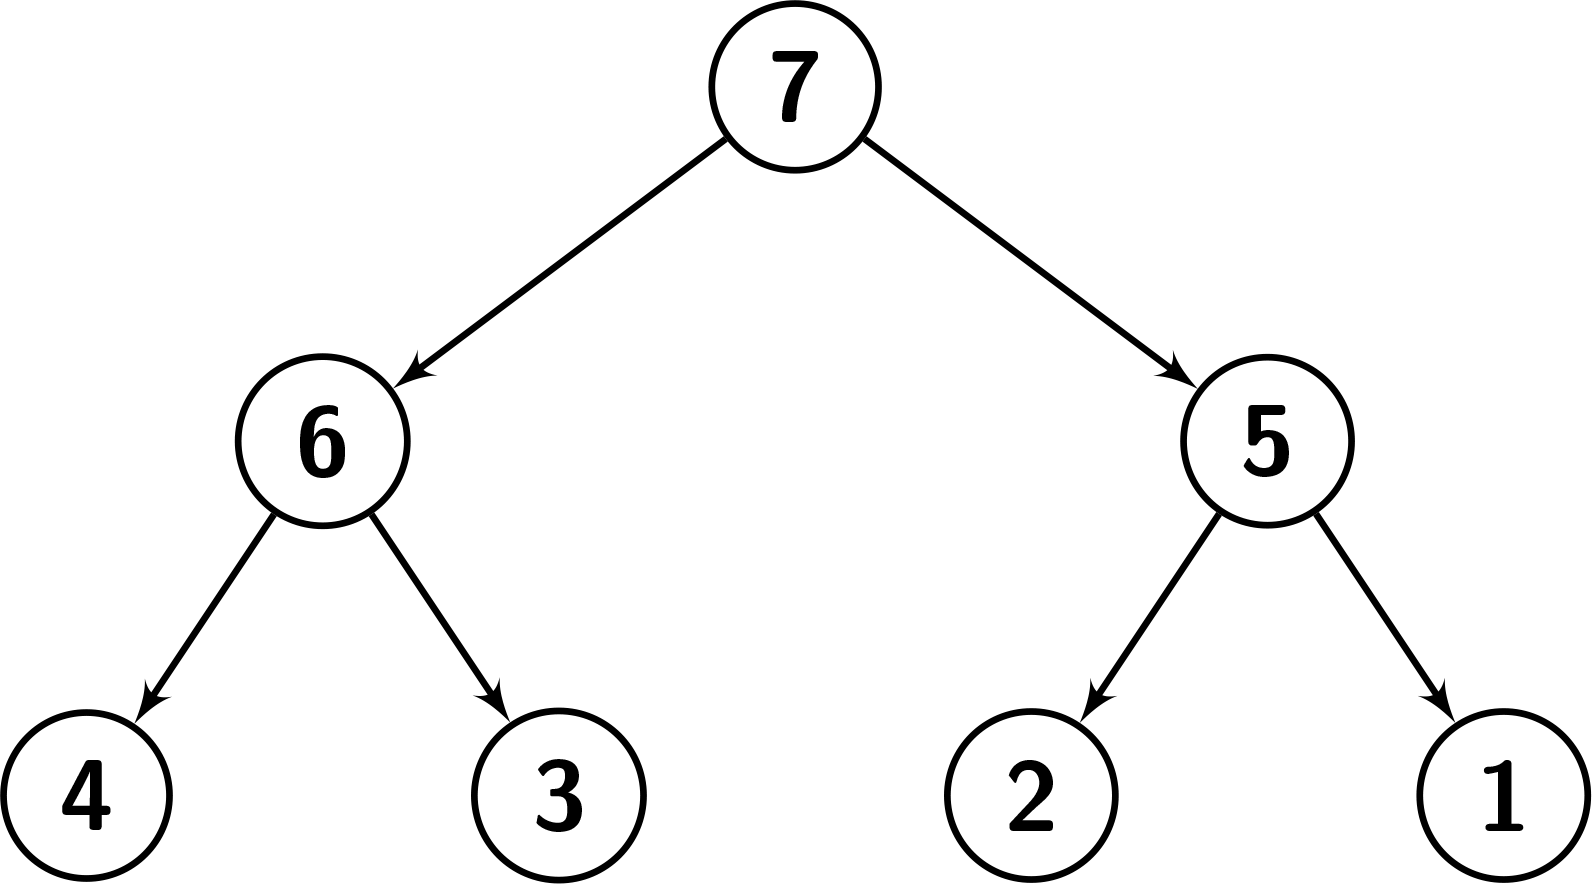
Input: root = [7,6,5,4,3,2,1], k = 2
Output: 3
Explanation: Number the nodes from 1 to 7.
The values in the subtree of node 1: {1,2,3,4,5,6,7}. Since node.val == 7, there are 6 nodes having a smaller value than its value. So it's great enough.
The values in the subtree of node 2: {3,4,6}. Since node.val == 6, there are 2 nodes having a smaller value than its value. So it's great enough.
The values in the subtree of node 3: {1,2,5}. Since node.val == 5, there are 2 nodes having a smaller value than its value. So it's great enough.
It can be shown that other nodes are not great enough.
See the picture below for a better understanding.
Example 2:
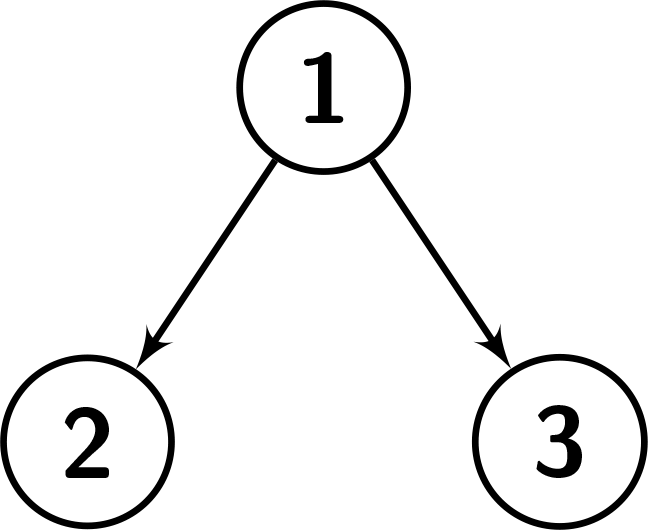
Input: root = [1,2,3], k = 1
Output: 0
Explanation: Number the nodes from 1 to 3.
The values in the subtree of node 1: {1,2,3}. Since node.val == 1, there are no nodes having a smaller value than its value. So it's not great enough.
The values in the subtree of node 2: {2}. Since node.val == 2, there are no nodes having a smaller value than its value. So it's not great enough.
The values in the subtree of node 3: {3}. Since node.val == 3, there are no nodes having a smaller value than its value. So it's not great enough.
See the picture below for a better understanding.
Example 3:
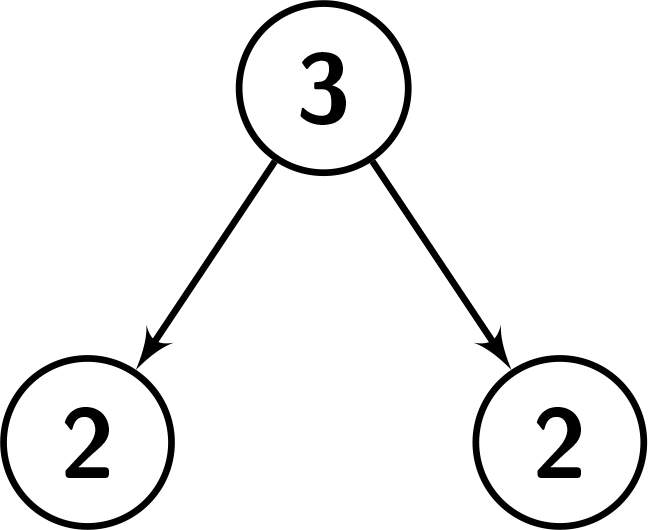
Input: root = [3,2,2], k = 2
Output: 1
Explanation: Number the nodes from 1 to 3.
The values in the subtree of node 1: {2,2,3}. Since node.val == 3, there are 2 nodes having a smaller value than its value. So it's great enough.
The values in the subtree of node 2: {2}. Since node.val == 2, there are no nodes having a smaller value than its value. So it's not great enough.
The values in the subtree of node 3: {2}. Since node.val == 2, there are no nodes having a smaller value than its value. So it's not great enough.
See the picture below for a better understanding.
Constraints:
- The number of nodes in the tree is in the range
[1, 104]. 1 <= Node.val <= 1041 <= k <= 10
Approach Overview
Problem Overview: You are given a binary tree and an integer k. A node is considered great enough if there are at least k nodes in its subtree whose values are strictly smaller than the node’s value. The task is to count how many nodes satisfy this condition.
Approach 1: Brute Force Subtree Scan (O(n²) time, O(h) space)
For every node, traverse its entire subtree and collect all values. Count how many values are smaller than the current node’s value and check if that count is at least k. This can be implemented with a DFS from each node. The drawback is repeated work: the same subtree nodes are scanned many times. In a skewed tree, this leads to O(n²) time complexity with recursion stack space O(h). This approach is useful for understanding the problem but does not scale for large trees.
Approach 2: Postorder DFS with Size-K Heap (O(n * k log k) time, O(k * h) space)
The optimized solution processes the tree using a postorder Depth-First Search. Each recursive call returns the k smallest values found in that subtree. Instead of storing every value, keep a bounded max-heap (or sorted container) of size at most k. When combining results from the left and right children, merge their candidate values while maintaining the size limit.
At a node, you already have the k smallest values from its descendants. If the heap size is k and the current node’s value is greater than the largest value inside that heap (the k-th smallest), then there are at least k nodes in the subtree with smaller values. That node is counted as great enough. After the check, insert the current node’s value into the heap and trim it back to size k before returning it to the parent.
This technique works because the only values relevant to ancestors are the k smallest ones. Any larger values can never affect the comparison for nodes higher in the tree. The traversal naturally follows the recursive structure of a binary tree, while the merging of partial results resembles a divide and conquer strategy.
Recommended for interviews: The postorder DFS with a bounded heap is the expected solution. Mentioning the brute force approach first demonstrates you understand the definition of the subtree condition. The optimized method shows you can reduce redundant work by propagating only the necessary information (the k smallest values) during DFS.
Solution
Try this approach in the editor →Detailed Complexity Analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Brute Force Subtree DFS | O(n²) | O(h) | Useful for understanding the definition of the subtree condition or when constraints are very small |
| Postorder DFS with Size-K Heap | O(n * k log k) | O(k * h) | General case for large trees; keeps only k smallest values per subtree |
Video Solution
2792. Count Nodes That Are Great Enough (Leetcode Hard) • Programming Live with Larry • 191 views views
Watch 2 more video solutions →Frequently Asked Questions
Is Count Nodes That Are Great Enough easy or hard?
Count Nodes That Are Great Enough Python/Java solution
How to solve Count Nodes That Are Great Enough in O(n)?
What is the best approach for Count Nodes That Are Great Enough?
Is Count Nodes That Are Great Enough asked at Google/Amazon/Meta?
What data structure is used in Count Nodes That Are Great Enough?
What is the time complexity of Count Nodes That Are Great Enough?
Ready to solve this problem?
Practice Count Nodes That Are Great Enough with our built-in code editor and test cases.
Practice on FleetCodeProblem Info
Table of Contents
Practice this problem
Open in Editor