
Construct Binary Tree from Inorder and Postorder Traversal - Solution & Explanation
Problem Statement
Given two integer arrays inorder and postorder where inorder is the inorder traversal of a binary tree and postorder is the postorder traversal of the same tree, construct and return the binary tree.
Example 1:
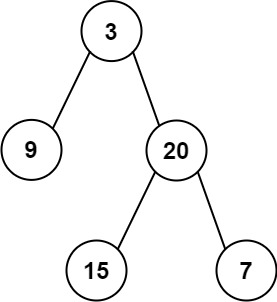
Input: inorder = [9,3,15,20,7], postorder = [9,15,7,20,3]
Output: [3,9,20,null,null,15,7]
Example 2:
Input: inorder = [-1], postorder = [-1]
Output: [-1]
Constraints:
1 <= inorder.length <= 3000postorder.length == inorder.length-3000 <= inorder[i], postorder[i] <= 3000inorderandpostorderconsist of unique values.- Each value of
postorderalso appears ininorder. inorderis guaranteed to be the inorder traversal of the tree.postorderis guaranteed to be the postorder traversal of the tree.
Approach Overview
Problem Overview: You are given two traversal arrays of the same binary tree: inorder and postorder. The goal is to reconstruct the original binary tree. The challenge is determining how to split the tree correctly using the ordering properties of both traversals.
Approach 1: Recursive Divide and Conquer with HashMap (O(n) time, O(n) space)
The key observation comes from traversal properties. In postorder, the last element is always the root of the current subtree. Once you identify the root, you locate its position inside the inorder array. Everything to the left of that index belongs to the left subtree, and everything to the right belongs to the right subtree. To avoid repeatedly scanning the inorder array, store each value's index in a HashMap for constant-time lookups.
The algorithm processes the postorder array from the end. Each recursive call creates a node, splits the inorder range, and recursively builds the right subtree first, then the left subtree. Building the right subtree first is necessary because postorder processes nodes as left → right → root, so when iterating backwards the order becomes root → right → left. Each node is created exactly once, producing O(n) time complexity with O(n) space for recursion and the hash map. This approach combines divide and conquer with efficient lookups using a hash table.
Approach 2: Iterative Construction using Stack (O(n) time, O(n) space)
An iterative strategy avoids recursion by simulating the construction process with a stack. Start from the last element of postorder, which is the root, and push it onto the stack. Traverse the postorder array backwards while tracking an index in the inorder array. The stack represents the path of nodes whose left child hasn't been attached yet.
If the top of the stack doesn't match the current inorder value, the next node becomes the right child of the stack's top node. If it matches, pop nodes from the stack until the values diverge; the next created node becomes the left child of the last popped node. This mirrors how inorder traversal signals that the right subtree has finished and the algorithm should move left. Each node is pushed and popped at most once, giving O(n) time complexity and O(n) auxiliary stack space. The approach is useful when you want to avoid deep recursion while working with binary tree construction problems.
Recommended for interviews: The recursive HashMap approach is the expected solution. It clearly demonstrates understanding of traversal properties and divide and conquer. Interviewers usually want to see the insight that the last element of postorder is the root and that a hash map reduces the lookup cost to O(1). The iterative stack version shows deeper mastery but is less commonly expected as the primary solution.
Approach 1: Recursive Approach using HashMap
This approach uses recursion and a HashMap to efficiently construct the binary tree. The key insight is that the last element in the postorder array is the root node. This node's index in the inorder array can be found using a HashMap, allowing constant time access during recursive calls.
This Python solution employs a recursive helper function to build the tree. The postorder index is decremented each time a new root is established, while the hashmap provides constant-time access to any given node's inorder index.
Complexity
Time Complexity: O(n), where n is the number of nodes. Each node is visited once.
Space Complexity: O(n), where n is the number of nodes for storing the map and recursion stack.
Approach 2: Iterative Approach using Stack
This approach builds the tree using an iterative method with a stack. It tracks nodes that need a child and assigns them accordingly. It takes advantage of the tree properties in the postorder and inorder arrays for efficient traversal and node placement.
This JavaScript solution uses a stack to iteratively build the tree. It maintains nodes that need children and assigns nodes based on whether they are different from the current inorder node. Nodes are popped from the stack when they match inorder traversal to handle left children appropriately.
Code
JavaScript
C#
Complexity
Time Complexity: O(n), where n is the number of nodes. Every element is seen once.
Space Complexity: O(n), where n is the number of nodes to account for the stack and tree storage.
Approach 3: Hash Table + Recursion
The last node in the post-order traversal is the root node. We can find the position of the root node in the in-order traversal, and then recursively construct the left and right subtrees.
Specifically, we first use a hash table d to store the position of each node in the in-order traversal. Then we design a recursive function dfs(i, j, n), where i and j represent the starting positions of the in-order and post-order traversals, respectively, and n represents the number of nodes in the subtree. The function logic is as follows:
- If
n leq 0, it means the subtree is empty, return a null node. - Otherwise, take out the last node
vof the post-order traversal, and then find the positionkofvin the in-order traversal using the hash tabled. Then the number of nodes in the left subtree isk - i, and the number of nodes in the right subtree isn - k + i - 1. - Recursively construct the left subtree
dfs(i, j, k - i)and the right subtreedfs(k + 1, j + k - i, n - k + i - 1), connect them to the root node, and finally return the root node.
The time complexity is O(n), and the space complexity is O(n). Here, n is the number of nodes in the binary tree.
Complexity Comparison
| Approach | Complexity |
|---|---|
| Recursive Approach using HashMap | Time Complexity: O(n), where n is the number of nodes. Each node is visited once. |
| Iterative Approach using Stack | Time Complexity: O(n), where n is the number of nodes. Every element is seen once. |
| Hash Table + Recursion | — |
Detailed Complexity Analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Recursive Divide and Conquer with HashMap | O(n) | O(n) | Best general solution. Clean recursion and constant-time inorder lookups. |
| Iterative Construction using Stack | O(n) | O(n) | Useful when avoiding recursion or when stack-based tree construction is preferred. |
Video Solution
L35. Construct the Binary Tree from Postorder and Inorder Traversal | C++ | Java • take U forward • 211,832 views views
Watch 9 more video solutions →Frequently Asked Questions
Is Construct Binary Tree from Inorder and Postorder Traversal easy or hard?
Construct Binary Tree from Inorder and Postorder Traversal Python/Java solution
How to solve Construct Binary Tree from Inorder and Postorder Traversal in O(n)?
What is the best approach for Construct Binary Tree from Inorder and Postorder Traversal?
Is Construct Binary Tree from Inorder and Postorder Traversal asked at Google/Amazon/Meta?
What data structure is used in Construct Binary Tree from Inorder and Postorder Traversal?
What is the time complexity of Construct Binary Tree from Inorder and Postorder Traversal?
Ready to solve this problem?
Practice Construct Binary Tree from Inorder and Postorder Traversal with our built-in code editor and test cases.
Practice on FleetCode