Web Crawler solution and explanation

5 more videos on this problem
 Web Crawler LeetCode 2020 07 15Vivek Sharma · 22:37 · 3K views
 1236. Web Crawler - Week 4/5 Leetcode March ChallengeProgramming Live with Larry · 10:37 · 1K views
 1236. Web CrawlerMuerde un zombie · 9:34 · 363 views
 Web Crawler | Leetcode 1236Debstuti Das · 10:36 · 331 views
 LeetCode 1236: Web CrawlerAlitaCode · 33:29 · 9 views
 LeetCode 1236: Web CrawlerAlitaCode · 29:44 · 8 views
The problem
Given a url startUrl and an interface HtmlParser, implement a web crawler to crawl all links that are under the same hostname as startUrl.
Return all urls obtained by your web crawler in any order.
Your crawler should:
- Start from the page:
startUrl - Call
HtmlParser.getUrls(url)to get all urls from a webpage of given url. - Do not crawl the same link twice.
- Explore only the links that are under the same hostname as
startUrl.
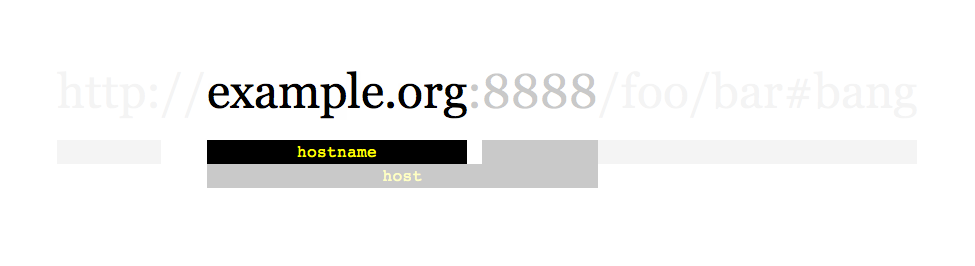
As shown in the example url above, the hostname is example.org. For simplicity sake, you may assume all urls use http protocol without any port specified. For example, the urls http://leetcode.com/problems and http://leetcode.com/contest are under the same hostname, while urls http://example.org/test and http://example.com/abc are not under the same hostname.
The HtmlParser interface is defined as such:
interface HtmlParser {
  // Return a list of all urls from a webpage of given url.
  public List<String> getUrls(String url);
}
Below are two examples explaining the functionality of the problem, for custom testing purposes you'll have three variables urls, edges and startUrl. Notice that you will only have access to startUrl in your code, while urls and edges are not directly accessible to you in code.
Note: Consider the same URL with the trailing slash "/" as a different URL. For example, "http://news.yahoo.com", and "http://news.yahoo.com/" are different urls.
Example 1:
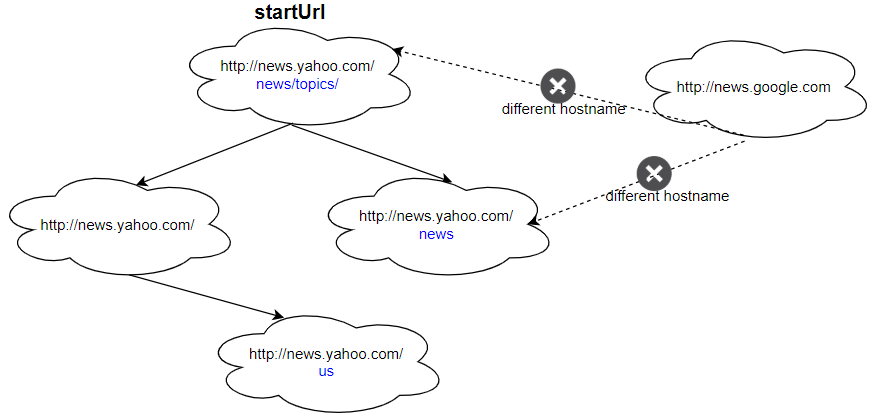
Input:
urls = [
  "http://news.yahoo.com",
  "http://news.yahoo.com/news",
  "http://news.yahoo.com/news/topics/",
  "http://news.google.com",
  "http://news.yahoo.com/us"
]
edges = [[2,0],[2,1],[3,2],[3,1],[0,4]]
startUrl = "http://news.yahoo.com/news/topics/"
Output: [
  "http://news.yahoo.com",
  "http://news.yahoo.com/news",
  "http://news.yahoo.com/news/topics/",
  "http://news.yahoo.com/us"
]
Example 2:
Input:
urls = [
  "http://news.yahoo.com",
  "http://news.yahoo.com/news",
  "http://news.yahoo.com/news/topics/",
  "http://news.google.com"
]
edges = [[0,2],[2,1],[3,2],[3,1],[3,0]]
startUrl = "http://news.google.com"
Output: ["http://news.google.com"]
Explanation: The startUrl links to all other pages that do not share the same hostname.
Constraints:
1 <= urls.length <= 10001 <= urls[i].length <= 300startUrlis one of theurls.- Hostname label must be from 1 to 63 characters long, including the dots, may contain only the ASCII letters from 'a' to 'z', digits from '0' to '9' and the hyphen-minus character ('-').
- The hostname may not start or end with the hyphen-minus character ('-').
- See: https://en.wikipedia.org/wiki/Hostname#Restrictions_on_valid_hostnames
- You may assume there're no duplicates in url library.
Approach overview
Problem Overview: Starting from startUrl, crawl every reachable page that belongs to the same hostname. The only way to discover links is through the provided HtmlParser.getUrls(url) API, so the problem becomes a graph traversal where URLs are nodes and hyperlinks are edges.
Approach 1: Breadth-First Search (BFS) Traversal (Time: O(N + E), Space: O(N))
Treat each URL as a node in a graph. Use a queue to perform breadth-first search starting from startUrl. Extract the hostname from the starting URL, then repeatedly dequeue a URL, call getUrls, and enqueue any discovered link that shares the same hostname and hasn’t been visited. A set tracks visited URLs to avoid infinite loops caused by cyclic links. BFS is straightforward and processes pages level by level, which mirrors how many real crawlers explore the web.
Approach 2: Depth-First Search (DFS) Traversal (Time: O(N + E), Space: O(N))
Another option is recursive or iterative depth-first search. Start with startUrl, store the hostname, and recursively visit every neighbor returned by getUrls. Before visiting a URL, check two conditions: it matches the original hostname and it hasn’t been visited before. DFS explores one branch fully before moving to another, which keeps the implementation concise with recursion and a visited set. From a complexity standpoint, DFS and BFS are identical because each valid URL is processed once.
Hostname filtering is the key constraint. Extract the domain portion of the starting URL and compare it with each discovered link. This ensures the crawler never leaves the target site even if external links appear in the page list. Since URL comparison and hostname parsing involve string operations, efficient substring checks keep overhead minimal.
Recommended for interviews: Either BFS or DFS is acceptable since both run in O(N + E) time and O(N) space. BFS with a queue and visited set is the most commonly expected approach because it clearly demonstrates graph traversal fundamentals and avoids recursion depth concerns. Mentioning DFS as an alternative shows strong understanding of traversal patterns.
Solution
# """
# This is HtmlParser's API interface.
# You should not implement it, or speculate about its implementation
# """
# class HtmlParser(object):
#    def getUrls(self, url):
#        """
#        :type url: str
#        :rtype List[str]
#        """


class Solution:
    def crawl(self, startUrl: str, htmlParser: 'HtmlParser') -> List[str]:
        def host(url):
            url = url[7:]
            return url.split('/')[0]

        def dfs(url):
            if url in ans:
                return
            ans.add(url)
            for next in htmlParser.getUrls(url):
                if host(url) == host(next):
                    dfs(next)

        ans = set()
        dfs(startUrl)
return list(ans)/**
* // This is the HtmlParser's API interface.
* // You should not implement it, or speculate about its implementation
* interface HtmlParser {
* public List<String> getUrls(String url) {}
* }
*/
class Solution {
private Set<String> ans;
public List<String> crawl(String startUrl, HtmlParser htmlParser) {
ans = new HashSet<>();
dfs(startUrl, htmlParser);
return new ArrayList<>(ans);
}
private void dfs(String url, HtmlParser htmlParser) {
if (ans.contains(url)) {
return;
}
ans.add(url);
for (String next : htmlParser.getUrls(url)) {
if (host(next).equals(host(url))) {
dfs(next, htmlParser);
}
}
}
private String host(String url) {
url = url.substring(7);
return url.split("/")[0];
}
}/**
* // This is the HtmlParser's API interface.
* // You should not implement it, or speculate about its implementation
* class HtmlParser {
* public:
* vector<string> getUrls(string url);
* };
*/
class Solution {
public:
vector<string> ans;
unordered_set<string> vis;
vector<string> crawl(string startUrl, HtmlParser htmlParser) {
dfs(startUrl, htmlParser);
return ans;
}
void dfs(string& url, HtmlParser& htmlParser) {
if (vis.count(url)) return;
vis.insert(url);
ans.push_back(url);
for (string next : htmlParser.getUrls(url))
if (host(url) == host(next))
dfs(next, htmlParser);
}
string host(string url) {
int i = 7;
string res;
for (; i < url.size(); ++i) {
if (url[i] == '/') break;
res += url[i];
}
return res;
}
};/**
* // This is HtmlParser's API interface.
* // You should not implement it, or speculate about its implementation
* type HtmlParser struct {
* func GetUrls(url string) []string {}
* }
*/
func crawl(startUrl string, htmlParser HtmlParser) []string {
var ans []string
vis := make(map[string]bool)
var dfs func(url string)
host := func(url string) string {
return strings.Split(url[7:], "/")[0]
}
dfs = func(url string) {
if vis[url] {
return
}
vis[url] = true
ans = append(ans, url)
for _, next := range htmlParser.GetUrls(url) {
if host(next) == host(url) {
dfs(next)
}
}
}
dfs(startUrl)
return ans
}Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Breadth-First Search (Queue) | O(N + E) | O(N) | General case. Preferred in interviews for clear level-by-level graph traversal. |
| Depth-First Search (Recursive/Stack) | O(N + E) | O(N) | Cleaner implementation with recursion when stack depth is manageable. |
Frequently asked questions
Is Web Crawler easy or hard?
Web Crawler is considered a Medium problem. The traversal logic is straightforward BFS or DFS, but candidates must correctly filter URLs by hostname and prevent revisiting nodes using a set.
Web Crawler Python/Java solution
Both Python and Java implementations use the same structure: extract the hostname, maintain a visited set, and traverse URLs using BFS or DFS. Python typically uses a deque and set, while Java uses Queue and HashSet with repeated calls to HtmlParser.getUrls.
How to solve Web Crawler in O(n)?
Use BFS or DFS with a hash set to track visited URLs. Start from startUrl, extract its hostname, and repeatedly fetch neighbors using HtmlParser.getUrls. Only add URLs with the same hostname and skip ones already visited, ensuring each page is processed exactly once.
What is the best approach for Web Crawler?
Graph traversal using BFS or DFS with a visited set is the best approach. Start from startUrl, extract its hostname, and only crawl URLs that share the same domain. Each discovered URL is processed once, giving O(N + E) time complexity where N is the number of pages and E is the number of links.
Is Web Crawler asked at Google/Amazon/Meta?
Web crawler style problems appear in interviews at companies like Google and Meta because they test graph traversal, URL parsing, and handling visited states. The problem models real distributed crawler systems but reduces it to BFS/DFS traversal over URLs.
What data structure is used in Web Crawler?
The core data structures are a queue (for BFS) or recursion/stack (for DFS) and a hash set to store visited URLs. String parsing is used to extract and compare hostnames so the crawler stays within the same domain.
What is the time complexity of Web Crawler?
The optimal solution runs in O(N + E) time. Each URL (node) is visited once and every hyperlink (edge) returned by HtmlParser.getUrls is processed once during traversal. Space complexity is O(N) for storing visited URLs and the BFS queue or DFS recursion stack.