
Leaf-Similar Trees - Solution & Explanation
Problem Statement
Consider all the leaves of a binary tree, from left to right order, the values of those leaves form a leaf value sequence.
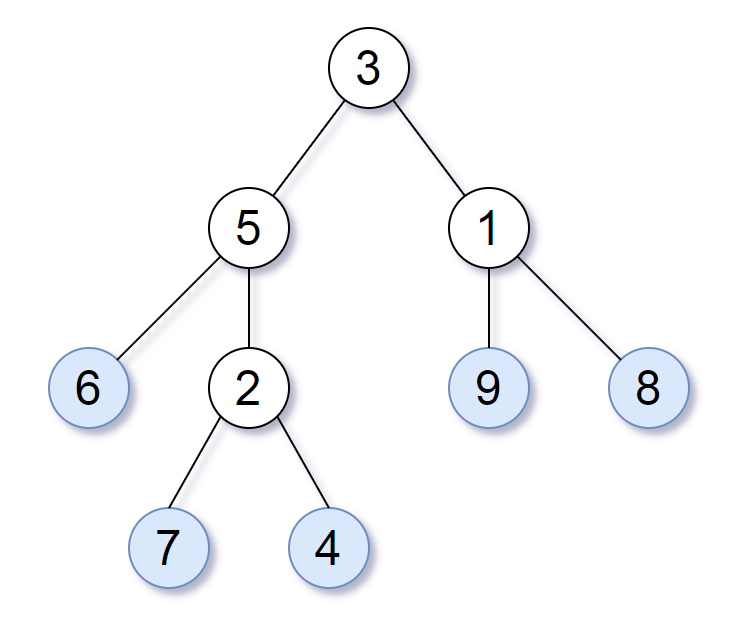
For example, in the given tree above, the leaf value sequence is (6, 7, 4, 9, 8).
Two binary trees are considered leaf-similar if their leaf value sequence is the same.
Return true if and only if the two given trees with head nodes root1 and root2 are leaf-similar.
Example 1:
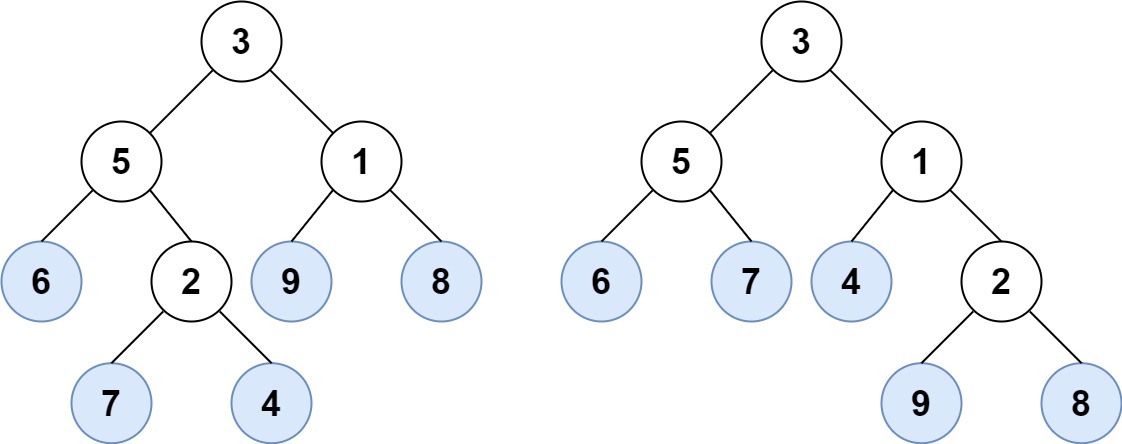
Input: root1 = [3,5,1,6,2,9,8,null,null,7,4], root2 = [3,5,1,6,7,4,2,null,null,null,null,null,null,9,8]
Output: true
Example 2:
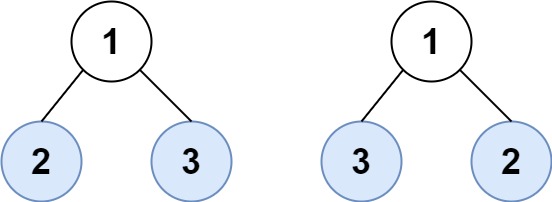
Input: root1 = [1,2,3], root2 = [1,3,2]
Output: false
Constraints:
- The number of nodes in each tree will be in the range
[1, 200]. - Both of the given trees will have values in the range
[0, 200].
Approach Overview
Problem Overview: Two binary trees are leaf-similar if the sequence of values from their leaf nodes (left to right) is identical. Traverse both trees, collect their leaf sequences, then compare the results. If the sequences match exactly, the trees are leaf-similar.
The key observation: only leaf nodes matter. Internal nodes and structure differences are irrelevant as long as the final leaf order is the same.
Approach 1: Recursive Depth-First Search (DFS) to Extract Leaf Sequences (Time: O(n + m), Space: O(h1 + h2))
Use a recursive depth-first search to traverse each tree and collect leaf values into an array. During traversal, check if the current node has no left and right children. If so, append its value to the sequence. Recursion naturally visits nodes in left-to-right order, which preserves the correct leaf ordering. After building both arrays, compare them element by element. Traversing each node once gives O(n + m) time where n and m are node counts of the two trees. Space complexity is O(h1 + h2) from recursion stacks, where h is the tree height.
This approach is clean and easy to reason about. Most interviewers expect this solution because it directly leverages recursion for tree traversal.
Approach 2: Iterative Depth-First Search (DFS) Using Stack (Time: O(n + m), Space: O(n + m))
An iterative DFS replaces recursion with an explicit stack. Push the root node onto the stack, repeatedly pop nodes, and push their children. When a node with no children is encountered, record its value in the leaf sequence. This approach simulates the traversal performed in recursive DFS but avoids recursion depth limits. After generating the sequences for both trees, compare them to determine if the trees are leaf-similar.
Iterative traversal is useful in environments where recursion depth might overflow or when you prefer explicit control over traversal order. The stack may temporarily hold many nodes, leading to O(n + m) auxiliary space in the worst case.
Both methods rely on standard tree traversal and operate directly on a binary tree. The only real task is correctly identifying leaf nodes and preserving their order.
Recommended for interviews: Recursive DFS is typically expected because it is concise and clearly expresses the traversal logic. Showing the recursive approach demonstrates comfort with tree recursion. The iterative stack version is still valuable if you want to avoid recursion or show deeper control over DFS mechanics.
Approach 1: Approach 1: Recursive Depth-First Search (DFS) to Extract Leaf Sequences
This approach involves using a recursive depth-first search (DFS) to traverse each binary tree and collect the leaf node values by diving into each sub-tree starting from the root node. We store the values of all leaf nodes from left to right in a list. After extracting the sequences from both trees, we compare these sequences to determine if the trees are leaf-similar.
We define a nested function dfs inside our main function to recursively traverse the binary tree. The dfs function returns a list of leaf node values by first checking if a node is null (in which case it returns an empty list), then it checks if the node is a leaf node (no left and right children), and if so, it returns a list containing the node's value. Otherwise, it recursively calls itself on the left and right children and concatenates their results. Lastly, we compare the two leaf sequences to decide if the trees are leaf-similar.
Complexity
Time Complexity: O(N) where N is the number of nodes in the tree, as we need to visit each node.
Space Complexity: O(H) where H is the height of the tree, due to the recursive stack.
Approach 2: Approach 2: Iterative Depth-First Search (DFS) Using Stack
This method employs an iterative version of depth-first search utilizing a stack to collect leaves of the tree. By substituting recursion with a stack, we manually handle tree traversal, but the core logic remains similar: traverse each tree, collect leaves, and compare leaf sequences.
Here, a Stack is used for both implementing the DFS traversal and collecting leaf node values iteratively. For leaf nodes, their values are added to a separate stack (list) leaves. By performing this for both root1 and root2, we get their leaf sequences, which are compared for equality at the end.
Code
Java
JavaScript
Complexity
Time Complexity: O(N), with N as the number of nodes in the tree, because every node is visited.
Space Complexity: O(H), where H is the height of the tree. This space is used by the stack during DFS traversal.
Approach 3: DFS
We can use Depth-First Search (DFS) to traverse the leaf nodes of the two trees, storing the values of the leaf nodes in two lists l_1 and l_2 respectively. Finally, we compare whether the two lists are equal.
Time complexity is O(n), and space complexity is O(n). Here, n is the number of nodes in the tree.
Complexity Comparison
| Approach | Complexity |
|---|---|
| Approach 1: Recursive Depth-First Search (DFS) to Extract Leaf Sequences | Time Complexity: O(N) where N is the number of nodes in the tree, as we need to visit each node. |
| Approach 2: Iterative Depth-First Search (DFS) Using Stack | Time Complexity: O(N), with N as the number of nodes in the tree, because every node is visited. |
| DFS | — |
Detailed Complexity Analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Recursive DFS to Collect Leaf Sequences | O(n + m) | O(h1 + h2) | Best general solution; simple recursion and minimal extra storage |
| Iterative DFS Using Stack | O(n + m) | O(n + m) | When recursion depth is a concern or iterative traversal is preferred |
Video Solution
Leaf-Similar Trees - Leetcode 872 - Python • NeetCodeIO • 20,475 views views
Watch 9 more video solutions →Frequently Asked Questions
Is Leaf-Similar Trees easy or hard?
Leaf-Similar Trees Python/Java solution
How to solve Leaf-Similar Trees in O(n)?
What is the best approach for Leaf-Similar Trees?
Is Leaf-Similar Trees asked at Google/Amazon/Meta?
What data structure is used in Leaf-Similar Trees?
What is the time complexity of Leaf-Similar Trees?
Ready to solve this problem?
Practice Leaf-Similar Trees with our built-in code editor and test cases.
Practice on FleetCode