Find if Path Exists in Graph solution and explanation
 Google

9 more videos on this problem
 Find if Path Exists in Graph - Leetcode 1971 - Graphs (Python)Greg Hogg · 12:20 · 29K views
 Find if Path Exists in Graph | Easiest Explanation | Microsoft | Leetcode 1971 | codestorywithMIKcodestorywithMIK · 24:40 · 17K views
 Find if Path Exists in Graph | LeetCode 1971 | EnglishCodeClips with Abhishek Ranjan · 13:18 · 7K views
 1971. Find if Path Exists in Graph | DFS | Connected Components | DSU | Union FindAryan Mittal · 13:27 · 4K views
 Find If Path Exists in Graph - LeetCode 1971 - JavaScriptAlgoJS · 6:48 · 3K views
 Find if Path Exists in Graph | Leetcode 1971 | Amazon Google Facebook interview questionSuper Lazy Coder · 12:16 · 489 views
 Daily Leetcode #993: Dec 19, 2022 - 1971. Find if Path Exists in GraphProgramming Live with Larry · 7:10 · 462 views
 LeetCode 1971 - Find if Path Exists in Graph - JavaAlpha-Code · 14:53 · 444 views
 Leetcode 1971 Find if path exists in a graph | Data structures & Algorithms #coding #datastructuresLearn with Shubhaw · 9:55 · 399 views
 1971. Find if Path Exists in Graph | JAVA |LeetCode solutionsde1prep · 16:00 · 285 views
The problem
There is a bi-directional graph with n vertices, where each vertex is labeled from 0 to n - 1 (inclusive). The edges in the graph are represented as a 2D integer array edges, where each edges[i] = [ui, vi] denotes a bi-directional edge between vertex ui and vertex vi. Every vertex pair is connected by at most one edge, and no vertex has an edge to itself.
You want to determine if there is a valid path that exists from vertex source to vertex destination.
Given edges and the integers n, source, and destination, return true if there is a valid path from source to destination, or false otherwise.
Example 1:
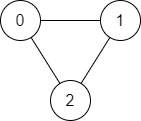
Input: n = 3, edges = [[0,1],[1,2],[2,0]], source = 0, destination = 2
Output: true
Explanation: There are two paths from vertex 0 to vertex 2:
- 0 → 1 → 2
- 0 → 2
Example 2:
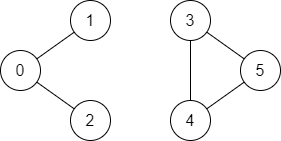
Input: n = 6, edges = [[0,1],[0,2],[3,5],[5,4],[4,3]], source = 0, destination = 5
Output: false
Explanation: There is no path from vertex 0 to vertex 5.
Constraints:
1 <= n <= 2 * 1050 <= edges.length <= 2 * 105edges[i].length == 20 <= ui, vi <= n - 1ui != vi0 <= source, destination <= n - 1- There are no duplicate edges.
- There are no self edges.
Approach overview
Problem Overview: You are given an undirected graph with n nodes and a list of edges. The task is simple: determine whether a valid path exists between a given source node and a destination node. In other words, check if the two nodes belong to the same connected component in the graph.
Approach 1: Depth-First Search (DFS) Traversal (Time: O(V + E), Space: O(V))
The most direct solution treats the graph as an adjacency list and performs a traversal starting from the source. Using Depth-First Search, you recursively explore all neighbors of each node until either the destination is found or all reachable nodes are visited. A visited array prevents revisiting nodes and getting stuck in cycles. If the traversal ever reaches the destination, a path exists.
This works because DFS explores every vertex reachable from the starting node. If the destination belongs to the same connected component, DFS will eventually reach it. Building the adjacency list takes O(E) time, and the traversal visits each node and edge at most once. This approach is intuitive and commonly used for connectivity checks in a graph.
Many implementations also use Breadth-First Search instead of DFS. BFS uses a queue instead of recursion but has the same time complexity O(V + E) and space complexity O(V). Both approaches work equally well for reachability problems.
Approach 2: Union-Find (Disjoint Set Union) (Time: O(E · α(V)), Space: O(V))
Union-Find models the graph as a collection of connected components. Initially, each node belongs to its own set. For every edge (u, v), perform a union operation to merge the sets containing those nodes. After processing all edges, nodes that are connected by any path will belong to the same root set.
To check if a path exists, simply compare the roots of source and destination. If they share the same representative parent, they are connected. With path compression and union by rank, each operation runs in nearly constant time, represented as the inverse Ackermann function α(V).
This approach avoids explicit traversal and is extremely efficient when you need to process many connectivity queries or build components incrementally. It’s a classic use case of the Union-Find data structure.
Recommended for interviews: DFS or BFS is typically the expected solution because it directly demonstrates graph traversal skills and understanding of connected components. Union-Find is also highly valued, especially if the interviewer wants to test knowledge of disjoint-set data structures. Showing DFS first proves you understand graph traversal fundamentals, while mentioning Union-Find demonstrates deeper algorithmic knowledge.
Approach 1: Depth First Search (DFS)
The DFS approach involves exploring as far as possible along each branch before backing up. Start from the source vertex and explore each adjacent vertex, marking visited vertices. If you reach the destination during your exploration, return true. If no path to destination is found by the time all possible vertices are visited, return false.
def validPath(n, edges, source, destination):
    if source == destination:
        return True

    from collections import defaultdict

    graph = defaultdict(list)
    for u, v in edges:
        graph[u].append(v)
        graph[v].append(u)

    visited = set()

    def dfs(node):
        if node == destination:
            return True
        if node in visited:
            return False

        visited.add(node)

        for neighbor in graph[node]:
            if dfs(neighbor):
                return True

        return False

return dfs(source)import java.util.ArrayList;
import java.util.List;
class Solution {
public boolean validPath(int n, int[][] edges, int source, int destination) {
if (source == destination) return true;
List<List<Integer>> adjList = new ArrayList<>();
for (int i = 0; i < n; i++) {
adjList.add(new ArrayList<>());
}
for (int[] edge : edges) {
adjList.get(edge[0]).add(edge[1]);
adjList.get(edge[1]).add(edge[0]);
}
boolean[] visited = new boolean[n];
return dfs(source, destination, adjList, visited);
}
private boolean dfs(int node, int destination, List<List<Integer>> adjList, boolean[] visited) {
if (node == destination) return true;
if (visited[node]) return false;
visited[node] = true;
for (int neighbor : adjList.get(node)) {
if (dfs(neighbor, destination, adjList, visited)) return true;
}
return false;
}
}#include <vector>
using namespace std;
void dfs(int node, vector<vector<int>>& adjList, vector<bool>& visited) {
if (visited[node]) return;
visited[node] = true;
for (int neighbor : adjList[node]) {
dfs(neighbor, adjList, visited);
}
}
bool validPath(int n, vector<vector<int>>& edges, int source, int destination) {
if (source == destination) return true;
vector<vector<int>> adjList(n);
for (auto& edge : edges) {
adjList[edge[0]].push_back(edge[1]);
adjList[edge[1]].push_back(edge[0]);
}
vector<bool> visited(n, false);
dfs(source, adjList, visited);
return visited[destination];
}var validPath = function(n, edges, source, destination) {
if (source === destination) return true;
const adjList = Array.from({length: n}, () => []);
for (let [u, v] of edges) {
adjList[u].push(v);
adjList[v].push(u);
}
const visited = new Array(n).fill(false);
const dfs = (node) => {
if (node === destination) return true;
if (visited[node]) return false;
visited[node] = true;
for (let neighbor of adjList[node]) {
if (dfs(neighbor)) return true;
}
return false;
}
return dfs(source);
};#include <stdbool.h>
#include <stdlib.h>
void dfs(int node, int **adjList, int *adjListSize, bool *visited) {
visited[node] = true;
for (int i = 0; i < adjListSize[node]; i++) {
int neighbor = adjList[node][i];
if (!visited[neighbor]) {
dfs(neighbor, adjList, adjListSize, visited);
}
}
}
bool validPath(int n, int **edges, int edgesSize, int *edgesColSize, int source, int destination) {
if (source == destination) return true;
// Create adjacency list
int *adjListSize = calloc(n, sizeof(int));
int **adjList = malloc(n * sizeof(int *));
for (int i = 0; i < n; i++) {
adjList[i] = malloc(0);
}
for (int i = 0; i < edgesSize; i++) {
int u = edges[i][0];
int v = edges[i][1];
adjListSize[u]++;
adjListSize[v]++;
adjList[u] = realloc(adjList[u], adjListSize[u] * sizeof(int));
adjList[v] = realloc(adjList[v], adjListSize[v] * sizeof(int));
adjList[u][adjListSize[u] - 1] = v;
adjList[v][adjListSize[v] - 1] = u;
}
bool *visited = calloc(n, sizeof(bool));
dfs(source, adjList, adjListSize, visited);
bool result = visited[destination];
// Free memory
for (int i = 0; i < n; i++) {
free(adjList[i]);
}
free(adjList);
free(adjListSize);
free(visited);
return result;
}using System;
using System.Collections.Generic;
public class Solution {
public bool ValidPath(int n, int[][] edges, int source, int destination) {
if (source == destination) return true;
var adjList = new List<int>[n];
for (var i = 0; i < n; i++) {
adjList[i] = new List<int>();
}
foreach (var edge in edges) {
adjList[edge[0]].Add(edge[1]);
adjList[edge[1]].Add(edge[0]);
}
var visited = new bool[n];
return Dfs(source, destination, adjList, visited);
}
private bool Dfs(int current, int destination, List<int>[] adjList, bool[] visited) {
if (current == destination) return true;
if (visited[current]) return false;
visited[current] = true;
foreach (var neighbor in adjList[current]) {
if (Dfs(neighbor, destination, adjList, visited)) return true;
}
return false;
}
}This Python implementation uses a recursive depth-first search, utilizing a set to track visited nodes to avoid cycles and repeated visits. The adjacency list structure is used for graph representation. The dfs function attempts to find a path from source to destination, returning True if successful.
Time Complexity: O(V + E), where V is the total number of vertices, and E is the total number of edges.
Space Complexity: O(V + E) to store the graph and visited state.
Approach 2: Union-Find (Disjoint Set Union, DSU)
The Union-Find approach is effective for problems involving connectivity checks among different components. This data structure helps efficiently merge sets of connected components and determine whether two vertices are in the same connected component by checking if they share the same root. Initialize each vertex as its own component, then loop through the edges to perform union operations, connecting the components. Finally, check if the source and destination vertices belong to the same component.
class UnionFind:
    def __init__(self, size):
        self.parent = list(range(size))
        self.rank = [0] * size

    def find(self, node):
        if self.parent[node] != node:
            self.parent[node] = self.find(self.parent[node])
        return self.parent[node]

    def union(self, u, v):
        rootU = self.find(u)
        rootV = self.find(v)
        if rootU != rootV:
            if self.rank[rootU] > self.rank[rootV]:
                self.parent[rootV] = rootU
            elif self.rank[rootU] < self.rank[rootV]:
                self.parent[rootU] = rootV
            else:
                self.parent[rootV] = rootU
                self.rank[rootU] += 1


def validPath(n, edges, source, destination):
    uf = UnionFind(n)
    for u, v in edges:
        uf.union(u, v)
return uf.find(source) == uf.find(destination)class UnionFind {
private int[] parent, rank;
public UnionFind(int n) {
parent = new int[n];
rank = new int[n];
for (int i = 0; i < n; i++) {
parent[i] = i;
rank[i] = 0;
}
}
public int find(int node) {
if (parent[node] != node) {
parent[node] = find(parent[node]);
}
return parent[node];
}
public void union(int u, int v) {
int rootU = find(u);
int rootV = find(v);
if (rootU != rootV) {
if (rank[rootU] > rank[rootV]) {
parent[rootV] = rootU;
} else if (rank[rootU] < rank[rootV]) {
parent[rootU] = rootV;
} else {
parent[rootV] = rootU;
rank[rootU]++;
}
}
}
}
public class Solution {
public boolean validPath(int n, int[][] edges, int source, int destination) {
UnionFind uf = new UnionFind(n);
for (int[] edge : edges) {
uf.union(edge[0], edge[1]);
}
return uf.find(source) == uf.find(destination);
}
}#include <vector>
#include <numeric>
using namespace std;
class UnionFind {
vector<int> parent, rank;
public:
UnionFind(int n) {
rank = vector<int>(n, 0);
parent = vector<int>(n);
iota(parent.begin(), parent.end(), 0);
}
int find(int node) {
if (parent[node] != node) {
parent[node] = find(parent[node]);
}
return parent[node];
}
void unionSet(int u, int v) {
int pu = find(u);
int pv = find(v);
if (rank[pu] > rank[pv]) {
parent[pv] = pu;
} else if (rank[pu] < rank[pv]) {
parent[pu] = pv;
} else {
parent[pu] = pv;
rank[pv]++;
}
}
};
bool validPath(int n, vector<vector<int>>& edges, int source, int destination) {
UnionFind uf(n);
for (const auto& edge : edges) {
uf.unionSet(edge[0], edge[1]);
}
return uf.find(source) == uf.find(destination);
}class UnionFind {
constructor(size) {
this.parent = Array.from({ length: size }, (_, index) => index);
this.rank = Array(size).fill(0);
}
find(node) {
if (this.parent[node] !== node) {
this.parent[node] = this.find(this.parent[node]);
}
return this.parent[node];
}
union(u, v) {
const rootU = this.find(u);
const rootV = this.find(v);
if (rootU !== rootV) {
if (this.rank[rootU] > this.rank[rootV]) {
this.parent[rootV] = rootU;
} else if (this.rank[rootU] < this.rank[rootV]) {
this.parent[rootU] = rootV;
} else {
this.parent[rootV] = rootU;
this.rank[rootU]++;
}
}
}
}
var validPath = function(n, edges, source, destination) {
const uf = new UnionFind(n);
for (let [u, v] of edges) {
uf.union(u, v);
}
return uf.find(source) === uf.find(destination);
};#include <stdbool.h>
int find(int parent[], int i) {
if (parent[i] == i) return i;
return parent[i] = find(parent, parent[i]);
}
void unionSets(int parent[], int rank[], int x, int y) {
int xRoot = find(parent, x);
int yRoot = find(parent, y);
if (xRoot != yRoot) {
if (rank[xRoot] < rank[yRoot]) {
parent[xRoot] = yRoot;
} else if (rank[xRoot] > rank[yRoot]) {
parent[yRoot] = xRoot;
} else {
parent[yRoot] = xRoot;
rank[xRoot]++;
}
}
}
bool validPath(int n, int **edges, int edgesSize, int *edgesColSize, int source, int destination) {
int *parent = malloc(n * sizeof(int));
int *rank = calloc(n, sizeof(int));
for (int i = 0; i < n; i++) {
parent[i] = i;
}
for (int i = 0; i < edgesSize; i++) {
unionSets(parent, rank, edges[i][0], edges[i][1]);
}
bool result = find(parent, source) == find(parent, destination);
free(parent);
free(rank);
return result;
}public class UnionFind {
private int[] parent;
private int[] rank;
public UnionFind(int size) {
parent = new int[size];
rank = new int[size];
for (int i = 0; i < size; i++) {
parent[i] = i;
rank[i] = 0;
}
}
public int Find(int x) {
if (parent[x] != x) {
parent[x] = Find(parent[x]);
}
return parent[x];
}
public void Union(int x, int y) {
int rootX = Find(x);
int rootY = Find(y);
if (rootX != rootY) {
if (rank[rootX] > rank[rootY]) {
parent[rootY] = rootX;
} else if (rank[rootX] < rank[rootY]) {
parent[rootX] = rootY;
} else {
parent[rootY] = rootX;
rank[rootX]++;
}
}
}
}
public class Solution {
public bool ValidPath(int n, int[][] edges, int source, int destination) {
UnionFind uf = new UnionFind(n);
foreach (var edge in edges) {
uf.Union(edge[0], edge[1]);
}
return uf.Find(source) == uf.Find(destination);
}
}This implementation in Python constructs a Union-Find set to help manage disjoint connectivity among graph nodes. It applies path compression in the `find` method, improving search efficiency, and utilizes union by rank for optimal tree height. This approach efficiently manages connectivity status, ensuring two points share connectivity status determined by their root nodes.
Time Complexity: O(Eα(V)), with α representing the Inverse Ackermann function.
Space Complexity: O(V), based on parent and rank structures.
Approach 3: DFS
We first convert edges into an adjacency list g, then use DFS to determine whether there is a path from source to destination.
During the process, we use an array vis to record the vertices that have already been visited to avoid revisiting them.
The time complexity is O(n + m), and the space complexity is O(n + m). Here, n and m are the number of nodes and edges, respectively.
function validPath(n: number, edges: number[][], source: number, destination: number): boolean {
    const g: number[][] = Array.from({ length: n }, () => []);
    for (const [u, v] of edges) {
        g[u].push(v);
        g[v].push(u);
    }
    const vis = new Set<number>();
    const dfs = (i: number) => {
        if (i === destination) {
            return true;
        }
        if (vis.has(i)) {
            return false;
        }
        vis.add(i);
        return g[i].some(dfs);
    };
    return dfs(source);
}func validPath(n int, edges [][]int, source int, destination int) bool {
vis := make([]bool, n)
g := make([][]int, n)
for _, e := range edges {
u, v := e[0], e[1]
g[u] = append(g[u], v)
g[v] = append(g[v], u)
}
var dfs func(int) bool
dfs = func(i int) bool {
if i == destination {
return true
}
vis[i] = true
for _, j := range g[i] {
if !vis[j] && dfs(j) {
return true
}
}
return false
}
return dfs(source)
}impl Solution {
pub fn valid_path(n: i32, edges: Vec<Vec<i32>>, source: i32, destination: i32) -> bool {
let n = n as usize;
let source = source as usize;
let destination = destination as usize;
let mut g = vec![Vec::new(); n];
let mut vis = vec![false; n];
for e in edges {
let u = e[0] as usize;
let v = e[1] as usize;
g[u].push(v);
g[v].push(u);
}
fn dfs(g: &Vec<Vec<usize>>, vis: &mut Vec<bool>, i: usize, destination: usize) -> bool {
if i == destination {
return true;
}
vis[i] = true;
for &j in &g[i] {
if !vis[j] && dfs(g, vis, j, destination) {
return true;
}
}
false
}
dfs(&g, &mut vis, source, destination)
}
}Approach 4: BFS
We can also use BFS to determine whether there is a path from source to destination.
Specifically, we define a queue q, initially adding source to the queue. Additionally, we use a set vis to record the vertices that have already been visited to avoid revisiting them.
Next, we continuously take vertices i from the queue. If i = destination, it means there is a path from source to destination, and we return true. Otherwise, we traverse all adjacent vertices j of i. If j has not been visited, we add j to the queue q and mark j as visited.
Finally, if the queue is empty, it means there is no path from source to destination, and we return false.
The time complexity is O(n + m), and the space complexity is O(n + m). Here, n and m are the number of nodes and edges, respectively.
function validPath(n: number, edges: number[][], source: number, destination: number): boolean {
    const g: number[][] = Array.from({ length: n }, () => []);
    for (const [u, v] of edges) {
        g[u].push(v);
        g[v].push(u);
    }
    const vis = new Set<number>([source]);
    const q = [source];
    while (q.length) {
        const i = q.pop()!;
        if (i === destination) {
            return true;
        }
        for (const j of g[i]) {
            if (!vis.has(j)) {
                vis.add(j);
                q.push(j);
            }
        }
    }
    return false;
}func validPath(n int, edges [][]int, source int, destination int) bool {
g := make([][]int, n)
for _, e := range edges {
u, v := e[0], e[1]
g[u] = append(g[u], v)
g[v] = append(g[v], u)
}
q := []int{source}
vis := make([]bool, n)
vis[source] = true
for len(q) > 0 {
i := q[0]
q = q[1:]
if i == destination {
return true
}
for _, j := range g[i] {
if !vis[j] {
vis[j] = true
q = append(q, j)
}
}
}
return false
}use std::collections::{HashSet, VecDeque};
impl Solution {
pub fn valid_path(n: i32, edges: Vec<Vec<i32>>, source: i32, destination: i32) -> bool {
let n = n as usize;
let source = source as usize;
let destination = destination as usize;
let mut g = vec![Vec::new(); n];
for edge in edges {
let u = edge[0] as usize;
let v = edge[1] as usize;
g[u].push(v);
g[v].push(u);
}
let mut q = VecDeque::new();
let mut vis = HashSet::new();
q.push_back(source);
vis.insert(source);
while let Some(i) = q.pop_front() {
if i == destination {
return true;
}
for &j in &g[i] {
if !vis.contains(&j) {
vis.insert(j);
q.push_back(j);
}
}
}
false
}
}Approach 5: Union-Find
Union-Find is a tree-like data structure that, as the name suggests, is used to handle some disjoint set merge and query problems. It supports two operations:
- Find: Determine which subset an element belongs to. The time complexity of a single operation is
O(\alpha(n)). - Union: Merge two subsets into one set. The time complexity of a single operation is
O(\alpha(n)).
For this problem, we can use the Union-Find set to merge the edges in edges, and then determine whether source and destination are in the same set.
The time complexity is O(n log n + m) or O(n \alpha(n) + m), and the space complexity is O(n). Where n and m are the number of nodes and edges, respectively.
class UnionFind {
    p: number[];
    size: number[];
    constructor(n: number) {
        this.p = Array(n)
            .fill(0)
            .map((_, i) => i);
        this.size = Array(n).fill(1);
    }

    find(x: number): number {
        if (this.p[x] !== x) {
            this.p[x] = this.find(this.p[x]);
        }
        return this.p[x];
    }

    union(a: number, b: number): boolean {
        const [pa, pb] = [this.find(a), this.find(b)];
        if (pa === pb) {
            return false;
        }
        if (this.size[pa] > this.size[pb]) {
            this.p[pb] = pa;
            this.size[pa] += this.size[pb];
        } else {
            this.p[pa] = pb;
            this.size[pb] += this.size[pa];
        }
        return true;
    }
}

function validPath(n: number, edges: number[][], source: number, destination: number): boolean {
    const uf = new UnionFind(n);
    edges.forEach(([u, v]) => uf.union(u, v));
    return uf.find(source) === uf.find(destination);
}type unionFind struct {
p, size []int
}
func newUnionFind(n int) *unionFind {
p := make([]int, n)
size := make([]int, n)
for i := range p {
p[i] = i
size[i] = 1
}
return &unionFind{p, size}
}
func (uf *unionFind) find(x int) int {
if uf.p[x] != x {
uf.p[x] = uf.find(uf.p[x])
}
return uf.p[x]
}
func (uf *unionFind) union(a, b int) bool {
pa, pb := uf.find(a), uf.find(b)
if pa == pb {
return false
}
if uf.size[pa] > uf.size[pb] {
uf.p[pb] = pa
uf.size[pa] += uf.size[pb]
} else {
uf.p[pa] = pb
uf.size[pb] += uf.size[pa]
}
return true
}
func validPath(n int, edges [][]int, source int, destination int) bool {
uf := newUnionFind(n)
for _, e := range edges {
uf.union(e[0], e[1])
}
return uf.find(source) == uf.find(destination)
}struct UnionFind {
p: Vec<usize>,
size: Vec<usize>,
}
impl UnionFind {
fn new(n: usize) -> Self {
let p = (0..n).collect();
let size = vec![1; n];
UnionFind { p, size }
}
fn find(&mut self, x: usize) -> usize {
if self.p[x] != x {
self.p[x] = self.find(self.p[x]);
}
self.p[x]
}
fn union(&mut self, a: usize, b: usize) {
let pa = self.find(a);
let pb = self.find(b);
if pa != pb {
if self.size[pa] > self.size[pb] {
self.p[pb] = pa;
self.size[pa] += self.size[pb];
} else {
self.p[pa] = pb;
self.size[pb] += self.size[pa];
}
}
}
}
impl Solution {
pub fn valid_path(n: i32, edges: Vec<Vec<i32>>, source: i32, destination: i32) -> bool {
let n = n as usize;
let mut uf = UnionFind::new(n);
for e in edges {
let u = e[0] as usize;
let v = e[1] as usize;
uf.union(u, v);
}
uf.find(source as usize) == uf.find(destination as usize)
}
}Complexity comparison
| Approach | Complexity |
|---|---|
| Depth First Search (DFS) | Time Complexity: O(V + E), where V is the total number of vertices, and E is the total number of edges. Space Complexity: O(V + E) to store the graph and visited state. |
| Union-Find (Disjoint Set Union, DSU) | Time Complexity: O(Eα(V)), with α representing the Inverse Ackermann function. Space Complexity: O(V), based on parent and rank structures. |
| DFS | – |
| BFS | – |
| Union-Find | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Depth-First Search (DFS) | O(V + E) | O(V) | Best general approach for checking connectivity using graph traversal |
| Breadth-First Search (BFS) | O(V + E) | O(V) | Preferred when iterative traversal with a queue is easier than recursion |
| Union-Find (Disjoint Set Union) | O(E · α(V)) | O(V) | Efficient for connectivity checks when processing many edges or multiple queries |
Frequently asked questions
Is Find if Path Exists in Graph easy or hard?
Find if Path Exists in Graph is categorized as an Easy problem because it focuses on basic graph traversal. Candidates only need to understand DFS, BFS, or Union-Find to check connectivity between two nodes. The challenge mainly involves building the adjacency list and handling visited nodes correctly.
Find if Path Exists in Graph Python/Java solution
In Python or Java, build an adjacency list using lists or hash maps and perform DFS or BFS starting from the source node. Track visited nodes to prevent revisiting. If the traversal reaches the destination, return true; otherwise return false after exploring all reachable nodes.
How to solve Find if Path Exists in Graph in O(V + E)?
Build an adjacency list from the edge list, then run DFS or BFS starting from the source node. Mark visited nodes to avoid cycles and repeatedly explore neighbors. If the destination node is reached during traversal, return true; otherwise return false after the search finishes.
What is the best approach for Find if Path Exists in Graph?
Depth-First Search (DFS) or Breadth-First Search (BFS) is the most common approach because it directly explores all nodes reachable from the source. Both run in O(V + E) time and O(V) space using an adjacency list. Union-Find is another efficient option that checks whether the source and destination belong to the same connected component.
Is Find if Path Exists in Graph asked at Google/Amazon/Meta?
Graph connectivity problems like this appear frequently in technical interviews at companies such as Amazon, Google, and Meta. Interviewers often use variations that test understanding of DFS, BFS, connected components, or Union-Find data structures.
What data structure is used in Find if Path Exists in Graph?
The problem typically uses an adjacency list to represent the graph and either a recursion stack or queue for traversal. A visited set or boolean array tracks explored nodes. In the alternative approach, the Union-Find (Disjoint Set Union) structure manages connected components.
What is the time complexity of Find if Path Exists in Graph?
The standard graph traversal solution using DFS or BFS runs in O(V + E) time, where V is the number of vertices and E is the number of edges. Each node and edge is visited at most once during traversal. The Union-Find approach runs in O(E · α(V)) time with path compression, which is effectively near constant per operation.