Checking Existence of Edge Length Limited Paths solution and explanation
 Google

9 more videos on this problem
 Checking Existence of Edge Length Limited Paths | Leetcode - 1697 | DSU | GOOGLE | ExplanationcodestorywithMIK · 32:17 · 9K views
 Checking Existence of Edge Length Limited Paths || Explain Union Find || Disjoint Set Union DSUAryan Mittal · 29:46 · 6K views
 LeetCode 1697. Checking Existence of Edge Length Limited PathsHappy Coding · 22:46 · 3K views
 1697. Checking Existence of Edge Length Limited Paths DSU | LeetCode Daily Challenge | LeetCode POTDDeep Tech · 16:26 · 1K views
 【每日一题】1697. Checking Existence of Edge Length Limited Paths, 12/21/2020Huifeng Guan · 18:11 · 905 views
 Checking Existence of Edge Length Limited Paths | Google Interview Questions | LeetCode ExperiencesScaleUp with SK · 25:18 · 825 views
 1697. Checking Existence of Edge Length Limited Paths (Leetcode Hard)Programming Live with Larry · 27:50 · 641 views
 1697 || Checking Existence of Edge Length Limited Paths || C++ || Leetcode Daily ChallengeCodeFreaks · 19:00 · 579 views
 Leetcode 1697. Checking Existence of Edge Length Limited Paths [Solution]Elite Code · 25:17 · 516 views
 Daily Leetcode #1124: Apr 29, 2023 - 1697. Checking Existence of Edge Length Limited PathsProgramming Live with Larry · 20:56 · 475 views
The problem
An undirected graph of n nodes is defined by edgeList, where edgeList[i] = [ui, vi, disi] denotes an edge between nodes ui and vi with distance disi. Note that there may be multiple edges between two nodes.
Given an array queries, where queries[j] = [pj, qj, limitj], your task is to determine for each queries[j] whether there is a path between pj and qj such that each edge on the path has a distance strictly less than limitj .
Return a boolean array answer, where answer.length == queries.length and the jth value of answer is true if there is a path for queries[j] is true, and false otherwise.
Example 1:
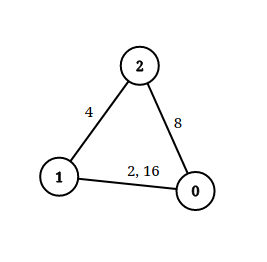
Input: n = 3, edgeList = [[0,1,2],[1,2,4],[2,0,8],[1,0,16]], queries = [[0,1,2],[0,2,5]]
Output: [false,true]
Explanation: The above figure shows the given graph. Note that there are two overlapping edges between 0 and 1 with distances 2 and 16.
For the first query, between 0 and 1 there is no path where each distance is less than 2, thus we return false for this query.
For the second query, there is a path (0 -> 1 -> 2) of two edges with distances less than 5, thus we return true for this query.
Example 2:
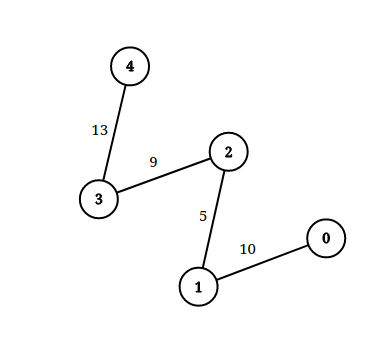
Input: n = 5, edgeList = [[0,1,10],[1,2,5],[2,3,9],[3,4,13]], queries = [[0,4,14],[1,4,13]]
Output: [true,false]
Explanation: The above figure shows the given graph.
Constraints:
2 <= n <= 1051 <= edgeList.length, queries.length <= 105edgeList[i].length == 3queries[j].length == 30 <= ui, vi, pj, qj <= n - 1ui != vipj != qj1 <= disi, limitj <= 109- There may be multiple edges between two nodes.
Approach overview
Problem Overview: You are given an undirected weighted graph and several queries. Each query asks whether two nodes can be connected using only edges whose weight is strictly less than a given limit. For every query, return true if such a path exists, otherwise false.
Approach 1: Union-Find with Sorting (O((E + Q) log E) time, O(N) space)
The key idea is to process queries offline by sorting both the edges and the queries by edge weight limit. Instead of checking each query independently, sort the edgeList by weight and sort queries by their limit. Then gradually add edges into a Union-Find structure while their weights remain below the current query’s limit. Once all eligible edges are merged, simply check if the two query nodes belong to the same connected component. This works because connectivity only increases as you add edges in increasing weight order. The Union Find structure provides nearly constant-time find and union operations with path compression and union by rank. Sorting drives the overall complexity, giving O((E + Q) log E) time and O(N) space.
Approach 2: Kruskal's Algorithm Modification (O((E + Q) log E) time, O(N) space)
This approach interprets the problem through the lens of minimum spanning tree construction. Kruskal’s algorithm processes edges in ascending order of weight and connects components using a Union-Find. For each query limit, you effectively simulate running Kruskal until the edge weight reaches that limit. All edges smaller than the limit are merged into the structure. After those merges, checking connectivity between the two query nodes answers the query instantly. Conceptually this is identical to the previous method but framed as a partial MST build for each query threshold. This perspective is helpful if you already understand Kruskal’s algorithm for graph connectivity problems. Sorting the edges and queries ensures efficient processing, while the disjoint set structure maintains components.
Both approaches rely heavily on ordering edges by weight. Efficient preprocessing with sorting ensures edges are added exactly once and queries are answered without repeated graph traversal.
Recommended for interviews: The Union-Find with sorted queries approach is what most interviewers expect. It shows you recognize that queries can be processed offline and that dynamic connectivity can be handled efficiently with a disjoint set. Explaining the brute-force idea (running a constrained BFS/DFS per query) demonstrates baseline understanding, but switching to the sorted Union-Find solution shows strong algorithmic insight.
Approach 1: Union-Find with Sorting
This approach is based on using a Union-Find (Disjoint Set Union) data structure, which allows us to efficiently keep track of connected components in the graph. The strategy involves sorting both the edges and the queries based on the edge weights and the query limits, respectively. By processing these sorted lists, we can incrementally add edges to the Union-Find structure and query the connectivity status effectively.
class UnionFind:
    def __init__(self, size):
        self.parent = list(range(size))
        self.rank = [1] * size

    def find(self, u):
        if u != self.parent[u]:
            self.parent[u] = self.find(self.parent[u])
        return self.parent[u]

    def union(self, u, v):
        rootU = self.find(u)
        rootV = self.find(v)
        if rootU != rootV:
            if self.rank[rootU] > self.rank[rootV]:
                self.parent[rootV] = rootU
            elif self.rank[rootU] < self.rank[rootV]:
                self.parent[rootU] = rootV
            else:
                self.parent[rootV] = rootU
                self.rank[rootU] += 1

    def connected(self, u, v):
        return self.find(u) == self.find(v)


def edgeLengthLimitedPaths(n, edgeList, queries):
    uf = UnionFind(n)
    answers = [False] * len(queries)
    edgeList.sort(key=lambda x: x[2])
    sorted_queries = sorted(enumerate(queries), key=lambda x: x[1][2])

    edgeIndex = 0
    for qIndex, (p, q, limit) in sorted_queries:
        while edgeIndex < len(edgeList) and edgeList[edgeIndex][2] < limit:
            uf.union(edgeList[edgeIndex][0], edgeList[edgeIndex][1])
            edgeIndex += 1
        answers[qIndex] = uf.connected(p, q)

return answersimport java.util.*;
class UnionFind {
int[] parent, rank;
public UnionFind(int size) {
parent = new int[size];
rank = new int[size];
for (int i = 0; i < size; i++) {
parent[i] = i;
rank[i] = 1;
}
}
public int find(int u) {
if (u != parent[u]) {
parent[u] = find(parent[u]);
}
return parent[u];
}
public void union(int u, int v) {
int rootU = find(u);
int rootV = find(v);
if (rootU != rootV) {
if (rank[rootU] > rank[rootV]) {
parent[rootV] = rootU;
} else if (rank[rootU] < rank[rootV]) {
parent[rootU] = rootV;
} else {
parent[rootV] = rootU;
rank[rootU]++;
}
}
}
public boolean connected(int u, int v) {
return find(u) == find(v);
}
}
public class Solution {
public boolean[] edgeLengthLimitedPaths(int n, int[][] edgeList, int[][] queries) {
UnionFind uf = new UnionFind(n);
boolean[] answers = new boolean[queries.length];
Arrays.sort(edgeList, Comparator.comparingInt(a -> a[2]));
int[][] indexedQueries = new int[queries.length][];
for (int i = 0; i < queries.length; i++) {
indexedQueries[i] = new int[] { queries[i][0], queries[i][1], queries[i][2], i };
}
Arrays.sort(indexedQueries, Comparator.comparingInt(a -> a[2]));
int edgeIndex = 0;
for (int[] q : indexedQueries) {
int p = q[0], q2 = q[1], limit = q[2], qIndex = q[3];
while (edgeIndex < edgeList.length && edgeList[edgeIndex][2] < limit) {
uf.union(edgeList[edgeIndex][0], edgeList[edgeIndex][1]);
edgeIndex++;
}
answers[qIndex] = uf.connected(p, q2);
}
return answers;
}
}#include <vector>
#include <algorithm>
#include <numeric>
class UnionFind {
public:
std::vector<int> parent, rank;
UnionFind(int size) : parent(size), rank(size, 1) {
std::iota(parent.begin(), parent.end(), 0);
}
int find(int u) {
if (u != parent[u])
parent[u] = find(parent[u]);
return parent[u];
}
void union_sets(int u, int v) {
int rootU = find(u);
int rootV = find(v);
if (rootU != rootV) {
if (rank[rootU] > rank[rootV])
parent[rootV] = rootU;
else if (rank[rootU] < rank[rootV])
parent[rootU] = rootV;
else {
parent[rootV] = rootU;
++rank[rootU];
}
}
}
bool connected(int u, int v) {
return find(u) == find(v);
}
};
std::vector<bool> edgeLengthLimitedPaths(int n, std::vector<std::vector<int>>& edgeList, std::vector<std::vector<int>>& queries) {
UnionFind uf(n);
std::vector<bool> answers(queries.size(), false);
std::sort(edgeList.begin(), edgeList.end(), [](const std::vector<int>& a, const std::vector<int>& b) { return a[2] < b[2]; });
std::vector<std::pair<int, std::vector<int>>> sorted_queries;
for (int i = 0; i < queries.size(); ++i) {
sorted_queries.emplace_back(i, queries[i]);
}
std::sort(sorted_queries.begin(), sorted_queries.end(), [](const std::pair<int, std::vector<int>>& a, const std::pair<int, std::vector<int>>& b) { return a.second[2] < b.second[2]; });
int edgeIndex = 0;
for (const auto& [qIndex, qry] : sorted_queries) {
int p = qry[0], q = qry[1], limit = qry[2];
while (edgeIndex < edgeList.size() && edgeList[edgeIndex][2] < limit) {
uf.union_sets(edgeList[edgeIndex][0], edgeList[edgeIndex][1]);
++edgeIndex;
}
answers[qIndex] = uf.connected(p, q);
}
return answers;
}class UnionFind {
constructor(size) {
this.parent = Array.from({ length: size }, (_, index) => index);
this.rank = Array(size).fill(1);
}
find(u) {
if (u !== this.parent[u]) {
this.parent[u] = this.find(this.parent[u]);
}
return this.parent[u];
}
union(u, v) {
const rootU = this.find(u);
const rootV = this.find(v);
if (rootU !== rootV) {
if (this.rank[rootU] > this.rank[rootV]) {
this.parent[rootV] = rootU;
} else if (this.rank[rootU] < this.rank[rootV]) {
this.parent[rootU] = rootV;
} else {
this.parent[rootV] = rootU;
this.rank[rootU]++;
}
}
}
connected(u, v) {
return this.find(u) === this.find(v);
}
}
function edgeLengthLimitedPaths(n, edgeList, queries) {
const uf = new UnionFind(n);
const answers = new Array(queries.length).fill(false);
edgeList.sort((a, b) => a[2] - b[2]);
const indexedQueries = queries.map((q, index) => [...q, index]).sort((a, b) => a[2] - b[2]);
let edgeIndex = 0;
for (const [p, q, limit, qIndex] of indexedQueries) {
while (edgeIndex < edgeList.length && edgeList[edgeIndex][2] < limit) {
uf.union(edgeList[edgeIndex][0], edgeList[edgeIndex][1]);
edgeIndex++;
}
answers[qIndex] = uf.connected(p, q);
}
return answers;
}using System;
using System.Linq;
public class UnionFind {
private int[] parent;
private int[] rank;
public UnionFind(int size) {
parent = new int[size];
rank = new int[size];
for (int i = 0; i < size; i++) {
parent[i] = i;
rank[i] = 1;
}
}
public int Find(int u) {
if (u != parent[u]) {
parent[u] = Find(parent[u]);
}
return parent[u];
}
public void Union(int u, int v) {
int rootU = Find(u);
int rootV = Find(v);
if (rootU != rootV) {
if (rank[rootU] > rank[rootV]) {
parent[rootV] = rootU;
} else if (rank[rootU] < rank[rootV]) {
parent[rootU] = rootV;
} else {
parent[rootV] = rootU;
rank[rootU]++;
}
}
}
public bool Connected(int u, int v) {
return Find(u) == Find(v);
}
}
public class Solution {
public bool[] EdgeLengthLimitedPaths(int n, int[][] edgeList, int[][] queries) {
var uf = new UnionFind(n);
bool[] answers = new bool[queries.Length];
Array.Sort(edgeList, (a, b) => a[2].CompareTo(b[2]));
var indexedQueries = queries.Select((q, index) => new { q, index }).OrderBy(x => x.q[2]).ToArray();
int edgeIndex = 0;
foreach (var item in indexedQueries) {
int p = item.q[0], q = item.q[1], limit = item.q[2], qIndex = item.index;
while (edgeIndex < edgeList.Length && edgeList[edgeIndex][2] < limit) {
uf.Union(edgeList[edgeIndex][0], edgeList[edgeIndex][1]);
edgeIndex++;
}
answers[qIndex] = uf.Connected(p, q);
}
return answers;
}
}This Python code implements the Union-Find with Path Compression technique. Initially, we sort the edgeList by distance and the queries by their limit. As we iterate over each query, we add edges to the Union-Find structure that are below the given query's limit. Then, we check if the specified nodes in the query belong to the same connected component.
Time Complexity: O(E log E + Q log Q + (E + Q) α(n))
Space Complexity: O(n)
Approach 2: Kruskal's Algorithm Modification
This approach involves modifying Kruskal's Minimum Spanning Tree algorithm to answer multiple queries about path existence. We leverage the intrinsic nature of Kruskal's algorithm which builds an MST (or a union-find structured graph) incrementally. For each query sorted by limit, we add edges with weight less than the limit to the union-find structure and check if two nodes are connected.
class UnionFind:
    def __init__(self, size):
        self.parent = list(range(size))
        self.rank = [1] * size

    def find(self, u):
        if u != self.parent[u]:
            self.parent[u] = self.find(self.parent[u])
        return self.parent[u]

    def union(self, u, v):
        rootU = self.find(u)
        rootV = self.find(v)
        if rootU != rootV:
            if self.rank[rootU] > self.rank[rootV]:
                self.parent[rootV] = rootU
            elif self.rank[rootU] < self.rank[rootV]:
                self.parent[rootU] = rootV
            else:
                self.parent[rootV] = rootU
                self.rank[rootU] += 1

    def connected(self, u, v):
        return self.find(u) == self.find(v)


def edgeLengthLimitedPathsKruskal(n, edgeList, queries):
    uf = UnionFind(n)
    answers = [False] * len(queries)
    edgeList.sort(key=lambda x: x[2])
    sorted_queries = sorted(enumerate(queries), key=lambda x: x[1][2])

    edgeIndex = 0
    for qIndex, (p, q, limit) in sorted_queries:
        while edgeIndex < len(edgeList) and edgeList[edgeIndex][2] < limit:
            uf.union(edgeList[edgeIndex][0], edgeList[edgeIndex][1])
            edgeIndex += 1
        answers[qIndex] = uf.connected(p, q)

return answersimport java.util.*;
class UnionFind {
int[] parent, rank;
public UnionFind(int size) {
parent = new int[size];
rank = new int[size];
for (int i = 0; i < size; i++) {
parent[i] = i;
rank[i] = 1;
}
}
public int find(int u) {
if (u != parent[u]) {
parent[u] = find(parent[u]);
}
return parent[u];
}
public void union(int u, int v) {
int rootU = find(u);
int rootV = find(v);
if (rootU != rootV) {
if (rank[rootU] > rank[rootV]) {
parent[rootV] = rootU;
} else if (rank[rootU] < rank[rootV]) {
parent[rootU] = rootV;
} else {
parent[rootV] = rootU;
rank[rootU]++;
}
}
}
public boolean connected(int u, int v) {
return find(u) == find(v);
}
}
public class Solution {
public boolean[] edgeLengthLimitedPathsKruskal(int n, int[][] edgeList, int[][] queries) {
UnionFind uf = new UnionFind(n);
boolean[] answers = new boolean[queries.length];
Arrays.sort(edgeList, Comparator.comparingInt(a -> a[2]));
int[][] indexedQueries = new int[queries.length][];
for (int i = 0; i < queries.length; i++) {
indexedQueries[i] = new int[] { queries[i][0], queries[i][1], queries[i][2], i };
}
Arrays.sort(indexedQueries, Comparator.comparingInt(a -> a[2]));
int edgeIndex = 0;
for (int[] q : indexedQueries) {
int p = q[0], q2 = q[1], limit = q[2], qIndex = q[3];
while (edgeIndex < edgeList.length && edgeList[edgeIndex][2] < limit) {
uf.union(edgeList[edgeIndex][0], edgeList[edgeIndex][1]);
edgeIndex++;
}
answers[qIndex] = uf.connected(p, q2);
}
return answers;
}
}#include <vector>
#include <algorithm>
#include <numeric>
class UnionFind {
public:
std::vector<int> parent, rank;
UnionFind(int size) : parent(size), rank(size, 1) {
std::iota(parent.begin(), parent.end(), 0);
}
int find(int u) {
if (u != parent[u])
parent[u] = find(parent[u]);
return parent[u];
}
void union_sets(int u, int v) {
int rootU = find(u);
int rootV = find(v);
if (rootU != rootV) {
if (rank[rootU] > rank[rootV])
parent[rootV] = rootU;
else if (rank[rootU] < rank[rootV])
parent[rootU] = rootV;
else {
parent[rootV] = rootU;
++rank[rootU];
}
}
}
bool connected(int u, int v) {
return find(u) == find(v);
}
};
std::vector<bool> edgeLengthLimitedPathsKruskal(int n, std::vector<std::vector<int>>& edgeList, std::vector<std::vector<int>>& queries) {
UnionFind uf(n);
std::vector<bool> answers(queries.size(), false);
std::sort(edgeList.begin(), edgeList.end(), [](const std::vector<int>& a, const std::vector<int>& b) { return a[2] < b[2]; });
std::vector<std::pair<int, std::vector<int>>> sorted_queries;
for (int i = 0; i < queries.size(); ++i) {
sorted_queries.emplace_back(i, queries[i]);
}
std::sort(sorted_queries.begin(), sorted_queries.end(), [](const std::pair<int, std::vector<int>>& a, const std::pair<int, std::vector<int>>& b) { return a.second[2] < b.second[2]; });
int edgeIndex = 0;
for (const auto& [qIndex, qry] : sorted_queries) {
int p = qry[0], q = qry[1], limit = qry[2];
while (edgeIndex < edgeList.size() && edgeList[edgeIndex][2] < limit) {
uf.union_sets(edgeList[edgeIndex][0], edgeList[edgeIndex][1]);
++edgeIndex;
}
answers[qIndex] = uf.connected(p, q);
}
return answers;
}class UnionFind {
constructor(size) {
this.parent = Array.from({ length: size }, (_, index) => index);
this.rank = Array(size).fill(1);
}
find(u) {
if (u !== this.parent[u]) {
this.parent[u] = this.find(this.parent[u]);
}
return this.parent[u];
}
union(u, v) {
const rootU = this.find(u);
const rootV = this.find(v);
if (rootU !== rootV) {
if (this.rank[rootU] > this.rank[rootV]) {
this.parent[rootV] = rootU;
} else if (this.rank[rootU] < this.rank[rootV]) {
this.parent[rootU] = rootV;
} else {
this.parent[rootV] = rootU;
this.rank[rootU]++;
}
}
}
connected(u, v) {
return this.find(u) === this.find(v);
}
}
function edgeLengthLimitedPathsKruskal(n, edgeList, queries) {
const uf = new UnionFind(n);
const answers = new Array(queries.length).fill(false);
edgeList.sort((a, b) => a[2] - b[2]);
const indexedQueries = queries.map((q, index) => [...q, index]).sort((a, b) => a[2] - b[2]);
let edgeIndex = 0;
for (const [p, q, limit, qIndex] of indexedQueries) {
while (edgeIndex < edgeList.length && edgeList[edgeIndex][2] < limit) {
uf.union(edgeList[edgeIndex][0], edgeList[edgeIndex][1]);
edgeIndex++;
}
answers[qIndex] = uf.connected(p, q);
}
return answers;
}using System;
using System.Linq;
public class UnionFind {
private int[] parent;
private int[] rank;
public UnionFind(int size) {
parent = new int[size];
rank = new int[size];
for (int i = 0; i < size; i++) {
parent[i] = i;
rank[i] = 1;
}
}
public int Find(int u) {
if (u != parent[u]) {
parent[u] = Find(parent[u]);
}
return parent[u];
}
public void Union(int u, int v) {
int rootU = Find(u);
int rootV = Find(v);
if (rootU != rootV) {
if (rank[rootU] > rank[rootV]) {
parent[rootV] = rootU;
} else if (rank[rootU] < rank[rootV]) {
parent[rootU] = rootV;
} else {
parent[rootV] = rootU;
rank[rootU]++;
}
}
}
public bool Connected(int u, int v) {
return Find(u) == Find(v);
}
}
public class Solution {
public bool[] EdgeLengthLimitedPathsKruskal(int n, int[][] edgeList, int[][] queries) {
var uf = new UnionFind(n);
bool[] answers = new bool[queries.Length];
Array.Sort(edgeList, (a, b) => a[2].CompareTo(b[2]));
var indexedQueries = queries.Select((q, index) => new { q, index }).OrderBy(x => x.q[2]).ToArray();
int edgeIndex = 0;
foreach (var item in indexedQueries) {
int p = item.q[0], q = item.q[1], limit = item.q[2], qIndex = item.index;
while (edgeIndex < edgeList.Length && edgeList[edgeIndex][2] < limit) {
uf.Union(edgeList[edgeIndex][0], edgeList[edgeIndex][1]);
edgeIndex++;
}
answers[qIndex] = uf.Connected(p, q);
}
return answers;
}
}This Python code uses a slight modification of Kruskal's algorithm. We use the union-find data structure to progressively add edges before each query is processed, sorted by their limit. It essentially mimics building a Minimum Spanning Tree to answer each query about connectivity efficiently.
Time Complexity: O(E log E + Q log Q + (E + Q) α(n))
Space Complexity: O(n)
Approach 3: Offline Queries + Union-Find
According to the problem requirements, we need to judge each query queries[i], that is, to determine whether there is a path with edge weight less than or equal to limit between the two points a and b of the current query.
The connectivity of two points can be determined by a union-find set. Moreover, since the order of queries does not affect the result, we can sort all queries in ascending order by limit, and also sort all edges in ascending order by edge weight.
Then for each query, we start from the edge with the smallest weight, add all edges with weights strictly less than limit to the union-find set, and then use the query operation of the union-find set to determine whether the two points are connected.
The time complexity is O(m times log m + q times log q), where m and q are the number of edges and queries, respectively.
func distanceLimitedPathsExist(n int, edgeList [][]int, queries [][]int) []bool {
	p := make([]int, n)
	for i := range p {
		p[i] = i
	}
	sort.Slice(edgeList, func(i, j int) bool { return edgeList[i][2] < edgeList[j][2] })
	var find func(int) int
	find = func(x int) int {
		if p[x] != x {
			p[x] = find(p[x])
		}
		return p[x]
	}
	m := len(queries)
	qid := make([]int, m)
	ans := make([]bool, m)
	for i := range qid {
		qid[i] = i
	}
	sort.Slice(qid, func(i, j int) bool { return queries[qid[i]][2] < queries[qid[j]][2] })
	j := 0
	for _, i := range qid {
		a, b, limit := queries[i][0], queries[i][1], queries[i][2]
		for j < len(edgeList) && edgeList[j][2] < limit {
			u, v := edgeList[j][0], edgeList[j][1]
			p[find(u)] = find(v)
			j++
		}
		ans[i] = find(a) == find(b)
	}
	return ans
}impl Solution {
#[allow(dead_code)]
pub fn distance_limited_paths_exist(
n: i32,
edge_list: Vec<Vec<i32>>,
queries: Vec<Vec<i32>>,
) -> Vec<bool> {
let mut disjoint_set: Vec<usize> = vec![0; n as usize];
let mut ans_vec: Vec<bool> = vec![false; queries.len()];
let mut q_vec: Vec<usize> = vec![0; queries.len()];
// Initialize the set
for i in 0..n {
disjoint_set[i as usize] = i as usize;
}
// Initialize the q_vec
for i in 0..queries.len() {
q_vec[i] = i;
}
// Sort the q_vec based on the query limit, from the lowest to highest
q_vec.sort_by(|i, j| queries[*i][2].cmp(&queries[*j][2]));
// Sort the edge_list based on the edge weight, from the lowest to highest
let mut edge_list = edge_list.clone();
edge_list.sort_by(|i, j| i[2].cmp(&j[2]));
let mut edge_idx: usize = 0;
for q_idx in &q_vec {
let s = queries[*q_idx][0] as usize;
let d = queries[*q_idx][1] as usize;
let limit = queries[*q_idx][2];
// Construct the disjoint set
while edge_idx < edge_list.len() && edge_list[edge_idx][2] < limit {
Solution::union(
edge_list[edge_idx][0] as usize,
edge_list[edge_idx][1] as usize,
&mut disjoint_set,
);
edge_idx += 1;
}
// If the parents of s & d are the same, this query should be `true`
// Otherwise, the current query is `false`
ans_vec[*q_idx] = Solution::check_valid(s, d, &mut disjoint_set);
}
ans_vec
}
#[allow(dead_code)]
pub fn find(x: usize, d_set: &mut Vec<usize>) -> usize {
if d_set[x] != x {
d_set[x] = Solution::find(d_set[x], d_set);
}
return d_set[x];
}
#[allow(dead_code)]
pub fn union(s: usize, d: usize, d_set: &mut Vec<usize>) {
let p_s = Solution::find(s, d_set);
let p_d = Solution::find(d, d_set);
d_set[p_s] = p_d;
}
#[allow(dead_code)]
pub fn check_valid(s: usize, d: usize, d_set: &mut Vec<usize>) -> bool {
let p_s = Solution::find(s, d_set);
let p_d = Solution::find(d, d_set);
p_s == p_d
}
}Complexity comparison
| Approach | Complexity |
|---|---|
| Union-Find with Sorting | Time Complexity: O(E log E + Q log Q + (E + Q) α(n)) |
| Kruskal's Algorithm Modification | Time Complexity: O(E log E + Q log Q + (E + Q) α(n)) |
| Offline Queries + Union-Find | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Brute Force BFS/DFS per Query | O(Q * (N + E)) | O(N + E) | Small graphs or when constraints are tiny and implementation simplicity matters |
| Union-Find with Sorted Queries | O((E + Q) log E) | O(N) | Best general solution for large graphs and many queries |
| Modified Kruskal Processing | O((E + Q) log E) | O(N) | Useful when reasoning about MST construction or weight-ordered connectivity |
Frequently asked questions
Is Checking Existence of Edge Length Limited Paths easy or hard?
This problem is classified as Hard because it combines graph connectivity, offline query processing, and Union-Find optimization. The challenge is recognizing that queries should be sorted and processed incrementally rather than solved independently.
Checking Existence of Edge Length Limited Paths Python or Java solution
Python, Java, C++, JavaScript, and C# implementations typically follow the same pattern: sort edges, sort queries with original indices, process edges incrementally, and use a Union-Find structure to test connectivity. The logic remains identical across languages.
How to solve Checking Existence of Edge Length Limited Paths efficiently?
Sort the edge list by weight and sort queries by their distance limit. Use a Union-Find data structure and keep adding edges whose weights are smaller than the current query limit. After inserting eligible edges, check if the query’s two nodes share the same parent in the disjoint set.
What is the best approach for Checking Existence of Edge Length Limited Paths?
The most efficient approach uses Union-Find with offline query processing. Sort edges by weight and sort queries by their limit. Gradually union edges whose weights are smaller than the query limit, then check if the two nodes belong to the same component. This reduces repeated graph traversals and runs in O((E + Q) log E) time.
Is Checking Existence of Edge Length Limited Paths asked at Google/Amazon/Meta?
Graph connectivity with constraints and Union-Find problems frequently appear in interviews at companies like Google, Amazon, and Meta. Variants involving offline queries, dynamic connectivity, or Kruskal-style processing are common in senior-level algorithm interviews.
What data structure is used in Checking Existence of Edge Length Limited Paths?
The core data structure is Union-Find (Disjoint Set Union). It efficiently maintains connected components while edges are added in sorted order. Path compression and union by rank keep operations nearly constant time.
What is the time complexity of Checking Existence of Edge Length Limited Paths?
The optimal solution runs in O((E + Q) log E) time due to sorting the edges and queries. Union-Find operations such as union and find run in nearly constant amortized time with path compression. Space complexity is O(N) for maintaining the disjoint set structure.