Tree Node solution and explanation
 Google

9 more videos on this problem
 Solving SQL Interview Query | Find Tree Node type using SQLtechTFQ · 9:43 · 32K views
 LeetCode Medium 608 Uber & Amazon Interview SQL Question with Detailed ExplanationEveryday Data Science · 6:50 · 6K views
 Leet Code SQL Problem 608 Tree NodeCloudFitness · 9:44 · 2K views
 LeetCode 608 - Tree Node (Python and SQL) [Medium]Ryan & Matt Data Science · 12:13 · 398 views
 Leetcode 608 [SQL] : Tree Node Easy Explanation #sql #interviewData Titan 101 · 9:09 · 381 views
 608. Tree Node | LeetCode | SQL | Solution | Interview ProblemData Alchemist · 5:49 · 285 views
 LeetCode 608. Tree Node | Case end | SQLSleepy Cracker · 2:51 · 123 views
 LeetCode - 608. Tree Node (SQL)Chain Of Thought · 5:42 · 62 views
 608. Tree Node Updated ||LeetCode - Medium||SQL #sql #insightvanta #leetcodeInsightVanta · 5:31 · 38 views
 #15 Leetcode #608 Tree Node #sqlqueryinterviewquestionsandanswers #leetcodesqljava stories · 5:49 · 31 views
The problem
Table: Tree
+-------------+------+
| Column Name | Type |
+-------------+------+
| id          | int  |
| p_id        | int  |
+-------------+------+
id is the column with unique values for this table.
Each row of this table contains information about the id of a node and the id of its parent node in a tree.
The given structure is always a valid tree.
Each node in the tree can be one of three types:
- "Leaf": if the node is a leaf node.
- "Root": if the node is the root of the tree.
- "Inner": If the node is neither a leaf node nor a root node.
Write a solution to report the type of each node in the tree.
Return the result table in any order.
The result format is in the following example.
Example 1:
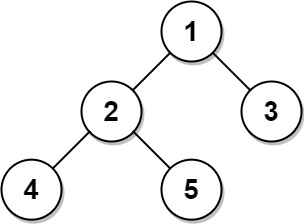
Input:
Tree table:
+----+------+
| id | p_id |
+----+------+
| 1  | null |
| 2  | 1    |
| 3  | 1    |
| 4  | 2    |
| 5  | 2    |
+----+------+
Output:
+----+-------+
| id | type  |
+----+-------+
| 1  | Root  |
| 2  | Inner |
| 3  | Leaf  |
| 4  | Leaf  |
| 5  | Leaf  |
+----+-------+
Explanation:
Node 1 is the root node because its parent node is null and it has child nodes 2 and 3.
Node 2 is an inner node because it has parent node 1 and child node 4 and 5.
Nodes 3, 4, and 5 are leaf nodes because they have parent nodes and they do not have child nodes.
Example 2:

Input:
Tree table:
+----+------+
| id | p_id |
+----+------+
| 1  | null |
+----+------+
Output:
+----+-------+
| id | type  |
+----+-------+
| 1  | Root  |
+----+-------+
Explanation: If there is only one node on the tree, you only need to output its root attributes.
Note: This question is the same as 3054: Binary Tree Nodes.
Approach overview
Problem Overview: You are given a table Tree(id, p_id) representing a tree structure. Each row is a node, and p_id points to its parent. The task is to classify every node as Root, Inner, or Leaf depending on whether it has a parent and whether it has children.
Approach 1: Using Child Count (O(n) time, O(1) extra space)
This approach determines the node type by checking how many children each node has. Perform a self-reference lookup where a node’s id appears as another row’s p_id. If p_id IS NULL, the node is the Root. If the node appears in the child list (meaning at least one row has p_id = id), it is an Inner node. Otherwise, it is a Leaf. SQL typically uses GROUP BY or LEFT JOIN with a child count to detect this. With proper indexing on id and p_id, the database scans the table once and performs efficient lookups, giving roughly O(n) time complexity and constant auxiliary space since the work happens inside the query engine. This approach is clear and scales well for larger datasets.
Approach 2: Using Parent Lookup (O(n) time, O(1) extra space)
Instead of counting children, this method directly checks membership relationships. First identify the root using p_id IS NULL. For the remaining rows, determine if a node is referenced as a parent anywhere in the table. If a node’s id appears in the set of p_id values, it must have at least one child, making it an Inner node. If it does not appear in that set, it is a Leaf. This is usually implemented with IN, NOT IN, or EXISTS subqueries. The database engine internally builds a lookup structure for the parent IDs, so the classification can still be resolved in about O(n) time. The query is concise and easy to reason about when working with relational hierarchies.
Problems like this frequently appear in database interview rounds because they test how well you understand hierarchical data in relational tables. You are essentially deriving structural information from a flat table using SQL operations such as filtering, membership checks, and self-references. Knowledge of SQL joins and subqueries is essential, especially when modeling parent-child relationships similar to self joins.
Recommended for interviews: The child-count or self-join approach is typically preferred because it clearly shows how you derive children from the table structure. The parent lookup version is slightly shorter and perfectly valid, but interviewers often expect you to reason explicitly about parent-child relationships using joins or grouped counts.
Approach 1: Approach 1: Using Child Count
The idea is to identify the type of each node by examining the parent-child relationship. Specifically, to identify:
- The root node, which does not have a parent.
- Inner nodes, which have children.
- Leaf nodes, which do not have any children.
Steps:
- Traverse the tree table to build a map where each id points to its type.
- Use a helper data structure to count the number of children for each node.
- Scan the table again to finalize node types based on the count data.
def classify_nodes(nodes):
    child_count = dict()
    types = dict()

    for node in nodes:
        id, p_id = node
        if p_id != None:
            child_count[p_id] = child_count.get(p_id, 0) + 1
        types[id] = "Leaf"

    for node in nodes:
        id, p_id = node
        if p_id is None:
            types[id] = "Root"
        elif id in child_count:
            types[id] = "Inner"

    for id in types:
        print(id, types[id])

nodes = [(1, None), (2, 1), (3, 1), (4, 2), (5, 2)]
classify_nodes(nodes)import java.util.*;
class Node {
int id, p_id;
Node(int id, int p_id) { this.id = id; this.p_id = p_id; }
}
public class TreeNode {
public static void classifyNodes(List<Node> nodes) {
Map<Integer, Integer> childCount = new HashMap<>();
Map<Integer, String> types = new HashMap<>();
for (Node node : nodes) {
if (node.p_id != -1) {
childCount.put(node.p_id, childCount.getOrDefault(node.p_id, 0) + 1);
}
types.put(node.id, "Leaf");
}
for (Node node : nodes) {
if (node.p_id == -1) {
types.put(node.id, "Root");
} else if (childCount.getOrDefault(node.id, 0) > 0) {
types.put(node.id, "Inner");
}
}
for (Node node : nodes) {
System.out.println(node.id + " " + types.get(node.id));
}
}
public static void main(String[] args) {
List<Node> nodes = Arrays.asList(
new Node(1, -1),
new Node(2, 1),
new Node(3, 1),
new Node(4, 2),
new Node(5, 2)
);
classifyNodes(nodes);
}
}#include <iostream>
#include <vector>
#include <unordered_map>
using namespace std;
struct Node {
int id, p_id;
};
void classifyNodes(vector<Node>& nodes) {
unordered_map<int, int> childCount;
unordered_map<int, string> types;
for (const auto& node : nodes) {
if (node.p_id != -1) {
childCount[node.p_id]++;
}
types[node.id] = "Leaf";
}
for (const auto& node : nodes) {
if (node.p_id == -1) {
types[node.id] = "Root";
} else if (childCount[node.id]) {
types[node.id] = "Inner";
}
}
for (const auto& node : nodes) {
cout << node.id << " " << types[node.id] << endl;
}
}
int main() {
vector<Node> nodes = {{1, -1}, {2, 1}, {3, 1}, {4, 2}, {5, 2}};
classifyNodes(nodes);
return 0;
}const classifyNodes = (nodes) => {
const childCount = {};
const types = {};
nodes.forEach(([id, p_id]) => {
if (p_id !== null) {
if (!childCount[p_id]) childCount[p_id] = 0;
childCount[p_id]++;
}
types[id] = "Leaf";
});
nodes.forEach(([id, p_id]) => {
if (p_id === null) {
types[id] = "Root";
} else if (childCount[id]) {
types[id] = "Inner";
}
});
for (const id in types) {
console.log(id, types[id]);
}
};
const nodes = [[1, null], [2, 1], [3, 1], [4, 2], [5, 2]];
classifyNodes(nodes);#include <stdio.h>
#include <stdlib.h>
#include <string.h>
#define MAX_NODES 100
typedef struct {
int id;
int p_id;
} Node;
typedef struct {
int id;
char type[10];
} ResultNode;
void classifyNodes(Node nodes[], int n, ResultNode result[]) {
int children[MAX_NODES] = {0};
int isRoot[MAX_NODES] = {0};
for (int i = 0; i < n; i++) {
if (nodes[i].p_id == -1) {
isRoot[nodes[i].id] = 1;
continue;
}
children[nodes[i].p_id]++;
}
for (int i = 0; i < n; i++) {
int id = nodes[i].id;
strcpy(result[i].type, "Leaf");
if (children[id] > 0) strcpy(result[i].type, "Inner");
if (isRoot[id]) strcpy(result[i].type, "Root");
result[i].id = id;
}
}
int main() {
Node nodes[] = {{1, -1}, {2, 1}, {3, 1}, {4, 2}, {5, 2}};
int n = 5;
ResultNode result[5];
classifyNodes(nodes, n, result);
for (int i = 0; i < n; i++) {
printf("%d %s\n", result[i].id, result[i].type);
}
return 0;
}using System;
using System.Collections.Generic;
public class Node {
public int Id, PId;
public Node(int id, int pId) { Id = id; PId = pId; }
}
public class TreeNode {
public static void ClassifyNodes(List<Node> nodes) {
var childCount = new Dictionary<int, int>();
var types = new Dictionary<int, string>();
foreach (var node in nodes) {
if (node.PId != -1) {
if (!childCount.ContainsKey(node.PId)) childCount[node.PId] = 0;
childCount[node.PId]++;
}
types[node.Id] = "Leaf";
}
foreach (var node in nodes) {
if (node.PId == -1) {
types[node.Id] = "Root";
} else if (childCount.ContainsKey(node.Id)) {
types[node.Id] = "Inner";
}
}
foreach (var node in nodes) {
Console.WriteLine(node.Id + " " + types[node.Id]);
}
}
public static void Main() {
List<Node> nodes = new List<Node> {
new Node(1, -1), new Node(2, 1), new Node(3, 1), new Node(4, 2), new Node(5, 2)
};
ClassifyNodes(nodes);
}
}The Python solution leverages dictionaries to count children and classify node types. By iterating over the list of nodes, it first initializes each node as a 'Leaf', then updates its status to 'Root' or 'Inner' based on its structural position in the tree.
Time Complexity: O(n) - single traversal of nodes.
Space Complexity: O(n) - space for dictionaries.
Approach 2: Approach 2: Using Parent Lookup
This approach centers around identifying nodes type by tracking parent relationships directly:
- Root nodes are explicitly those which have no parents.
- Inner nodes have a parent (non-null p_id) and also have children, usually derived by inversion of role (found as a parent somewhere).
- Leaf nodes aren't found as a parent in any other nodes.
Steps:
- Construct a parent dictionary to easily distinguish inner from leaf nodes.
- Assign initial types by checking the node's p_id and presence in the parent dictionary.
def classify_nodes(nodes):
    is_child = set()

    for id, p_id in nodes:
        if p_id is not None:
            is_child.add(p_id)

    for id, p_id in nodes:
        if p_id is None:
            print(id, "Root")
        elif id in is_child:
            print(id, "Inner")
        else:
            print(id, "Leaf")

nodes = [(1, None), (2, 1), (3, 1), (4, 2), (5, 2)]
classify_nodes(nodes)import java.util.*;
class Node {
int id, p_id;
Node(int id, int p_id) { this.id = id; this.p_id = p_id; }
}
public class TreeNode {
public static void classifyNodes(List<Node> nodes) {
Set<Integer> isChild = new HashSet<>();
nodes.forEach(node -> {
if (node.p_id != -1) isChild.add(node.p_id);
});
nodes.forEach(node -> {
if (node.p_id == -1) {
System.out.println(node.id + " Root");
} else if (isChild.contains(node.id)) {
System.out.println(node.id + " Inner");
} else {
System.out.println(node.id + " Leaf");
}
});
}
public static void main(String[] args) {
List<Node> nodes = Arrays.asList(
new Node(1, -1),
new Node(2, 1),
new Node(3, 1),
new Node(4, 2),
new Node(5, 2)
);
classifyNodes(nodes);
}
}#include <iostream>
#include <vector>
#include <unordered_set>
struct Node {
int id, p_id;
};
void classifyNodes(const std::vector<Node>& nodes) {
std::unordered_set<int> isChild;
for (const auto& node : nodes) {
if (node.p_id != -1) {
isChild.insert(node.p_id);
}
}
for (const auto& node : nodes) {
if (node.p_id == -1) {
std::cout << node.id << " Root" << std::endl;
} else if (isChild.count(node.id)) {
std::cout << node.id << " Inner" << std::endl;
} else {
std::cout << node.id << " Leaf" << std::endl;
}
}
}
int main() {
std::vector<Node> nodes = {{1, -1}, {2, 1}, {3, 1}, {4, 2}, {5, 2}};
classifyNodes(nodes);
return 0;
}const classifyNodes = (nodes) => {
const isChild = new Set();
nodes.forEach(([id, p_id]) => {
if (p_id !== null) isChild.add(p_id);
});
nodes.forEach(([id, p_id]) => {
if (p_id === null) {
console.log(id, "Root");
} else if (isChild.has(id)) {
console.log(id, "Inner");
} else {
console.log(id, "Leaf");
}
});
};
const nodes = [[1, null], [2, 1], [3, 1], [4, 2], [5, 2]];
classifyNodes(nodes);#include <stdio.h>
#include <stdlib.h>
#include <string.h>
#define MAX_NODES 100
typedef struct {
int id;
int p_id;
} Node;
typedef struct {
int id;
char type[10];
} ResultNode;
void classifyNodes(Node nodes[], int n, ResultNode result[]) {
int isChild[MAX_NODES] = {0};
for (int i = 0; i < n; i++) {
if (nodes[i].p_id != -1) {
isChild[nodes[i].p_id] = 1;
}
}
for (int i = 0; i < n; i++) {
int id = nodes[i].id;
if (nodes[i].p_id == -1) {
strcpy(result[i].type, "Root");
} else if (isChild[id]) {
strcpy(result[i].type, "Inner");
} else {
strcpy(result[i].type, "Leaf");
}
result[i].id = id;
}
}
int main() {
Node nodes[] = {{1, -1}, {2, 1}, {3, 1}, {4, 2}, {5, 2}};
int n = 5;
ResultNode result[5];
classifyNodes(nodes, n, result);
for (int i = 0; i < n; i++) {
printf("%d %s\n", result[i].id, result[i].type);
}
return 0;
}using System;
using System.Collections.Generic;
public class Node {
public int Id, PId;
public Node(int id, int pId) { Id = id; PId = pId; }
}
public class TreeNode {
public static void ClassifyNodes(List<Node> nodes) {
var isChild = new HashSet<int>();
foreach (var node in nodes) {
if (node.PId != -1) isChild.Add(node.PId);
}
foreach (var node in nodes) {
if (node.PId == -1) {
Console.WriteLine(node.Id + " Root");
} else if (isChild.Contains(node.Id)) {
Console.WriteLine(node.Id + " Inner");
} else {
Console.WriteLine(node.Id + " Leaf");
}
}
}
public static void Main() {
List<Node> nodes = new List<Node> {
new Node(1, -1), new Node(2, 1), new Node(3, 1), new Node(4, 2), new Node(5, 2)
};
ClassifyNodes(nodes);
}
}Python's implementation uses a set to distinguish between nodes that are involved as parents. This effectively allows rapid classification of node status, ensuring concise filtering of data.
Time Complexity: O(n)
Space Complexity: O(n)
Approach 3: Conditional Statements + Subquery
We can use the CASE WHEN conditional statement to determine the type of each node as follows:
- If a node's
p_idisNULL, then it is a root node. - Otherwise, if a node is the parent node of another node (we use a subquery to determine this), then it is an internal node.
- Otherwise, it is a leaf node.
# Write your MySQL query statement below
SELECT
    id,
    CASE
        WHEN p_id IS NULL THEN 'Root'
        WHEN id IN (SELECT p_id FROM Tree) THEN 'Inner'
        ELSE 'Leaf'
    END AS type
FROM Tree;Complexity comparison
| Approach | Complexity |
|---|---|
| Approach 1: Using Child Count | Time Complexity: O(n) - single traversal of nodes. |
| Approach 2: Using Parent Lookup | Time Complexity: O(n) |
| Conditional Statements + Subquery | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Child Count via Self Join / Group By | O(n) | O(1) | Best for clearly identifying nodes with children using joins or grouped counts |
| Parent Lookup with IN / EXISTS | O(n) | O(1) | Shorter SQL when simply checking if a node appears as a parent |
Frequently asked questions
Is Tree Node easy or hard?
Tree Node is generally considered a medium-level SQL problem. The difficulty comes from recognizing how to infer tree structure from a flat table and correctly classify nodes using parent-child relationships.
Tree Node Python/Java solution
The problem itself is solved using SQL because the input is a relational table. However, the same logic can be implemented in Python or Java by building a map from parent to children and classifying each node based on whether it has a parent and how many children it has.
How to solve Tree Node in O(n)?
Scan the table once and determine node types using SQL conditions. If p_id IS NULL, the node is Root. If the node’s id appears as a p_id in another row, it is an Inner node. Otherwise it is a Leaf. Using joins or EXISTS queries keeps the complexity around O(n).
What is the best approach for Tree Node?
The child-count or self-join approach is the most common solution. It checks whether each node appears as a parent in other rows to determine if it has children. Combined with the condition p_id IS NULL for the root, this classifies nodes as Root, Inner, or Leaf in about O(n) time.
Is Tree Node asked at Google/Amazon/Meta?
Tree Node represents a typical SQL hierarchy classification problem that appears in database interview rounds at large tech companies. Variants of parent-child relationship queries and hierarchical data classification are common in companies like Amazon, Google, and Meta.
What data structure is used in Tree Node?
The logical structure is a tree represented in a relational table using a parent pointer (p_id). Instead of explicit tree nodes, the hierarchy is inferred using SQL joins or parent lookups between rows.
What is the time complexity of Tree Node?
Most SQL solutions run in O(n) time because the table is scanned and parent-child relationships are checked using indexed lookups or joins. The database engine optimizes membership checks such as IN, EXISTS, or JOIN operations internally.