
Recover a Tree From Preorder Traversal - Solution & Explanation
Problem Statement
We run a preorder depth-first search (DFS) on the root of a binary tree.
At each node in this traversal, we output D dashes (where D is the depth of this node), then we output the value of this node. If the depth of a node is D, the depth of its immediate child is D + 1. The depth of the root node is 0.
If a node has only one child, that child is guaranteed to be the left child.
Given the output traversal of this traversal, recover the tree and return its root.
Example 1:
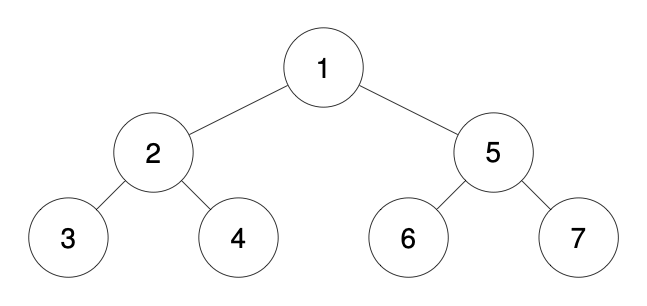
Input: traversal = "1-2--3--4-5--6--7"
Output: [1,2,5,3,4,6,7]
Example 2:
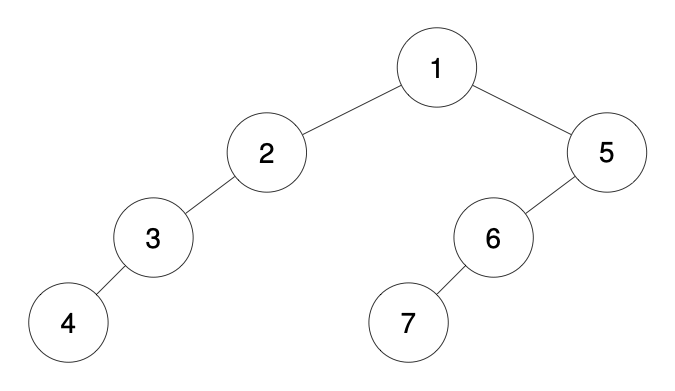
Input: traversal = "1-2--3---4-5--6---7"
Output: [1,2,5,3,null,6,null,4,null,7]
Example 3:
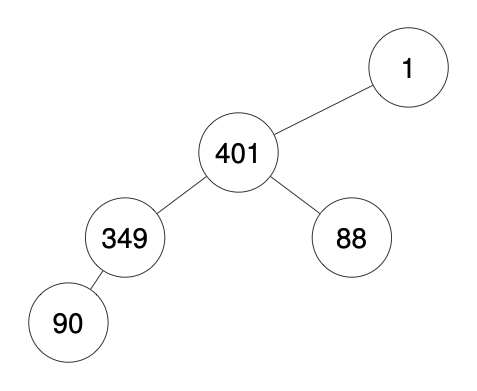
Input: traversal = "1-401--349---90--88"
Output: [1,401,null,349,88,90]
Constraints:
- The number of nodes in the original tree is in the range
[1, 1000]. 1 <= Node.val <= 109
Approach Overview
Problem Overview: The input string represents a preorder traversal of a binary tree where node depth is encoded using dashes (-). Each node value appears after a sequence of dashes equal to its depth. Your task is to rebuild the original binary tree from this encoded preorder string.
Approach 1: Recursive Parsing with DFS (Time: O(n), Space: O(h))
This method parses the string while recursively building the tree in preorder order. First read the number of dashes to determine the node’s depth, then parse the integer value that follows. If the current depth matches the expected depth, create the node and recursively build its left and right children. If the dash count does not match the expected depth, backtrack so the parent call can attach the node correctly. The traversal naturally mirrors preorder construction using depth-first search. Time complexity is O(n) because each character in the string is processed once, and space complexity is O(h) due to the recursion stack where h is tree height.
Approach 2: Iterative Construction Using Stack (Time: O(n), Space: O(n))
The iterative approach processes the string left to right and uses a stack to track the path from root to the current node. First count dashes to determine the node depth, then parse the node value. While the stack size is greater than the current depth, pop nodes until the parent at depth d-1 remains on top. Attach the new node as the left child if empty, otherwise as the right child. Push the new node onto the stack to maintain the traversal path. The stack effectively represents the current root-to-node path in the tree. Each node is pushed and popped at most once, giving O(n) time and O(n) auxiliary space.
Recommended for interviews: The stack-based iterative approach is typically expected in interviews because it directly models the preorder traversal path and avoids complex recursion state management. The recursive solution demonstrates strong understanding of preorder parsing and DFS construction, but the stack version is easier to reason about under time pressure while maintaining the optimal O(n) runtime.
Approach 1: Recursive Approach
In this approach, we recursively parse the traversal string to construct the tree. We track the current position in the string and the expected depth using recursion. For each valid node, we create a new tree node and attempt to construct its left and right subtrees by increasing the expected depth.
The code defines a TreeNode class and a recoverFromPreorder function that constructs a binary tree from the given traversal string. This is done using a nested helper function that recursively builds the tree. The function uses a nonlocal index variable to maintain the current position within the string.
For each node, helper checks the number of dashes to see if they match the expected depth. If they match, it extracts the number representing the node's value, creates a TreeNode, and attempts to add left and right children by increasing the expected depth.
Complexity
Time Complexity: O(n), where n is the length of the traversal string, since each character is processed once.
Space Complexity: O(h), where h is the height of the tree, as this is the maximum depth of the recursion stack.
Approach 2: Iterative Approach Using Stack
An iterative approach can be implemented using a stack. We use the stack to keep track of nodes along with their depths, and iteratively add nodes while maintaining the correct parent-child relationships. Each new node is inserted as a child of the node on the top of the stack, with adjustments made based on depths.
In Python, an iterative solution uses a stack to manage nodes and depths while parsing the traversal string. The number of dashes determines the depth. Nodes are created based on parsed values, and the stack is leveraged to attach each node at the correct position in the tree. Levels deeper than the current node's depth are popped from the stack, associating nodes as the left (and subsequently right) child of the last valid node at that depth.
Code
Python
C#
JavaScript
Complexity
Time Complexity: O(n), where n is the string length, as each character is evaluated once.
Space Complexity: O(h), where h is the height of the tree, related to the maximum size of the stack.
Approach 3: Default Approach
Code
Java
C++
TypeScript
JavaScript
Complexity Comparison
| Approach | Complexity |
|---|---|
| Recursive Approach | Time Complexity: O(n), where n is the length of the traversal string, since each character is processed once. Space Complexity: O(h), where h is the height of the tree, as this is the maximum depth of the recursion stack. |
| Iterative Approach Using Stack | Time Complexity: O(n), where n is the string length, as each character is evaluated once. Space Complexity: O(h), where h is the height of the tree, related to the maximum size of the stack. |
| Default Approach | — |
Detailed Complexity Analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Recursive DFS Parsing | O(n) | O(h) | Good when recursion is comfortable and you want code that mirrors preorder traversal logic |
| Iterative Stack Construction | O(n) | O(n) | Preferred in interviews; stack explicitly tracks node depth and parent relationships |
Video Solution
Recover a Tree From Preorder Traversal - Leetcode 1028 - Python • NeetCodeIO • 11,186 views views
Watch 9 more video solutions →Frequently Asked Questions
Is Recover a Tree From Preorder Traversal easy or hard?
Recover a Tree From Preorder Traversal Python/Java solution
How to solve Recover a Tree From Preorder Traversal in O(n)?
What is the best approach for Recover a Tree From Preorder Traversal?
Is Recover a Tree From Preorder Traversal asked at Google/Amazon/Meta?
What data structure is used in Recover a Tree From Preorder Traversal?
What is the time complexity of Recover a Tree From Preorder Traversal?
Ready to solve this problem?
Practice Recover a Tree From Preorder Traversal with our built-in code editor and test cases.
Practice on FleetCode