Reachable Nodes In Subdivided Graph solution and explanation
 Google

9 more videos on this problem
 Reachable Nodes In Subdivided Graph | Leetcode 882 | Live coding sessionCoding Decoded · 19:50 · 4K views
 花花酱 LeetCode 882. Reachable Nodes In Subdivided Graph - 刷题找工作 EP215Hua Hua · 16:01 · 3K views
 LeetCode 882. Reachable Nodes In Subdivided GraphHappy Coding · 17:44 · 2K views
 Reachable Nodes In Subdivided Graph | LeetCode | Intuitive Dijkstra Solution Explained in DetailTanishq Chaudhary · 23:30 · 1K views
 【每日一题】882. Reachable Nodes In Subdivided Graph, 2/21/2021Huifeng Guan · 27:06 · 730 views
 Daily Leetcode #530: Sep 12, 2021 - 882. Reachable Nodes In Subdivided GraphProgramming Live with Larry · 27:23 · 701 views
 Leetcode - Reachable Nodes In Subdivided Graph (Python)Timothy H Chang · 14:21 · 576 views
 Day 12/30 | Reachable Nodes In Subdivided Graph | September LeetCoding Challenge 2021 | C++Ascorbichelix · 20:40 · 419 views
 Leetcode 0882. Reachable Nodes In Subdivided GraphFearless Learner · 17:16 · 238 views
 Reachable Nodes In Subdivided Graph||Leetcode || HardSandeep Vaid · 28:11 · 158 views
The problem
You are given an undirected graph (the "original graph") with n nodes labeled from 0 to n - 1. You decide to subdivide each edge in the graph into a chain of nodes, with the number of new nodes varying between each edge.
The graph is given as a 2D array of edges where edges[i] = [ui, vi, cnti] indicates that there is an edge between nodes ui and vi in the original graph, and cnti is the total number of new nodes that you will subdivide the edge into. Note that cnti == 0 means you will not subdivide the edge.
To subdivide the edge [ui, vi], replace it with (cnti + 1) new edges and cnti new nodes. The new nodes are x1, x2, ..., xcnti, and the new edges are [ui, x1], [x1, x2], [x2, x3], ..., [xcnti-1, xcnti], [xcnti, vi].
In this new graph, you want to know how many nodes are reachable from the node 0, where a node is reachable if the distance is maxMoves or less.
Given the original graph and maxMoves, return the number of nodes that are reachable from node 0 in the new graph.
Example 1:
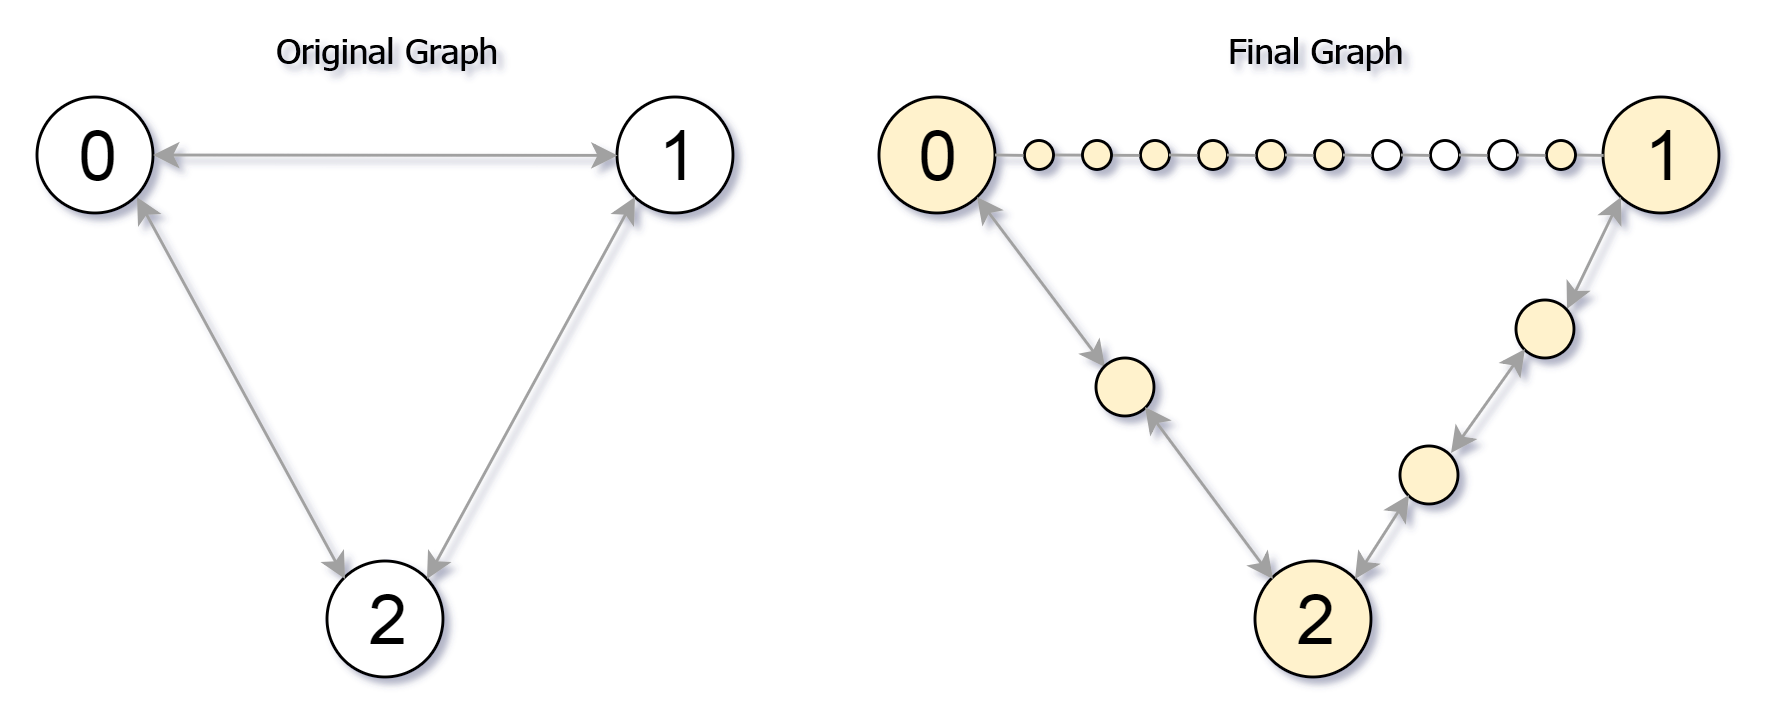
Input: edges = [[0,1,10],[0,2,1],[1,2,2]], maxMoves = 6, n = 3
Output: 13
Explanation: The edge subdivisions are shown in the image above.
The nodes that are reachable are highlighted in yellow.
Example 2:
Input: edges = [[0,1,4],[1,2,6],[0,2,8],[1,3,1]], maxMoves = 10, n = 4
Output: 23
Example 3:
Input: edges = [[1,2,4],[1,4,5],[1,3,1],[2,3,4],[3,4,5]], maxMoves = 17, n = 5
Output: 1
Explanation: Node 0 is disconnected from the rest of the graph, so only node 0 is reachable.
Constraints:
0 <= edges.length <= min(n * (n - 1) / 2, 104)edges[i].length == 30 <= ui < vi < n- There are no multiple edges in the graph.
0 <= cnti <= 1040 <= maxMoves <= 1091 <= n <= 3000
Approach overview
Problem Overview: You get an undirected graph where every edge is subdivided into multiple intermediate nodes. Starting from node 0 with maxMoves, count how many original and newly created nodes you can reach without exceeding the move limit.
Approach 1: Dijkstra's Algorithm on Logical Subdivisions (O(E log V) time, O(V + E) space)
Instead of explicitly building all subdivided nodes, treat each edge weight as the number of subdivisions. Run Dijkstra’s algorithm from node 0 using a max heap or priority queue that tracks remaining moves. When you traverse an edge, you consume moves equal to the number of subdivisions plus one to reach the neighbor. Even if you cannot reach the neighbor fully, you can still count partial progress along the subdivided nodes. Maintain how many new nodes were used on each edge from both directions and cap it by the subdivision count.
This approach avoids constructing potentially huge graphs. The algorithm only processes original nodes while logically accounting for intermediate ones. Works well because shortest remaining distance naturally determines how far you can travel along each edge. Uses techniques from shortest path and heap (priority queue) problems.
Approach 2: Depth First Search with Logical Path Expansion (O(E * maxMoves) time, O(V + E) space)
Perform DFS from node 0 while tracking remaining moves. Each recursive step attempts to move along edges and consume subdivisions step by step. If the remaining moves cannot reach the next original node, count only the intermediate nodes along that edge. Maintain a visited structure for edges so subdivided nodes are not double-counted when reached from both sides.
This approach models traversal more directly but becomes inefficient when maxMoves is large. DFS may repeatedly explore similar states. Useful mainly for reasoning about how subdivided nodes contribute to the final count.
Approach 3: Dijkstra on Explicitly Built Subdivided Graph (O((V + S) log (V + S)) time, O(V + S) space)
Construct the full graph where each edge with n subdivisions becomes a chain of n intermediate nodes. After building the expanded graph, run standard Dijkstra from node 0 and count nodes with distance ≤ maxMoves. This makes the logic simple but the graph size becomes huge because the number of new nodes equals the sum of all subdivisions.
This version demonstrates correctness clearly but is impractical for large inputs. It shows why treating subdivisions logically instead of physically is a key optimization when solving graph problems with implicit nodes.
Approach 4: Breadth-First Search with Move Tracking (O(E * maxMoves) time, O(V + E) space)
BFS can simulate movement layer by layer while tracking remaining steps. Each transition consumes part of the move budget along subdivided edges. Similar to DFS, it must track how many intermediate nodes have already been counted from each side of an edge. Because BFS does not prioritize shorter paths like Dijkstra, it may explore inefficient states when the graph has varying subdivision counts.
Recommended for interviews: Dijkstra’s algorithm with logical subdivision tracking. It keeps the graph small, guarantees optimal exploration order, and handles partial edge traversal cleanly. Interviewers expect candidates to recognize that explicitly building the subdivided graph is infeasible and that shortest-path logic solves the move constraint efficiently.
Approach 1: Dijkstra's Algorithm on Logical Subdivisions
We treat the problem as a shortest path problem. Each edge between nodes in the original graph may be subdivided logically without explicitly constructing all new nodes. We can utilize Dijkstra's algorithm to calculate the shortest paths starting from node 0, considering edge subdivisions.
import heapq

def reachableNodes(edges, maxMoves, n):
    graph = {i: {} for i in range(n)}
    for u, v, cnt in edges:
        graph[u][v] = cnt
        graph[v][u] = cnt
    pq = [(0, 0)]
    dist = {0: 0}
    result = 0
    used_edges = {}
    while pq:
        curr_dist, u = heapq.heappop(pq)
        if curr_dist > dist.get(u, float('inf')):
            continue
        result += 1
        for v, cnt in graph[u].items():
            v_dist = curr_dist + cnt + 1
            if v_dist <= maxMoves and v_dist < dist.get(v, float('inf')):
                dist[v] = v_dist
                heapq.heappush(pq, (v_dist, v))
            used_edges[(u, v)] = min(cnt, maxMoves - curr_dist)
    return result + sum(min(v1+v2, cnt) for (u, v), cnt in graph.items() for v1, v2 in [(used_edges.get((u, v), 0), used_edges.get((v, u), 0))])

# Example usage
# edges = [[0,1,10],[0,2,1],[1,2,2]]
# maxMoves = 6
# n = 3
# print(reachableNodes(edges, maxMoves, n))  # Output: 13
The function initializes a graph where each node points to a dictionary of its connected nodes treating cnt as weights for route expansion. This is reminiscent of representing weighted edges for pathfinding algorithms. We use a priority queue to maintain node distances akin to Dijkstra's algorithm, continually exploring until all reachable nodes are calculated within maxMoves.
Time Complexity: O(E + V log V), where E is the number of edges and V the number of vertices.
Space Complexity: O(E + V) for storing the graph and distances.
Approach 2: Depth First Search with Logical Path Expansion
Instead of explicitly constructing the whole subdivided graph, we utilize a DFS strategy. By expanding paths logically through recursion and considering move limits, we can calculate the number of reachable nodes without extra space overhead.
def reachableNodesDFS(edges, maxMoves, n):
    graph = {i: [] for i in range(n)}
    for u, v, cnt in edges:
        graph[u].append((v, cnt))
        graph[v].append((u, cnt))
    visited_nodes = set()
    def dfs(node, remaining_moves):
        if node in visited_nodes or remaining_moves < 0:
            return
        visited_nodes.add(node)
        for neighbor, cnt in graph[node]:
            allowable_traversal = min(cnt, remaining_moves)
            if allowable_traversal > 0:
                dfs(neighbor, remaining_moves - cnt - 1)
    dfs(0, maxMoves)
    result = len(visited_nodes) + \
        sum(min(cnt, sum(min(maxMoves - dist, cnt) for dist in [maxMoves - d for d in range(cnt+1)])) for u, v, cnt in edges)
    return result

# Example usage
# edges = [[0,1,4],[1,2,6],[0,2,8],[1,3,1]]
# maxMoves = 10
# n = 4
# print(reachableNodesDFS(edges, maxMoves, n))  # Output: 23
This solution builds an adjacency list to represent the graph. It applies a DFS approach, where each node recursively attempts to visit connected nodes, tracking nodes reached using a set. Subdivisions are not created explicitly, and instead, logical path expansion is calculated by allowable traversal of each edge within given maxMoves.
Time Complexity: O(V + E), where V is the number of vertices and E the number of edges, as it involves visiting nodes and edges logically.
Space Complexity: O(V + E) for adjacency list and visited set.
Approach 3: Dijkstra's Algorithm on Subdivided Graph
This approach involves using Dijkstra's algorithm to calculate the shortest distance from node 0 to all other nodes in the subdivided graph. The subdivision requires splitting each edge into a path with additional nodes. The priority queue maintains nodes sorted by distance, ensuring efficient processing of the shortest paths first.
from heapq import heappop, heappush

def reachable_nodes(edges, maxMoves, n):
    graph = {i: {} for i in range(n)}
    for u, v, cnt in edges:
        graph[u][v] = cnt
        graph[v][u] = cnt

    pq = [(0, 0)]  # (distance, node)
    dist = {0: 0}
    used = {}
    res = 0

    while pq:
        d, node = heappop(pq)
        if d > dist.get(node, 0):
            continue
        res += 1
        for nei, cnt in graph[node].items():
            v = min(cnt, maxMoves - d)
            used[node, nei] = v
            d2 = d + cnt + 1
            if d2 < dist.get(nei, float('inf')):
                heappush(pq, (d2, nei))
                dist[nei] = d2

    for u, v, cnt in edges:
        res += min(cnt, used.get((u, v), 0) + used.get((v, u), 0))

    return res

# Example usage:
# edges = [[0,1,10],[0,2,1],[1,2,2]], maxMoves = 6, n = 3
# print(reachable_nodes(edges, maxMoves, n)) # Output: 13#include <iostream>
#include <vector>
#include <queue>
#include <unordered_map>
#include <climits>
using namespace std;
int reachableNodes(vector<vector<int>>& edges, int maxMoves, int n) {
vector<unordered_map<int, int>> graph(n);
for (auto &edge : edges) {
int u = edge[0], v = edge[1], cnt = edge[2];
graph[u][v] = cnt;
graph[v][u] = cnt;
}
priority_queue<pair<int, int>, vector<pair<int, int>>, greater<pair<int, int>>> pq;
pq.push({0, 0});
vector<int> dist(n, INT_MAX);
dist[0] = 0;
unordered_map<int, int> used;
int res = 0;
while (!pq.empty()) {
auto [d, node] = pq.top(); pq.pop();
if (d > dist[node]) continue;
res++;
for (auto &[neighbor, cnt] : graph[node]) {
int v = min(cnt, maxMoves - d);
used[node * n + neighbor] = v;
int d2 = d + cnt + 1;
if (d2 < dist[neighbor]) {
dist[neighbor] = d2;
pq.push({d2, neighbor});
}
}
}
for (auto &edge : edges) {
int u = edge[0], v = edge[1], cnt = edge[2];
res += min(cnt, (used[u * n + v]) + (used[v * n + u]));
}
return res;
}
// Example usage:
// int main() {
// vector<vector<int>> edges = {{0,1,10},{0,2,1},{1,2,2}};
// int maxMoves = 6, n = 3;
// cout << reachableNodes(edges, maxMoves, n) << endl; // Output: 13
// return 0;
// }function reachableNodes(edges, maxMoves, n) {
const graph = Array.from({length: n}, () => ({}));
for (let [u, v, cnt] of edges) {
graph[u][v] = cnt;
graph[v][u] = cnt;
}
const pq = [[0, 0]];
const dist = Array(n).fill(Infinity);
dist[0] = 0;
const used = {};
let res = 0;
while (pq.length) {
const [d, node] = pq.shift();
if (d > dist[node]) continue;
res++;
for (const [neighbour, cnt] of Object.entries(graph[node])) {
const v = Math.min(cnt, maxMoves - d);
used[node * n + parseInt(neighbour)] = v;
const d2 = d + cnt + 1;
if (d2 < dist[neighbour]) {
dist[neighbour] = d2;
pq.push([d2, parseInt(neighbour)]);
pq.sort((a, b) => a[0] - b[0]);
}
}
}
for (let [u, v, cnt] of edges) {
res += Math.min(cnt, (used[u * n + v] || 0) + (used[v * n + u] || 0));
}
return res;
}
// Example usage:
// edges = [[0,1,10],[0,2,1],[1,2,2]], maxMoves = 6, n = 3
// console.log(reachableNodes(edges, maxMoves, n)); // Output: 13This Python implementation uses a priority queue (heap) to perform a modified Dijkstra's algorithm. The graph is built with adjacency lists where each node's neighbor's distance is stored. As we traverse the graph, we count the nodes within reach (incrementing result res). The 'dist' dictionary keeps the shortest known distance to each node from the starting node, and 'used' tracks how many new nodes we reach in subdivided edges. Finally, we sum up these used nodes for each edge in the given edges list to get the total reachable node count.
Time Complexity: O(E + N log N), where E is the number of edges and N is the number of nodes due to priority queue operations.
Space Complexity: O(N + E), for storing graph, distance, and used nodes mappings.
Approach 4: Alternative Approach - Breadth-First Search (BFS)
This approach employs BFS to explore the graph iteratively. Unlike Dijkstra, BFS is less concerned with path cost optimization and focuses on level-wise expansion. It's useful when all edge weights are equal. Here, edges must be handled considering additional costs per neighbor negotiation based on subdivided portions of the graph.
import java.util.*;

public class ReachableNodesBFS {
    public int reachableNodes(int[][] edges, int maxMoves, int n) {
        List<Map<Integer, Integer>> graph = new ArrayList<>();
        for (int i = 0; i < n; i++) graph.add(new HashMap<>());
        for (int[] edge : edges) {
            int u = edge[0], v = edge[1], cnt = edge[2];
            graph.get(u).put(v, cnt);
            graph.get(v).put(u, cnt);
        }

        Queue<int[]> q = new LinkedList<>();
        q.offer(new int[]{0, 0});
        int[] dist = new int[n];
        Arrays.fill(dist, Integer.MAX_VALUE);
        dist[0] = 0;
        int[] used = new int[n * n];
        int res = 0;

        while (!q.isEmpty()) {
            int[] curr = q.poll();
            int d = curr[0], node = curr[1];
            if (d > dist[node]) continue;
            res++;
            for (Map.Entry<Integer, Integer> neighbor : graph.get(node).entrySet()) {
                int nei = neighbor.getKey(), cnt = neighbor.getValue();
                int v = Math.min(cnt, maxMoves - d);
                used[node * n + nei] = v;
                int d2 = d + cnt + 1;
                if (d2 < dist[nei]) {
                    dist[nei] = d2;
                    q.offer(new int[]{d2, nei});
                }
            }
        }

        for (int[] edge : edges) {
            int u = edge[0], v = edge[1], cnt = edge[2];
            res += Math.min(cnt, used[u * n + v] + used[v * n + u]);
        }
        return res;
    }

    public static void main(String[] args) {
        ReachableNodesBFS solution = new ReachableNodesBFS();
        int[][] edges = {{0,1,4},{1,2,6},{0,2,8},{1,3,1}};
        int maxMoves = 10, n = 4;
        System.out.println(solution.reachableNodes(edges, maxMoves, n));  // Output: 23
    }
}using System;
using System.Collections.Generic;
public class ReachableNodes {
public int ReachableNodesWithBFS(int[][] edges, int maxMoves, int n) {
var graph = new Dictionary<int, Dictionary<int, int>>();
for (int i = 0; i < n; i++) graph[i] = new Dictionary<int, int>();
foreach (var edge in edges) {
int u = edge[0], v = edge[1], cnt = edge[2];
graph[u][v] = cnt;
graph[v][u] = cnt;
}
var q = new Queue<(int, int)>();
q.Enqueue((0, 0));
int[] dist = new int[n];
Array.Fill(dist, int.MaxValue);
dist[0] = 0;
var used = new Dictionary<(int, int), int>();
int res = 0;
while (q.Count > 0) {
var (d, node) = q.Dequeue();
if (d > dist[node]) continue;
res++;
foreach (var (nei, cnt) in graph[node]) {
int v = Math.Min(cnt, maxMoves - d);
if (!used.ContainsKey((node, nei)))
used[(node, nei)] = 0;
used[(node, nei)] = v;
int d2 = d + cnt + 1;
if (d2 < dist[nei]) {
dist[nei] = d2;
q.Enqueue((d2, nei));
}
}
}
foreach (var edge in edges) {
int u = edge[0], v = edge[1], cnt = edge[2];
res += Math.Min(cnt, used.GetValueOrDefault((u, v), 0) + used.GetValueOrDefault((v, u), 0));
}
return res;
}
public static void Main() {
var solution = new ReachableNodes();
int[][] edges = new int[][] { new[] { 0, 1, 4 }, new[] { 1, 2, 6 }, new[] { 0, 2, 8 }, new[] { 1, 3, 1 } };
int maxMoves = 10, n = 4;
Console.WriteLine(solution.ReachableNodesWithBFS(edges, maxMoves, n)); // Output: 23
}
}The Java solution explores combinations of reachable nodes using BFS. A queue is used to maintain exploration from the starting node iteratively. Each node's reachable distance is updated if a shorter path via a neighbor is discovered, counting reachable nodes based on the accumulated distance.
Time Complexity: O(E + N^2), due to BFS and operations at each node with the distance array update.
Space Complexity: O(N + E), capturing the adjacency list and additional structures like queue and distance array.
Approach 5: Default Approach
func reachableNodes(edges [][]int, maxMoves int, n int) (ans int) {
	g := make([][]pair, n)
	for _, e := range edges {
		u, v, cnt := e[0], e[1], e[2]+1
		g[u] = append(g[u], pair{cnt, v})
		g[v] = append(g[v], pair{cnt, u})
	}
	dist := make([]int, n)
	for i := range dist {
		dist[i] = 1 << 30
	}
	dist[0] = 0
	q := hp{{0, 0}}
	for len(q) > 0 {
		p := heap.Pop(&q).(pair)
		d, u := p.v, p.i
		for _, nxt := range g[u] {
			v, cnt := nxt.i, nxt.v
			if t := d + cnt; t < dist[v] {
				dist[v] = t
				heap.Push(&q, pair{t, v})
			}
		}
	}
	for _, d := range dist {
		if d <= maxMoves {
			ans++
		}
	}
	for _, e := range edges {
		u, v, cnt := e[0], e[1], e[2]
		a := min(cnt, max(0, maxMoves-dist[u]))
		b := min(cnt, max(0, maxMoves-dist[v]))
		ans += min(cnt, a+b)
	}
	return
}

type pair struct{ v, i int }
type hp []pair

func (h hp) Len() int           { return len(h) }
func (h hp) Less(i, j int) bool { return h[i].v < h[j].v }
func (h hp) Swap(i, j int)      { h[i], h[j] = h[j], h[i] }
func (h *hp) Push(v any)        { *h = append(*h, v.(pair)) }
func (h *hp) Pop() any { a := *h; v := a[len(a)-1]; *h = a[:len(a)-1]; return v }Complexity comparison
| Approach | Complexity |
|---|---|
| Dijkstra's Algorithm on Logical Subdivisions | Time Complexity: O(E + V log V), where E is the number of edges and V the number of vertices. |
| Depth First Search with Logical Path Expansion | Time Complexity: O(V + E), where V is the number of vertices and E the number of edges, as it involves visiting nodes and edges logically. |
| Dijkstra's Algorithm on Subdivided Graph | Time Complexity: O(E + N log N), where E is the number of edges and N is the number of nodes due to priority queue operations. |
| Alternative Approach - Breadth-First Search (BFS) | Time Complexity: O(E + N^2), due to BFS and operations at each node with the distance array update. |
| Default Approach | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Dijkstra's Algorithm on Logical Subdivisions | O(E log V) | O(V + E) | Best general solution; handles large subdivision counts efficiently |
| Depth First Search with Logical Path Expansion | O(E * maxMoves) | O(V + E) | Conceptual exploration of reachable nodes when constraints are small |
| Dijkstra on Explicitly Built Subdivided Graph | O((V + S) log (V + S)) | O(V + S) | Educational approach when the subdivided graph size is manageable |
| Breadth-First Search with Move Tracking | O(E * maxMoves) | O(V + E) | Works for small graphs or uniform edge costs |
Frequently asked questions
Is Reachable Nodes In Subdivided Graph easy or hard?
Reachable Nodes In Subdivided Graph is classified as Hard. The challenge comes from realizing that explicitly creating all subdivided nodes is infeasible and that the correct solution requires combining Dijkstra’s algorithm with partial edge traversal accounting.
Reachable Nodes In Subdivided Graph Python or Java solution?
Most implementations use Dijkstra with a heap. Python solutions typically rely on heapq with adjacency lists, while Java uses PriorityQueue and C++ uses priority_queue. The algorithmic structure remains the same across languages with O(E log V) complexity.
How to solve Reachable Nodes In Subdivided Graph in O(E log V)?
Run Dijkstra from node 0 to compute the shortest distance to each original node. For every edge (u, v, n), calculate how many subdivided nodes can be reached from both endpoints using the remaining moves. The total reachable nodes equal reachable original nodes plus the minimum of n and the sum of partial traversals from u and v.
What is the best approach for Reachable Nodes In Subdivided Graph?
Dijkstra’s algorithm with logical subdivision tracking is the most efficient approach. Instead of building every intermediate node, treat the subdivision count as edge weight and compute the shortest distance from node 0. Then count how many subdivided nodes can be consumed from each edge based on remaining moves. The complexity is O(E log V).
Is Reachable Nodes In Subdivided Graph asked at Google/Amazon/Meta?
Reachable Nodes In Subdivided Graph is a Hard graph problem commonly used to test shortest-path reasoning and priority queue usage. Variants of this problem appear in interviews at companies like Google, Amazon, and Meta when evaluating advanced graph traversal and optimization skills.
What data structure is used in Reachable Nodes In Subdivided Graph?
The core data structure is a priority queue (heap) used in Dijkstra’s shortest path algorithm. An adjacency list stores the graph, and hash maps or arrays track distances and how many subdivided nodes are used along each edge.
What is the time complexity of Reachable Nodes In Subdivided Graph?
The optimal solution using Dijkstra’s algorithm runs in O(E log V) time and O(V + E) space. Each edge is processed through a priority queue while computing the maximum reachable distance within maxMoves. Additional bookkeeping tracks how many subdivided nodes are used per edge.