Rank Transform of a Matrix solution and explanation
 Google

9 more videos on this problem
 Leetcode 1632. Rank Transform of a MatrixFraz · 25:21 · 9K views
 Coordinate Compression, LC 1632 Rank Transform of a MatrixErrichto Hard Algorithms · 1:12:55 · 7K views
 rank-transform-of-a-matrix || LeetcodePepcoding · 42:23 · 6K views
 LeetCode 1632. Rank Transform of a MatrixHappy Coding · 33:59 · 3K views
 Rank Transform of a Matrix | Disjoint Set Union | 1632 LeetCode | Day 08CodeWithSunny · 27:46 · 2K views
 Rank Transform of a Matrix Simply Explained DSU/UF Solution in Python3Tanishq Chaudhary · 21:01 · 1K views
 【每日一题】1632. Rank Transform of a Matrix, 10/26/2020Huifeng Guan · 59:41 · 1K views
 LeetCode 1632. Rank Transform of a MatrixAbrar & Software Engineering · 18:50 · 1K views
 1632. Rank Transform of a Matrix (Leetcode Hard)Programming Live with Larry · 2:05:33 · 551 views
 Daily Leetcode #495: Aug 08, 2021 - 1632. Rank Transform of a MatrixProgramming Live with Larry · 1:22:42 · 478 views
The problem
Given an m x n matrix, return a new matrix answer where answer[row][col] is the rank of matrix[row][col].
The rank is an integer that represents how large an element is compared to other elements. It is calculated using the following rules:
- The rank is an integer starting from
1. - If two elements
pandqare in the same row or column, then:- If
p < qthenrank(p) < rank(q) - If
p == qthenrank(p) == rank(q) - If
p > qthenrank(p) > rank(q)
- If
- The rank should be as small as possible.
The test cases are generated so that answer is unique under the given rules.
Example 1:
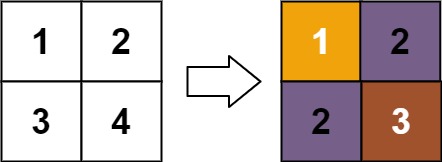
Input: matrix = [[1,2],[3,4]]
Output: [[1,2],[2,3]]
Explanation:
The rank of matrix[0][0] is 1 because it is the smallest integer in its row and column.
The rank of matrix[0][1] is 2 because matrix[0][1] > matrix[0][0] and matrix[0][0] is rank 1.
The rank of matrix[1][0] is 2 because matrix[1][0] > matrix[0][0] and matrix[0][0] is rank 1.
The rank of matrix[1][1] is 3 because matrix[1][1] > matrix[0][1], matrix[1][1] > matrix[1][0], and both matrix[0][1] and matrix[1][0] are rank 2.
Example 2:
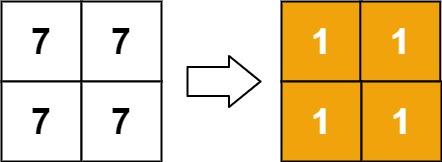
Input: matrix = [[7,7],[7,7]]
Output: [[1,1],[1,1]]
Example 3:
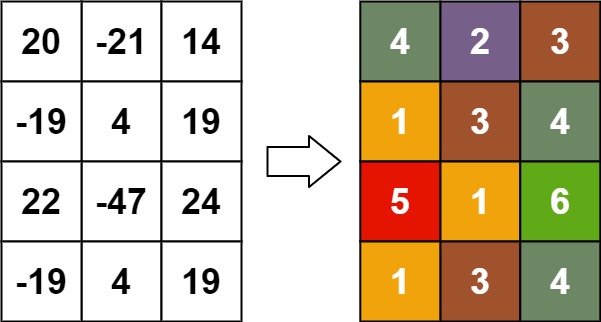
Input: matrix = [[20,-21,14],[-19,4,19],[22,-47,24],[-19,4,19]]
Output: [[4,2,3],[1,3,4],[5,1,6],[1,3,4]]
Constraints:
m == matrix.lengthn == matrix[i].length1 <= m, n <= 500-109 <= matrix[row][col] <= 109
Approach overview
Problem Overview: Given an m x n matrix, assign a rank to every cell. A cell’s rank depends on its value relative to other cells in the same row or column. If two cells share the same value and are connected through rows or columns, they must receive the same rank. Larger values must receive strictly larger ranks than smaller ones within the same row or column.
Approach 1: Sorting Rows and Columns (O(mn log(mn)) time, O(mn) space)
Start by sorting all cells by value. Process values in increasing order so smaller elements establish rank constraints first. For each value group, inspect the maximum rank already assigned in its row and column, then assign rank = max(rowRank, colRank) + 1. Update row and column rank trackers after assigning ranks. This approach is straightforward but requires careful handling when multiple cells share the same value to avoid violating equality constraints. It relies mainly on sorting and row/column bookkeeping.
Approach 2: Coordinate Compression with Union-Find (O(mn log(mn)) time, O(mn) space)
Cells with the same value that share a row or column must have identical ranks. Build groups using Union-Find. For each distinct value, connect its row index and column index in a disjoint set. This forms components representing cells that must share rank. After grouping, compute the rank for each component using the maximum rank already assigned to involved rows and columns. Sorting the values ensures constraints propagate correctly from smaller numbers to larger ones. This approach handles equality relationships cleanly and is widely considered the canonical solution.
Approach 3: Union-Find and Coordinate Compression (O(mn log(mn)) time, O(mn) space)
Another implementation of the same core idea compresses row and column indices into a single coordinate space and unions them when a cell appears. Processing values in sorted order ensures dependencies are resolved first. Each connected component represents a set of equal-valued cells tied by row/column relations. Compute the component rank using previously recorded row and column maximum ranks. This variant simplifies mapping and improves implementation clarity when working with arrays and large matrices.
Approach 4: BFS Rank Propagation (O(mn log(mn)) time, O(mn) space)
Model the problem as a graph where nodes represent rows and columns. Cells with the same value create edges between their row and column nodes. For each value group, build connected components and run BFS to propagate the rank constraint across the component. The rank assigned equals one more than the maximum rank already present among participating rows and columns. This approach resembles graph traversal and sometimes appears alongside topological ordering explanations because ranks must respect dependency ordering.
Recommended for interviews: The Union-Find with coordinate compression approach is what most interviewers expect. It cleanly handles equal-value constraints and demonstrates strong understanding of disjoint sets and dependency ordering. A basic sorting-based attempt shows you understand the row/column rank rule, but the optimized Union-Find solution proves you can model relationships between matrix elements efficiently.
Approach 1: Union-Find and Coordinate Compression
This approach utilizes the Union-Find data structure to associate ranks across the same row and column when we process elements in increasing order. We use coordinate compression to ensure that elements are processed efficiently by their unique values in increasing order. The process maintains a rank per element while ensuring rank relationships across the matrix.
def matrixRankTransform(matrix):
    import collections

    def find(v):
        if parent[v] != v:
            parent[v] = find(parent[v])
        return parent[v]

    def union(v1, v2):
        root1 = find(v1)
        root2 = find(v2)
        if root1 != root2:
            if rank[root1] > rank[root2]:
                parent[root2] = root1
            else:
                parent[root1] = root2
                if rank[root1] == rank[root2]:
                    rank[root2] += 1

    m, n = len(matrix), len(matrix[0])
    rank_map = collections.defaultdict(list)
    for r in range(m):
        for c in range(n):
            rank_map[matrix[r][c]].append((r, c))

    result = [[0] * n for _ in range(m)]
    row_max, col_max = [0] * m, [0] * n

    for value in sorted(rank_map):
        parent = {}
        rank = {}

        for r, c in rank_map[value]:
            key = (r, c)
            parent[key] = key
            rank[key] = 0

        for r, c in rank_map[value]:
            if r > 0 and matrix[r-1][c] == value:
                union((r-1, c), (r, c))
            if c > 0 and matrix[r][c-1] == value:
                union((r, c-1), (r, c))

        rank_set = collections.defaultdict(list)
        for r, c in rank_map[value]:
            root = find((r, c))
            rank_set[root].append((r, c))

        for group in rank_set.values():
            max_rank = 0
            for r, c in group:
                max_rank = max(max_rank, row_max[r], col_max[c])
            new_rank = max_rank + 1
            for r, c in group:
                result[r][c] = new_rank
                row_max[r] = new_rank
                col_max[c] = new_rank

    return result
The solution defines a clustering strategy using a union-find structure with path compression and union by rank. Elements in the matrix are grouped based on their values and are processed by increasing order of the element value. For each value, rows and columns are traversed to determine minimal ranks possible, and these ranks are then assigned to the rows and columns. The algorithm utilizes a union-find to merge similar values found in previous and subsequent cells of the matrix.
Time Complexity: O(m * n * log(m * n)), where m and n are the dimensions of the matrix. The log factor comes from union-find operations.
Space Complexity: O(m * n), due to the storage demands of the union-find structure and result matrix.
Approach 2: Sorting Rows and Columns
We can also solve this problem using a greedy strategy where each value is processed independently by sorting rows and columns. This involves sorting and updating ranks based on maintaining column and row data separately with sorting. This technique ensures an optimal rank assignment at each step by having separate row and column maximum rank tracking.
function matrixRankTransform(matrix) {
    const m = matrix.length, n = matrix[0].length;
    const rank = new Array(m + n).fill(0);
    const answer = Array.from({ length: m }, () => Array(n).fill(0));
    const valueCells = [];

    for (let r = 0; r < m; r++) {
        for (let c = 0; c < n; c++) {
            valueCells.push([matrix[r][c], r, c]);
        }
    }

    valueCells.sort((a, b) => a[0] - b[0]);

    let uf = new UnionFind(m + n);
    for (let i = 0; i < valueCells.length; ) {
        let j = i;
        while (j < valueCells.length && valueCells[j][0] === valueCells[i][0]) {
            const [_, r, c] = valueCells[j];
            uf.union(r, c + m);
            j++;
        }

        const parentToRank = new Map();
        for (let k = i; k < j; k++) {
            const [_, r, c] = valueCells[k];
            const root = uf.find(r);
            const rankVal = Math.max(rank[r], rank[c + m]);
            if (!parentToRank.has(root)) {
                parentToRank.set(root, rankVal);
            } else {
                parentToRank.set(root, Math.max(parentToRank.get(root), rankVal));
            }
        }

        for (let k = i; k < j; k++) {
            const [_, r, c] = valueCells[k];
            const root = uf.find(r);
            answer[r][c] = parentToRank.get(root) + 1;
            rank[r] = answer[r][c];
            rank[c + m] = answer[r][c];
        }

        i = j;
        uf.reset();
    }

    return answer;
}

class UnionFind {
    constructor(size) {
        this.parent = Array.from({ length: size }, (_, i) => i);
    }

    find(x) {
        if (this.parent[x] !== x) {
            this.parent[x] = this.find(this.parent[x]);
        }
        return this.parent[x];
    }

    union(x, y) {
        this.parent[this.find(x)] = this.find(y);
    }

    reset() {
        this.parent = this.parent.map((_, i) => i);
    }
}
The JavaScript solution involves sorting all entries by their values and unionizing their row and column indices. With each group of same-value entries, maximum possible ranks are assigned based on the leading rank values of rows and columns. The unique ranks are formed by later tracking the maximum of the unions established and annotated back to the full matrix grid.
Time Complexity: O(m * n * log(m * n)) because of sorting and complexity from the union-find operations.
Space Complexity: O(m + n) for union-find operation manipulation and storage for returned results.
Approach 3: Approach 1: Coordinate Compression with Union-Find
This approach uses coordinate compression with a union-find data structure to efficiently calculate ranks. By representing elements, their row and column constraints via sets, we can manage ranks dynamically as we process elements from smallest to largest.
def matrixRankTransform(matrix):
    from collections import defaultdict
    import heapq

    row_size, col_size = len(matrix), len(matrix[0])
    rank = [0] * (row_size + col_size)

    d = defaultdict(list)
    for r in range(row_size):
        for c in range(col_size):
            d[matrix[r][c]].append((r, c))

    sorted_keys = sorted(d.keys())

    answer = [[0] * col_size for _ in range(row_size)]

    for key in sorted_keys:
        rank_temp = rank[:]
        for (r, c) in d[key]:
            rank_temp[r] = max(rank_temp[r], rank[r - row_size + col_size]) + 1
            rank_temp[c + row_size] = max(rank_temp[c + row_size], rank[r - row_size + col_size]) + 1

        uf = {}  # Union-Find for merging equal elements in the same rows/cols
        for (r, c) in d[key]:
            root_r = find(r, uf)
            root_c = find(c + row_size, uf)
            if root_r != root_c:
                uf[root_c] = root_r
            union_val = rank_temp[r]
            answer[r][c] = union_val
            rank_temp[r] = rank_temp[c + row_size] = union_val

        rank = rank_temp
    return answer


def find(x, uf):
    if x != uf.get(x, x):
        uf[x] = find(uf[x], uf)
return uf.get(x, x)function matrixRankTransform(matrix) {
const m = matrix.length, n = matrix[0].length;
const positionMap = new Map();
for (let r = 0; r < m; r++) {
for (let c = 0; c < n; c++) {
if (!positionMap.has(matrix[r][c])) {
positionMap.set(matrix[r][c], []);
}
positionMap.get(matrix[r][c]).push([r, c]);
}
}
const uniqueKeys = Array.from(positionMap.keys()).sort((a, b) => a - b);
const rank = new Array(m + n).fill(0);
const answer = Array.from(new Array(m), () => new Array(n).fill(0));
for (const key of uniqueKeys) {
const parent = new Map();
const find = (node) => {
if (!parent.has(node)) {
parent.set(node, node);
}
if (node != parent.get(node)) {
const root = find(parent.get(node));
parent.set(node, root);
return root;
}
return node;
};
const union = (a, b) => {
const rootA = find(a);
const rootB = find(b);
if (rootA != rootB) {
parent.set(rootA, rootB);
}
};
const rankTemp = rank.slice();
for (const [r, c] of positionMap.get(key)) {
rankTemp[r] = Math.max(rankTemp[r], rankTemp[c + m]) + 1;
rankTemp[c + m] = rankTemp[r];
union(r, c + m);
}
for (const [r, c] of positionMap.get(key)) {
const root = find(r);
const currRank = rankTemp[root];
answer[r][c] = currRank;
rank[r] = Math.max(rank[r], currRank);
rank[c + m] = rank[r];
}
}
return answer;
}This solution sorts elements and processes them using a union-find algorithm to ensure that all elements with the same value and in the same row or column receive the same rank. It keeps track of the maximum rank imposed by previous elements in a separate array and updates these in the union-find process.
Time Complexity: O((m * n) log(m * n)) due to sorting, and space complexity is O(m * n) for storing ranks and unions.
Approach 4: Approach 2: BFS Rank Propagation
This approach employs a Breadth-First Search (BFS) strategy to propagate the ranks throughout the matrix. By utilizing a leveling mechanism, where each element will check its neighbors and assign the rank based on the relative position, the implementation aims to be more intuitive.
import java.util.*;

class Solution {
    public int[][] matrixRankTransform(int[][] matrix) {
        int m = matrix.length, n = matrix[0].length;
        int[][] result = new int[m][n];
        Map<Integer, Integer>[] rowMap = new Map[m];
        Map<Integer, Integer>[] colMap = new Map[n];
        for (int i = 0; i < m; i++) rowMap[i] = new HashMap<>();
        for (int i = 0; i < n; i++) colMap[i] = new HashMap<>();
        Queue<int[]>[] queues = new LinkedList[1001];
        for (int i = 0; i <= 1000; i++) queues[i] = new LinkedList<>();

        for (int i = 0; i < m; i++) {
            for (int j = 0; j < n; j++) {
                queues[matrix[i][j] + 500].offer(new int[]{i, j});
            }
        }

        for (int val = -500; val <= 500; ++val) {
            Queue<int[]> currentQueue = queues[val + 500];
            while (!currentQueue.isEmpty()) {
                int[] p = currentQueue.poll();
                int r = p[0], c = p[1];

                int rank = Math.max(rowMap[r].getOrDefault(val, 0), colMap[c].getOrDefault(val, 0)) + 1;
                result[r][c] = rank;

                rowMap[r].put(val, Math.max(rowMap[r].getOrDefault(val, 0), rank));
                colMap[c].put(val, Math.max(colMap[c].getOrDefault(val, 0), rank));
            }
        }
        return result;
    }
}#include <vector>
#include <queue>
#include <algorithm>
#include <unordered_map>
#include <utility>
using namespace std;
vector<vector<int>> matrixRankTransform(vector<vector<int>>& matrix) {
int m = matrix.size(), n = matrix[0].size();
vector<vector<int>> result(m, vector<int>(n, 0));
vector<unordered_map<int, int>> row(m), col(n);
vector<queue<pair<int, int>>> queues(1001);
for (int i = 0; i < m; ++i)
for (int j = 0; j < n; ++j)
queues[matrix[i][j] + 500].push({i, j});
for (int val = -500; val <= 500; ++val) {
auto& currQueue = queues[val + 500];
while (!currQueue.empty()) {
auto [r, c] = currQueue.front(); currQueue.pop();
int rank = max(row[r][val], col[c][val]) + 1;
result[r][c] = rank;
row[r][val] = max(row[r][val], rank);
col[c][val] = max(col[c][val], rank);
}
}
return result;
}Java employs the same queue methodology relying on alignment with canonical ranges (-500 .. 500 offset index). Each cell's neighbors propagate their rank influences causing an iterative resolution through the matrix values in a nearly natural sorting order.
Time Complexity: O(m * n), as all matrix cells are seen in one pass akin to counting sort, with constant complexity for the range of values. Space Complexity: O(m + n) for rowMap and colMap holding last row and col ranks associations individually.
Approach 5: Default Approach
type unionFind struct {
	p, size []int
}

func newUnionFind(n int) *unionFind {
	p := make([]int, n)
	size := make([]int, n)
	for i := range p {
		p[i] = i
		size[i] = 1
	}
	return &unionFind{p, size}
}

func (uf *unionFind) find(x int) int {
	if uf.p[x] != x {
		uf.p[x] = uf.find(uf.p[x])
	}
	return uf.p[x]
}

func (uf *unionFind) union(a, b int) {
	pa, pb := uf.find(a), uf.find(b)
	if pa != pb {
		if uf.size[pa] > uf.size[pb] {
			uf.p[pb] = pa
			uf.size[pa] += uf.size[pb]
		} else {
			uf.p[pa] = pb
			uf.size[pb] += uf.size[pa]
		}
	}
}

func (uf *unionFind) reset(x int) {
	uf.p[x] = x
	uf.size[x] = 1
}

func matrixRankTransform(matrix [][]int) [][]int {
	m, n := len(matrix), len(matrix[0])
	type pair struct{ i, j int }
	d := map[int][]pair{}
	for i, row := range matrix {
		for j, v := range row {
			d[v] = append(d[v], pair{i, j})
		}
	}
	rowMax := make([]int, m)
	colMax := make([]int, n)
	ans := make([][]int, m)
	for i := range ans {
		ans[i] = make([]int, n)
	}
	vs := []int{}
	for v := range d {
		vs = append(vs, v)
	}
	sort.Ints(vs)
	uf := newUnionFind(m + n)
	rank := make([]int, m+n)
	for _, v := range vs {
		ps := d[v]
		for _, p := range ps {
			uf.union(p.i, p.j+m)
		}
		for _, p := range ps {
			i, j := p.i, p.j
			rank[uf.find(i)] = max(rank[uf.find(i)], max(rowMax[i], colMax[j]))
		}
		for _, p := range ps {
			i, j := p.i, p.j
			ans[i][j] = 1 + rank[uf.find(i)]
			rowMax[i], colMax[j] = ans[i][j], ans[i][j]
		}
		for _, p := range ps {
			uf.reset(p.i)
			uf.reset(p.j + m)
		}
	}
	return ans
}Complexity comparison
| Approach | Complexity |
|---|---|
| Union-Find and Coordinate Compression | Time Complexity: O(m * n * log(m * n)), where m and n are the dimensions of the matrix. The log factor comes from union-find operations. |
| Sorting Rows and Columns | Time Complexity: O(m * n * log(m * n)) because of sorting and complexity from the union-find operations. |
| Approach 1: Coordinate Compression with Union-Find | Time Complexity: O((m * n) log(m * n)) due to sorting, and space complexity is O(m * n) for storing ranks and unions. |
| Approach 2: BFS Rank Propagation | Time Complexity: O(m * n), as all matrix cells are seen in one pass akin to counting sort, with constant complexity for the range of values. Space Complexity: O(m + n) for rowMap and colMap holding last row and col ranks associations individually. |
| Default Approach | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Sorting Rows and Columns | O(mn log(mn)) | O(mn) | Good for understanding the ranking rule and dependency ordering before introducing union-find. |
| Coordinate Compression with Union-Find | O(mn log(mn)) | O(mn) | Best general solution when equal values must share ranks across rows and columns. |
| Union-Find and Coordinate Compression | O(mn log(mn)) | O(mn) | Cleaner implementation when mapping rows and columns into a single union-find structure. |
| BFS Rank Propagation | O(mn log(mn)) | O(mn) | Useful when modeling the problem as a graph and propagating rank constraints through components. |
Frequently asked questions
Is Rank Transform of a Matrix easy or hard?
Rank Transform of a Matrix is classified as Hard. The difficulty comes from handling equal-value constraints across rows and columns while maintaining correct ordering for larger values. Efficient solutions require combining sorting with union-find or graph traversal techniques.
Rank Transform of a Matrix Python/Java solution
Python implementations commonly use Union-Find with dictionaries or arrays to manage row and column ranks. Java solutions often follow the same structure using DSU classes and sorted lists of cells. Both achieve O(mn log(mn)) time complexity and O(mn) extra space.
How to solve Rank Transform of a Matrix in O(mn log(mn))?
Sort all cells by value and process them in increasing order. For cells with the same value, union their row and column nodes to form components. Compute the rank for each component using the maximum rank previously assigned to its rows or columns, then update those ranks. This guarantees consistent ranks while respecting ordering constraints.
What is the best approach for Rank Transform of a Matrix?
Union-Find with coordinate compression is the most reliable approach. Process matrix values in sorted order and group equal values connected by rows or columns using a disjoint set. Each group receives a rank based on the maximum existing rank in its rows or columns plus one. This method runs in O(mn log(mn)) time and handles equality constraints correctly.
Is Rank Transform of a Matrix asked at Google/Amazon/Meta?
Matrix ranking and constraint propagation problems appear in interviews at companies like Google, Amazon, and Meta. Variants often combine union-find, graph modeling, and sorting. The problem tests your ability to manage dependencies across rows and columns efficiently.
What data structure is used in Rank Transform of a Matrix?
The key data structure is Union-Find (Disjoint Set Union) to group cells with equal values that share rows or columns. Additional structures include hash maps for value grouping and arrays to track the maximum rank for each row and column. Some solutions also model the matrix as a graph for BFS traversal.
What is the time complexity of Rank Transform of a Matrix?
The optimal solutions run in O(mn log(mn)) time where m and n are matrix dimensions. The log factor comes from sorting all cells by value. Union-Find operations are nearly constant due to path compression, keeping the overall complexity dominated by sorting.