K Highest Ranked Items Within a Price Range solution and explanation

5 more videos on this problem
 2146 K Highest Ranked Items Within a Price Range | LeetCode 2146 || BiWeekly- 70 || Graph || BFS ||Bro Coders · 19:57 · 1K views
 K Highest Ranked Items Within a Price Range | LeetCode | Biweekly Contest 70We are Coders · 5:30 · 1K views
 K Highest Ranked Items Within a Price Range | Leetcode 2146 | BI-Weekly Contest 70 Solution | JavaPepcoding · 29:42 · 630 views
 2146. K Highest Ranked Items Within a Price Range (Leetcode Medium)Programming Live with Larry · 14:37 · 527 views
 2146. K Highest Ranked Items Within a Price Range || Leetcode Biweekly Contest 70 || C++ || BFS 🔥Ankit · 7:40 · 136 views
 LeetCode 2146: K Highest Ranked Items Within a Price RangeAlitaCode · 32:40 · 4 views
The problem
You are given a 0-indexed 2D integer array grid of size m x n that represents a map of the items in a shop. The integers in the grid represent the following:
0represents a wall that you cannot pass through.1represents an empty cell that you can freely move to and from.- All other positive integers represent the price of an item in that cell. You may also freely move to and from these item cells.
It takes 1 step to travel between adjacent grid cells.
You are also given integer arrays pricing and start where pricing = [low, high] and start = [row, col] indicates that you start at the position (row, col) and are interested only in items with a price in the range of [low, high] (inclusive). You are further given an integer k.
You are interested in the positions of the k highest-ranked items whose prices are within the given price range. The rank is determined by the first of these criteria that is different:
- Distance, defined as the length of the shortest path from the
start(shorter distance has a higher rank). - Price (lower price has a higher rank, but it must be in the price range).
- The row number (smaller row number has a higher rank).
- The column number (smaller column number has a higher rank).
Return the k highest-ranked items within the price range sorted by their rank (highest to lowest). If there are fewer than k reachable items within the price range, return all of them.
Example 1:
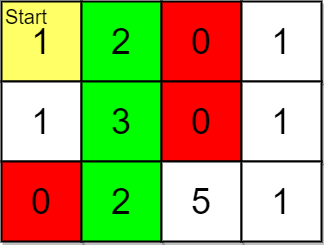
Input: grid = [[1,2,0,1],[1,3,0,1],[0,2,5,1]], pricing = [2,5], start = [0,0], k = 3
Output: [[0,1],[1,1],[2,1]]
Explanation: You start at (0,0).
With a price range of [2,5], we can take items from (0,1), (1,1), (2,1) and (2,2).
The ranks of these items are:
- (0,1) with distance 1
- (1,1) with distance 2
- (2,1) with distance 3
- (2,2) with distance 4
Thus, the 3 highest ranked items in the price range are (0,1), (1,1), and (2,1).
Example 2:
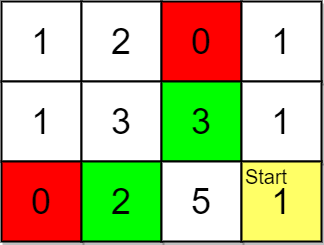
Input: grid = [[1,2,0,1],[1,3,3,1],[0,2,5,1]], pricing = [2,3], start = [2,3], k = 2
Output: [[2,1],[1,2]]
Explanation: You start at (2,3).
With a price range of [2,3], we can take items from (0,1), (1,1), (1,2) and (2,1).
The ranks of these items are:
- (2,1) with distance 2, price 2
- (1,2) with distance 2, price 3
- (1,1) with distance 3
- (0,1) with distance 4
Thus, the 2 highest ranked items in the price range are (2,1) and (1,2).
Example 3:
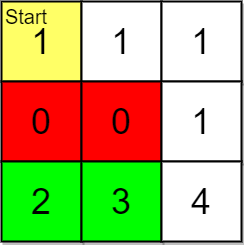
Input: grid = [[1,1,1],[0,0,1],[2,3,4]], pricing = [2,3], start = [0,0], k = 3
Output: [[2,1],[2,0]]
Explanation: You start at (0,0).
With a price range of [2,3], we can take items from (2,0) and (2,1).
The ranks of these items are:
- (2,1) with distance 5
- (2,0) with distance 6
Thus, the 2 highest ranked items in the price range are (2,1) and (2,0).
Note that k = 3 but there are only 2 reachable items within the price range.
Constraints:
m == grid.lengthn == grid[i].length1 <= m, n <= 1051 <= m * n <= 1050 <= grid[i][j] <= 105pricing.length == 22 <= low <= high <= 105start.length == 20 <= row <= m - 10 <= col <= n - 1grid[row][col] > 01 <= k <= m * n
Approach overview
Problem Overview: You start at a position in a grid representing a store. Each cell contains a price or a wall. The task is to find the k highest ranked items whose prices fall within a given range. Ranking follows strict rules: shortest distance from the start first, then lower price, then smaller row index, then smaller column index.
Approach 1: Breadth-First Search (BFS) with Sorting (Time: O(mn log(mn)), Space: O(mn))
The grid behaves like an unweighted graph, so Breadth-First Search naturally finds cells in order of increasing distance from the start. Traverse the grid using BFS while tracking visited cells. Whenever you encounter a cell whose value falls within the price range, store it along with its ranking attributes: distance, price, row, and column. After the traversal finishes, sort the collected candidates using the ranking rules and return the first k positions. Sorting ensures the correct ordering across all valid items.
This approach is straightforward and easy to reason about. BFS guarantees correct distance ordering, while a final sorting step resolves ties using price and coordinates. The downside is that you may collect many candidates and then sort them, which increases the overall cost.
Approach 2: BFS with Priority Queue (Time: O(mn log k), Space: O(mn))
This method still uses BFS to explore the matrix in increasing distance order, but instead of storing every candidate, it maintains a bounded priority queue. During traversal, each valid item is pushed into the heap with its ranking tuple (distance, price, row, col). If the heap grows larger than k, remove the lowest priority element according to the ranking rules. This keeps only the best k candidates while scanning the grid.
Because the heap never stores more than k elements, insertion and removal cost O(log k). The BFS still touches each reachable cell once, but the ranking maintenance becomes more efficient than sorting all candidates at the end.
Recommended for interviews: Start by explaining the BFS traversal since the grid is an unweighted graph and distance is the primary ranking factor. The BFS + sorting approach clearly demonstrates the ranking logic and is easy to implement. The BFS with a priority queue is the more optimized solution and shows stronger algorithmic thinking, especially when the grid contains many candidate items but only a small k is required.
Approach 1: Breadth-First Search (BFS) with Sorting
This approach involves using BFS to navigate through the grid starting from the given 'start' position. During the BFS, calculate the distance of each item from the start and filter based on the price range. Once the valid items are identified, sort them according to the criteria specified (distance, price, row, column) and pick the top k items.
import heapq
from collections import deque

def k_highest_ranked_items(grid, pricing, start, k):
    m, n = len(grid), len(grid[0])
    low, high = pricing
    start_x, start_y = start
    directions = [(1, 0), (-1, 0), (0, 1), (0, -1)]
    queue = deque([(start_x, start_y, 0)])  # (x, y, distance)
    visited = set()
    visited.add((start_x, start_y))
    items = []

    while queue:
        x, y, distance = queue.popleft()

        if low <= grid[x][y] <= high:
            heapq.heappush(items, (distance, grid[x][y], x, y))

        for dx, dy in directions:
            nx, ny = x + dx, y + dy
            if 0 <= nx < m and 0 <= ny < n and (nx, ny) not in visited and grid[nx][ny] != 0:
                visited.add((nx, ny))
                queue.append((nx, ny, distance + 1))

    result = []
    while items and len(result) < k:
        result.append(heapq.heappop(items)[2:])

return resultfunction kHighestRankedItems(grid, pricing, start, k) {
const [low, high] = pricing;
const [startRow, startCol] = start;
const m = grid.length, n = grid[0].length;
const directions = [[1, 0], [-1, 0], [0, 1], [0, -1]];
const queue = [[startRow, startCol, 0]]; // x, y, distance
const visited = new Set([startRow * n + startCol]);
const items = [];
while (queue.length) {
const [x, y, distance] = queue.shift();
if (grid[x][y] >= low && grid[x][y] <= high) {
items.push([distance, grid[x][y], x, y]);
}
for (const [dx, dy] of directions) {
const nx = x + dx, ny = y + dy;
if (nx >= 0 && nx < m && ny >= 0 && ny < n && !visited.has(nx * n + ny) && grid[nx][ny] !== 0) {
visited.add(nx * n + ny);
queue.push([nx, ny, distance + 1]);
}
}
}
items.sort((a, b) =>
a[0] - b[0] || a[1] - b[1] || a[2] - b[2] || a[3] - b[3]
);
return items.slice(0, k).map(([, , x, y]) => [x, y]);
}The Python solution uses a deque for the BFS queue to ensure efficient popping from the left. We use a priority queue (min-heap) to keep track of items based on the ranking criteria, storing tuples of the form (distance, price, x-coordinate, y-coordinate). The result list is constructed by popping the top k items from the heap.
Time Complexity: O(m * n * log(m * n)), as we potentially explore each cell and sort up to m * n items.
Space Complexity: O(m * n), due to additional space for queues and visited tracking.
Approach 2: Breadth-First Search with Priority Queue
This approach combines BFS with a priority queue to dynamically maintain the top k items. As we perform BFS, items are immediately added to the priority queue with the necessary criteria for comparison, maintaining only the top k items efficiently without needing to sort all possible items at the end.
import java.util.*;

public List<List<Integer>> kHighestRankedItems(int[][] grid, int[] pricing, int[] start, int k) {
    int m = grid.length, n = grid[0].length;
    int low = pricing[0], high = pricing[1];
    int startX = start[0], startY = start[1];
    int[][] directions = {{1, 0}, {-1, 0}, {0, 1}, {0, -1}};

    PriorityQueue<int[]> pq = new PriorityQueue<>((a, b) ->
        a[0] != b[0] ? a[0] - b[0] : (a[1] != b[1] ? a[1] - b[1] : (a[2] != b[2] ? a[2] - b[2] : a[3] - b[3]))));
    Queue<int[]> queue = new ArrayDeque<>();
    boolean[][] visited = new boolean[m][n];

    queue.add(new int[]{startX, startY, 0});
    visited[startX][startY] = true;

    while (!queue.isEmpty()) {
        int[] current = queue.poll();
        int x = current[0], y = current[1], dist = current[2];

        if (grid[x][y] <= high && grid[x][y] >= low) {
            pq.offer(new int[]{dist, grid[x][y], x, y});
            if (pq.size() > k) pq.poll();
        }

        for (int[] dir : directions) {
            int nx = x + dir[0], ny = y + dir[1];
            if (nx >= 0 && nx < m && ny >= 0 && ny < n && !visited[nx][ny] && grid[nx][ny] != 0) {
                visited[nx][ny] = true;
                queue.offer(new int[]{nx, ny, dist + 1});
            }
        }
    }

    List<List<Integer>> result = new ArrayList<>();
    while (!pq.isEmpty()) {
        int[] item = pq.poll();
        result.add(Arrays.asList(item[2], item[3]));
    }
    Collections.reverse(result);
    return result;
}#include <vector>
#include <queue>
#include <tuple>
using namespace std;
vector<vector<int>> kHighestRankedItems(vector<vector<int>>& grid, vector<int>& pricing, vector<int>& start, int k) {
int m = grid.size(), n = grid[0].size();
int low = pricing[0], high = pricing[1];
int startX = start[0], startY = start[1];
vector<pair<int, int>> directions = {{1, 0}, {-1, 0}, {0, 1}, {0, -1}};
auto cmp = [](const tuple<int, int, int, int>& a, const tuple<int, int, int, int>& b) {
return get<0>(a) > get<0>(b) || (get<0>(a) == get<0>(b) && get<1>(a) > get<1>(b)) ||
(get<0>(a) == get<0>(b) && get<1>(a) == get<1>(b) && get<2>(a) > get<2>(b)) ||
(get<0>(a) == get<0>(b) && get<1>(a) == get<1>(b) && get<2>(a) == get<2>(b) && get<3>(a) > get<3>(b));
};
priority_queue<tuple<int, int, int, int>, vector<tuple<int, int, int, int>>, decltype(cmp)> pq(cmp);
queue<tuple<int, int, int>> q;
vector<vector<bool>> visited(m, vector<bool>(n, false));
q.emplace(startX, startY, 0);
visited[startX][startY] = true;
while (!q.empty()) {
auto [x, y, dist] = q.front(); q.pop();
if (grid[x][y] <= high && grid[x][y] >= low) {
pq.emplace(dist, grid[x][y], x, y);
if (pq.size() > k) pq.pop();
}
for (auto &[dx, dy] : directions) {
int nx = x + dx, ny = y + dy;
if (nx >= 0 && nx < m && ny >= 0 && ny < n && !visited[nx][ny] && grid[nx][ny] != 0) {
visited[nx][ny] = true;
q.emplace(nx, ny, dist + 1);
}
}
}
vector<vector<int>> result;
while (!pq.empty()) {
auto [dist, price, x, y] = pq.top(); pq.pop();
result.push_back({x, y});
}
reverse(result.begin(), result.end());
return result;
}The Java implementation follows a similar strategy by leveraging Java's PriorityQueue for the top k selection, employing BFS for traversal. The priority queue here orders items based on the specified ranking criteria, and it is ensured that only the top k elements remain in the queue by evicting the lowest-priority items as needed. Finally, the selected items' coordinates are returned in the desired order.
Time Complexity: O(m * n *log(k)), gaining efficiency by only maintaining k high-priority items.
Space Complexity: O(k + m * n), for visited marking and priority queue.
Approach 3: BFS + Sorting
We can start from (row, col) and use breadth-first search to find all items with prices in the range [low, high]. Store the distance, price, row coordinate, and column coordinate of these items in the array pq.
Finally, sort pq by distance, price, row coordinate, and column coordinate, and return the coordinates of the first k items.
The time complexity is O(m times n times log (m times n)), and the space complexity is O(m times n). Here, m and n are the number of rows and columns of the 2D array grid, respectively.
function highestRankedKItems(
    grid: number[][],
    pricing: number[],
    start: number[],
    k: number,
): number[][] {
    const [m, n] = [grid.length, grid[0].length];
    const [row, col] = start;
    const [low, high] = pricing;
    let q: [number, number][] = [[row, col]];
    const pq: [number, number, number, number][] = [];
    if (low <= grid[row][col] && grid[row][col] <= high) {
        pq.push([0, grid[row][col], row, col]);
    }
    grid[row][col] = 0;
    const dirs = [-1, 0, 1, 0, -1];
    for (let step = 1; q.length > 0; ++step) {
        const nq: [number, number][] = [];
        for (const [x, y] of q) {
            for (let j = 0; j < 4; j++) {
                const nx = x + dirs[j];
                const ny = y + dirs[j + 1];
                if (nx >= 0 && nx < m && ny >= 0 && ny < n && grid[nx][ny] > 0) {
                    if (low <= grid[nx][ny] && grid[nx][ny] <= high) {
                        pq.push([step, grid[nx][ny], nx, ny]);
                    }
                    grid[nx][ny] = 0;
                    nq.push([nx, ny]);
                }
            }
        }
        q = nq;
    }
    pq.sort((a, b) => {
        if (a[0] !== b[0]) return a[0] - b[0];
        if (a[1] !== b[1]) return a[1] - b[1];
        if (a[2] !== b[2]) return a[2] - b[2];
        return a[3] - b[3];
    });
    const ans: number[][] = [];
    for (let i = 0; i < Math.min(k, pq.length); i++) {
        ans.push([pq[i][2], pq[i][3]]);
    }
    return ans;
}func highestRankedKItems(grid [][]int, pricing []int, start []int, k int) (ans [][]int) {
m, n := len(grid), len(grid[0])
row, col := start[0], start[1]
low, high := pricing[0], pricing[1]
q := [][2]int{{row, col}}
pq := [][]int{}
if low <= grid[row][col] && grid[row][col] <= high {
pq = append(pq, []int{0, grid[row][col], row, col})
}
grid[row][col] = 0
dirs := [5]int{-1, 0, 1, 0, -1}
for step := 1; len(q) > 0; step++ {
for sz := len(q); sz > 0; sz-- {
x, y := q[0][0], q[0][1]
q = q[1:]
for j := 0; j < 4; j++ {
nx, ny := x+dirs[j], y+dirs[j+1]
if nx >= 0 && nx < m && ny >= 0 && ny < n && grid[nx][ny] > 0 {
if low <= grid[nx][ny] && grid[nx][ny] <= high {
pq = append(pq, []int{step, grid[nx][ny], nx, ny})
}
grid[nx][ny] = 0
q = append(q, [2]int{nx, ny})
}
}
}
}
sort.Slice(pq, func(i, j int) bool {
a, b := pq[i], pq[j]
if a[0] != b[0] {
return a[0] < b[0]
}
if a[1] != b[1] {
return a[1] < b[1]
}
if a[2] != b[2] {
return a[2] < b[2]
}
return a[3] < b[3]
})
for i := 0; i < len(pq) && i < k; i++ {
ans = append(ans, pq[i][2:])
}
return
}Complexity comparison
| Approach | Complexity |
|---|---|
| Breadth-First Search (BFS) with Sorting | Time Complexity: O(m * n * log(m * n)), as we potentially explore each cell and sort up to m * n items. |
| Breadth-First Search with Priority Queue | Time Complexity: O(m * n *log(k)), gaining efficiency by only maintaining k high-priority items. |
| BFS + Sorting | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| BFS with Sorting | O(mn log(mn)) | O(mn) | Simple implementation when the number of valid items is small or clarity is preferred |
| BFS with Priority Queue | O(mn log k) | O(mn) | Better when the grid is large but only the top k ranked items are required |
Frequently asked questions
Is K Highest Ranked Items Within a Price Range easy or hard?
The problem is rated Medium on LeetCode. The BFS traversal is straightforward, but the challenge comes from implementing the multi-level ranking rules correctly and optimizing the selection of the top k items.
How to solve K Highest Ranked Items Within a Price Range in optimal time?
Run BFS from the starting position to explore cells in distance order. For each cell whose price falls within the range, push it into a priority queue ordered by distance, price, row, and column. Keep the heap size at most k. This yields an overall complexity of O(mn log k).
What is the best approach for K Highest Ranked Items Within a Price Range?
Breadth-First Search combined with ranking logic is the most effective approach. BFS guarantees that cells are explored in increasing distance from the start. You then rank valid items by distance, price, row, and column using either sorting or a priority queue. The heap-based approach reduces sorting overhead when k is small.
What data structure is used in K Highest Ranked Items Within a Price Range?
The core data structure is a queue for Breadth-First Search to explore the grid level by level. A sorting structure or a heap (priority queue) is used to rank items by distance, price, and coordinates according to the problem rules.
What is the time complexity of K Highest Ranked Items Within a Price Range?
The BFS traversal itself takes O(mn) because every grid cell may be visited once. If you collect all candidates and sort them, the total complexity becomes O(mn log(mn)). Using a priority queue limited to k elements improves the ranking cost to O(mn log k).
K Highest Ranked Items Within a Price Range Python or Java solution approach
Python solutions typically run BFS with a deque and store candidates for sorting or use heapq for ranking. Java and C++ implementations often use a PriorityQueue with a custom comparator to maintain the best k items while traversing the grid.
Is K Highest Ranked Items Within a Price Range asked at Google, Amazon, or Meta?
Grid traversal and ranking problems like this frequently appear in interviews at companies such as Amazon, Google, and Meta. The problem tests BFS fundamentals, matrix traversal, and custom sorting or heap usage for multi-criteria ranking.