
Count Submatrices With Equal Frequency of X and Y - Solution & Explanation
Problem Statement
Given a 2D character matrix grid, where grid[i][j] is either 'X', 'Y', or '.', return the number of submatrices that contain:
grid[0][0]- an equal frequency of
'X'and'Y'. - at least one
'X'.
Example 1:
Input: grid = [["X","Y","."],["Y",".","."]]
Output: 3
Explanation:
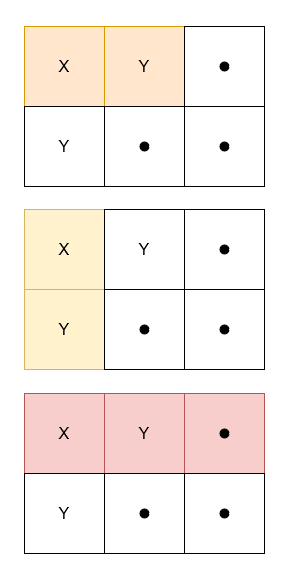
Example 2:
Input: grid = [["X","X"],["X","Y"]]
Output: 0
Explanation:
No submatrix has an equal frequency of 'X' and 'Y'.
Example 3:
Input: grid = [[".","."],[".","."]]
Output: 0
Explanation:
No submatrix has at least one 'X'.
Constraints:
1 <= grid.length, grid[i].length <= 1000grid[i][j]is either'X','Y', or'.'.
Approach Overview
Problem Overview: Given a matrix containing characters including X and Y, count how many submatrices contain the same number of X and Y. A valid submatrix has balanced frequency of both characters. The challenge is efficiently checking many possible rectangular regions.
Approach 1: Prefix Sum and Hash Map (O(m^2 * n) time, O(n) space)
This approach converts the matrix into a numeric grid where X = +1, Y = -1, and other cells contribute 0. A submatrix with equal counts of X and Y then becomes a region with total sum 0. Fix two row boundaries and compress the rows into a 1D array of column sums. The task reduces to counting subarrays with sum zero, which can be done using a hash map storing prefix sum frequencies. Each column update checks if the current prefix sum has appeared before; if so, all earlier occurrences form balanced submatrices. This technique leverages prefix sum and hashing to avoid scanning every rectangle explicitly.
Approach 2: Dynamic Programming with Accumulated Count (O(m^2 * n) time, O(m * n) space)
This method builds prefix counts for X and Y across the matrix using dynamic programming. For every pair of row boundaries, accumulate column counts of X and Y between those rows. Instead of recomputing frequencies from scratch, reuse the accumulated counts and track the difference (countX - countY) across columns. When the difference repeats, the columns between them form a balanced region. The DP prefix structure speeds up region queries and reduces repeated scanning of cells. This approach works well when you already maintain 2D prefix structures for a matrix problem.
Recommended for interviews: The prefix sum + hash map approach is the standard solution. It converts a 2D problem into repeated 1D subarray checks and demonstrates strong understanding of array prefix techniques. Interviewers usually expect this optimization because brute force enumeration of all rectangles quickly becomes too slow.
Approach 1: Prefix Sum and Hash Map
This approach uses a prefix sum array and a hash map to maintain the difference between the numbers of 'X' and 'Y' found so far. This setup enables the identification of subarrays where the count of 'X' and 'Y' is equal.
For each row start and row end combination, collapse the 2D array into a 1D frequency difference array, and search for differences that occur at least once in different locations, which will correspond to equal X and Y submatrices.
The solution iterates through each possible pair of starting and ending rows. For each column, it calculates the difference between the number of 'X's and 'Y's and updates a hash map to find matches with previous occurrences of the same difference. This identifies submatrices satisfying the problem's condition.
Complexity
Time Complexity: O(n^2 * m), where n is the number of rows and m is the number of columns.
Space Complexity: O(m), for the hash map storing differences.
Approach 2: Dynamic Programming with Accumulated Count
This approach uses dynamic programming by maintaining an accumulated count array. The goal is to keep a cumulative total of 'X's and 'Y's up to each point in the grid, allowing quick calculation of any submatrix's contents via differences.
This C++ code uses two 2D arrays to maintain cumulative counts of 'X' and 'Y' appearance. For each valid starting and ending row, it calculates the count differences column-wise and integrates these differences with hash maps to derive submatrices with equal numbers of 'X' and 'Y'.
Code
C++
JavaScript
Complexity
Time Complexity: O(n * m^2), where n is the number of rows and m is the number of columns.
Space Complexity: O(n * m), for storing cumulative counts.
Approach 3: 2D Prefix Sum
According to the problem description, we only need to calculate the prefix sums s[i][j][0] and s[i][j][1] for each position (i, j), which represent the number of characters X and Y in the submatrix from (0, 0) to (i, j), respectively. If s[i][j][0] > 0 and s[i][j][0] = s[i][j][1], it means the condition is met, and we increment the answer by one.
After traversing all positions, return the answer.
The time complexity is O(m times n), and the space complexity is O(m times n). Here, m and n represent the number of rows and columns of the matrix, respectively.
Complexity Comparison
| Approach | Complexity |
|---|---|
| Prefix Sum and Hash Map | Time Complexity: O(n^2 * m), where n is the number of rows and m is the number of columns. |
| Dynamic Programming with Accumulated Count | Time Complexity: O(n * m^2), where n is the number of rows and m is the number of columns. |
| 2D Prefix Sum | — |
Detailed Complexity Analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Prefix Sum + Hash Map | O(m^2 * n) | O(n) | General case; best balance of speed and simplicity |
| Dynamic Programming with Accumulated Count | O(m^2 * n) | O(m * n) | Useful when prefix counts of characters are already maintained for multiple queries |
Video Solution
Count Submatrices With Equal Frequency of X and Y | Using Same Pattern Concept | Leetcode 3212 | MIK • codestorywithMIK • 6,726 views views
Watch 9 more video solutions →Frequently Asked Questions
Is Count Submatrices With Equal Frequency of X and Y easy or hard?
Count Submatrices With Equal Frequency of X and Y Python/Java solution
How to solve Count Submatrices With Equal Frequency of X and Y in O(n)?
What is the best approach for Count Submatrices With Equal Frequency of X and Y?
Is Count Submatrices With Equal Frequency of X and Y asked at Google/Amazon/Meta?
What data structure is used in Count Submatrices With Equal Frequency of X and Y?
What is the time complexity of Count Submatrices With Equal Frequency of X and Y?
Ready to solve this problem?
Practice Count Submatrices With Equal Frequency of X and Y with our built-in code editor and test cases.
Practice on FleetCodeTable of Contents
Practice this problem
Open in Editor