
Count Nodes Equal to Average of Subtree - Solution & Explanation
Problem Statement
Given the root of a binary tree, return the number of nodes where the value of the node is equal to the average of the values in its subtree.
Note:
- The average of
nelements is the sum of thenelements divided bynand rounded down to the nearest integer. - A subtree of
rootis a tree consisting ofrootand all of its descendants.
Example 1:
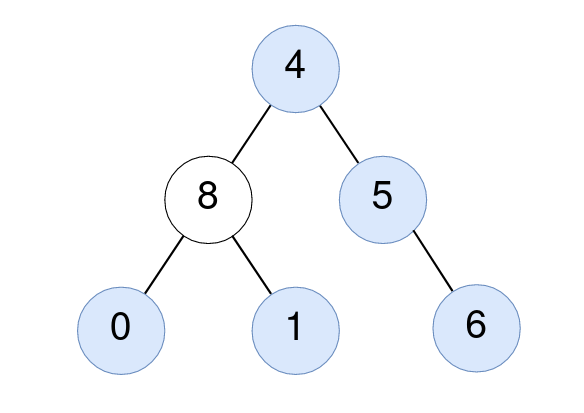
Input: root = [4,8,5,0,1,null,6]
Output: 5
Explanation:
For the node with value 4: The average of its subtree is (4 + 8 + 5 + 0 + 1 + 6) / 6 = 24 / 6 = 4.
For the node with value 5: The average of its subtree is (5 + 6) / 2 = 11 / 2 = 5.
For the node with value 0: The average of its subtree is 0 / 1 = 0.
For the node with value 1: The average of its subtree is 1 / 1 = 1.
For the node with value 6: The average of its subtree is 6 / 1 = 6.
Example 2:
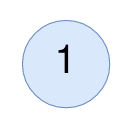
Input: root = [1]
Output: 1
Explanation: For the node with value 1: The average of its subtree is 1 / 1 = 1.
Constraints:
- The number of nodes in the tree is in the range
[1, 1000]. 0 <= Node.val <= 1000
Approach Overview
Problem Overview: You are given the root of a binary tree. For every node, compute the average value of all nodes in its subtree (including itself). Count how many nodes have a value equal to the integer average of their subtree.
Approach 1: Recursion with Post-Order Traversal (O(n) time, O(h) space)
This approach uses a post-order Depth-First Search to process children before their parent. Each recursive call returns two values: the sum of the subtree and the number of nodes in that subtree. With these values, you compute average = sum // count and compare it with the current node's value. Because each node is visited exactly once and aggregation happens while returning from recursion, the algorithm runs in O(n) time with O(h) space for the recursion stack, where h is the tree height. This pattern is common in tree problems where subtree metrics must be combined bottom-up.
Approach 2: Iterative DFS Using Stack (O(n) time, O(n) space)
An iterative solution simulates the same post-order traversal using an explicit stack instead of recursion. Each stack frame stores the node and a state flag indicating whether its children have already been processed. A hash map (or dictionary) stores computed (sum, count) pairs for each node so the parent can aggregate them later. Once both children are processed, compute the subtree sum and node count, then check whether the node value equals sum // count. This method avoids recursion depth limits but uses O(n) auxiliary space for the stack and cached results.
Recommended for interviews: The recursive post-order traversal is the expected solution. Interviewers want to see that you recognize subtree computations require bottom-up aggregation, a common binary tree pattern. The iterative stack version demonstrates deeper understanding of DFS mechanics but is usually unnecessary unless recursion limits are a concern.
Approach 1: Recursion with Post-Order Traversal
This approach involves using a post-order traversal (left, right, root) to compute the sum and count of nodes for each subtree. At each node, the sum of values and the total count of the subtree nodes are determined. The average is calculated by dividing the sum by the count and compared with the node's value. If they are equal, a counter is incremented.
This Python solution defines a recursive DFS function `dfs` that traverses the tree in a post-order manner. For each node, it computes the sum and count of the subtree rooted at that node. If the node value equals the average (sum // count) of its subtree, the counter `self.count` is incremented.
Code
Python
JavaScript
Complexity
Time Complexity: O(n), where n is the number of nodes in the tree, as each node is visited once.
Space Complexity: O(h), where h is the height of the tree, which accounts for the recursion stack.
Approach 2: Iterative Using Stack
This approach involves using an iterative method with an explicit stack to perform a post-order traversal. Similar to the recursive method, it calculates the sum and count of the subtree nodes for each node using an additional data structure to simulate recursion.
The C# solution utilizes an explicit stack to perform a post-order traversal. It uses a dictionary to store the sum and count for each node. The node is processed twice: first to traverse its children and then to calculate its subtree's sum and count.
Complexity
Time Complexity: O(n), since each node is processed twice.
Space Complexity: O(n), for the stack and the dictionary storing sums and counts for each node.
Approach 3: DFS
We design a function dfs, which calculates the sum and the number of nodes of the subtree rooted at the current node.
The execution process of the function dfs is as follows:
- If the current node is null, return
(0, 0). - Otherwise, we recursively calculate the sum and the number of nodes of the left and right subtrees, denoted as
(ls, ln)and(rs, rn), respectively. Then, the sumsand the number of nodesnof the subtree rooted at the current node arels + rs + root.valandln + rn + 1, respectively. Ifs / n = root.val, it means the current node meets the requirement of the problem, and we increment the answeransby1. - Finally, the function
dfsreturnssandn.
We initialize the answer ans to 0, then call the dfs function, and finally return the answer ans.
The time complexity is O(n), and the space complexity is O(n). Here, n represents the number of nodes in the binary tree.
Code
Python
Java
C++
Go
TypeScript
Complexity Comparison
| Approach | Complexity |
|---|---|
| Recursion with Post-Order Traversal | Time Complexity: O(n), where n is the number of nodes in the tree, as each node is visited once. |
| Iterative Using Stack | Time Complexity: O(n), since each node is processed twice. |
| DFS | — |
Detailed Complexity Analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Recursion with Post-Order Traversal | O(n) | O(h) | Best general solution. Clean bottom-up aggregation of subtree sum and count. |
| Iterative DFS Using Stack | O(n) | O(n) | When recursion depth may overflow or when implementing DFS iteratively. |
Video Solution
Count Nodes Equal to Average of Subtree | 2 Approaches | Leetcode-2265 | Explanation ➕ Live Coding • codestorywithMIK • 7,344 views views
Watch 9 more video solutions →Frequently Asked Questions
Is Count Nodes Equal to Average of Subtree easy or hard?
Count Nodes Equal to Average of Subtree Python/Java solution
How to solve Count Nodes Equal to Average of Subtree in O(n)?
What is the best approach for Count Nodes Equal to Average of Subtree?
Is Count Nodes Equal to Average of Subtree asked at Google/Amazon/Meta?
What data structure is used in Count Nodes Equal to Average of Subtree?
What is the time complexity of Count Nodes Equal to Average of Subtree?
Ready to solve this problem?
Practice Count Nodes Equal to Average of Subtree with our built-in code editor and test cases.
Practice on FleetCode