Path Existence Queries in a Graph II solution and explanation
 Google

9 more videos on this problem
 Path Existence Queries in a Graph II | Leetcode 3534 | Binary Lifting | Concepts & Questions - 5codestorywithMIK · 1:10:56 · 8K views
 Path Existence Queries in a Graph II | Leetcode - 3534Shivam Gupta · 28:25 · 2K views
 Path Existence Queries in a Graph II - Leetcode 3534 | Java | HindiKernel Queen 👑 · 25:28 · 1K views
 Path Existence Queries in a Graph II | LeetCode 3534 - Pythonimpoldev · 16:18 · 1K views
 3534. Path Existence Queries in a Graph II | Leetcode Daily - PythonLeetcode Daily · 3:51 · 812 views
 3534. Path Existence Queries in a Graph II (Leetcode Hard)Programming Live with Larry · 2:21:36 · 566 views
 Daily Leetcode #2292: Jul 10, 2026 - 3534. Path Existence Queries in a Graph IIProgramming Live with Larry · 40:08 · 532 views
 Path Existence Queries in a Graph II | LeetCode 3534 | Binary Lifting | Java | Developer CoderDeveloper Coder · 52:19 · 254 views
 LeetCode 3534 | Path Existence Queries in a Graph II 🔥 Hard Explained with Binary Lifting | #JavaExplainedbychhavi · 10:15 · 253 views
 LeetCode 3534 Path Existence Queries in a Graph IIManjeet Dhayal · 30:58 · 66 views
The problem
You are given an integer n representing the number of nodes in a graph, labeled from 0 to n - 1.
You are also given an integer array nums of length n and an integer maxDiff.
An undirected edge exists between nodes i and j if the absolute difference between nums[i] and nums[j] is at most maxDiff (i.e., |nums[i] - nums[j]| <= maxDiff).
You are also given a 2D integer array queries. For each queries[i] = [ui, vi], find the minimum distance between nodes ui and vi. If no path exists between the two nodes, return -1 for that query.
Return an array answer, where answer[i] is the result of the ith query.
Note: The edges between the nodes are unweighted.
Example 1:
Input: n = 5, nums = [1,8,3,4,2], maxDiff = 3, queries = [[0,3],[2,4]]
Output: [1,1]
Explanation:
The resulting graph is:
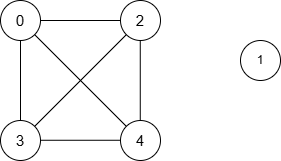
| Query | Shortest Path | Minimum Distance |
|---|---|---|
| [0, 3] | 0 → 3 | 1 |
| [2, 4] | 2 → 4 | 1 |
Thus, the output is [1, 1].
Example 2:
Input: n = 5, nums = [5,3,1,9,10], maxDiff = 2, queries = [[0,1],[0,2],[2,3],[4,3]]
Output: [1,2,-1,1]
Explanation:
The resulting graph is:
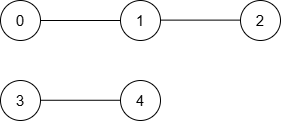
| Query | Shortest Path | Minimum Distance |
|---|---|---|
| [0, 1] | 0 → 1 | 1 |
| [0, 2] | 0 → 1 → 2 | 2 |
| [2, 3] | None | -1 |
| [4, 3] | 3 → 4 | 1 |
Thus, the output is [1, 2, -1, 1].
Example 3:
Input: n = 3, nums = [3,6,1], maxDiff = 1, queries = [[0,0],[0,1],[1,2]]
Output: [0,-1,-1]
Explanation:
There are no edges between any two nodes because:
- Nodes 0 and 1:
|nums[0] - nums[1]| = |3 - 6| = 3 > 1 - Nodes 0 and 2:
|nums[0] - nums[2]| = |3 - 1| = 2 > 1 - Nodes 1 and 2:
|nums[1] - nums[2]| = |6 - 1| = 5 > 1
Thus, no node can reach any other node, and the output is [0, -1, -1].
Constraints:
1 <= n == nums.length <= 1050 <= nums[i] <= 1050 <= maxDiff <= 1051 <= queries.length <= 105queries[i] == [ui, vi]0 <= ui, vi < n
Approach overview
Problem Overview: You are given a graph and multiple queries asking whether a valid path exists between two nodes under specific constraints (typically edge limits or conditions). Instead of recomputing connectivity for every query independently, the challenge is to process queries efficiently while the graph structure stays fixed.
Approach 1: BFS/DFS Per Query (Brute Force) (Time: O(Q * (V + E)), Space: O(V))
The most direct method is to treat every query independently. For each query, run a BFS or DFS starting from the source node and check if the destination node can be reached while respecting the constraint. During traversal, ignore edges that violate the query condition. This approach is simple and easy to implement using adjacency lists. However, it quickly becomes inefficient when the number of queries is large because the entire graph may be traversed for each query.
Approach 2: Offline Queries with Sorting + Union-Find (Optimal) (Time: O((E + Q) log E), Space: O(V))
A more scalable approach processes queries offline. First, sort all edges based on the constraint parameter (commonly weight or limit). Sort queries by the same constraint value. As you iterate through queries in increasing order, incrementally add valid edges to a Union-Find structure. Each union operation connects components whose edges satisfy the current query constraint. When processing a query, simply check whether the two nodes belong to the same connected component using find(). This transforms repeated graph traversals into near-constant time connectivity checks.
The key insight: connectivity only changes when new edges become eligible. By sorting both edges and queries, you add edges exactly once and reuse the resulting components for later queries. Union-Find with path compression and union by rank keeps operations extremely fast in practice.
Approach 3: Binary Search + Connectivity Checks (Time: O(Q log E * α(V)), Space: O(V))
Another variation applies binary search on the sorted edge list to determine the maximum prefix of edges that satisfy each query. For every candidate prefix, use a Union-Find structure to test connectivity. While this method demonstrates how monotonic constraints enable binary search, it tends to rebuild connectivity structures multiple times, making it slower than the fully offline approach.
These techniques rely heavily on efficient graph representations and the sorting of edges and queries. The Union-Find data structure is the central optimization because it answers connectivity queries in almost constant time.
Recommended for interviews: The offline sorting + Union-Find approach is what most interviewers expect for hard connectivity query problems. Showing the brute-force BFS/DFS solution first demonstrates understanding of the graph traversal baseline. Transitioning to Union-Find with sorted edges proves you can optimize repeated connectivity queries and reason about algorithmic scaling.
Solution
Key observation: an edge exists between two nodes if the absolute difference of their values is at most maxDiff. After sorting nodes by value, greedily jumping from a smaller-value node to the largest reachable value at each step yields the shortest path.
The preprocessing steps are as follows:
- Sort
(nums[i], i)pairs by value; - Use two pointers: for each sorted position
l, find the rightmost positionrsuch thatpairs[r].first - pairs[l].first <= maxDiff. Setf[i][0] = j, meaning from nodei, one jump reaches nodej, the largest-value node withinmaxDiff; - Build a binary lifting table
f[i][k], representing the node reached after2^kjumps from nodei.
For each query, assume nums[u] <= nums[v]:
- If
u == v, the answer is0; - If
nums[u] == nums[v], the answer is1; - Otherwise, use binary lifting to find the minimum number of jumps so that the reached node's value is at least
nums[v]; if unreachable, return-1, otherwise the answer isd + 1.
The time complexity is O(n log n + (n + q) log n) and the space complexity is O(n log n), where n is the number of nodes and q is the number of queries.
class Solution:
    def pathExistenceQueries(
        self, n: int, nums: List[int], maxDiff: int, queries: List[List[int]]
    ) -> List[int]:
        pairs = sorted((x, i) for i, x in enumerate(nums))
        m = 20
        f = [[0] * m for _ in range(n)]
        r = n - 1
        for l in range(n - 1, -1, -1):
            while pairs[r][0] - pairs[l][0] > maxDiff:
                r -= 1
            i, j = pairs[l][1], pairs[r][1]
            f[i][0] = j
            for k in range(1, m):
                f[i][k] = f[f[i][k - 1]][k - 1]

        ans = []
        for i, j in queries:
            if nums[i] > nums[j]:
                i, j = j, i
            if i == j:
                ans.append(0)
                continue
            if nums[i] == nums[j]:
                ans.append(1)
                continue
            d = 0
            for k in range(m - 1, -1, -1):
                if nums[f[i][k]] < nums[j]:
                    d |= 1 << k
                    i = f[i][k]
            if nums[f[i][0]] < nums[j]:
                ans.append(-1)
            else:
                ans.append(d + 1)
return ansclass Solution {
public int[] pathExistenceQueries(int n, int[] nums, int maxDiff, int[][] queries) {
int[][] pairs = new int[n][2];
for (int i = 0; i < n; i++) {
pairs[i][0] = nums[i];
pairs[i][1] = i;
}
Arrays.sort(pairs, (a, b) -> a[0] - b[0]);
int m = 20;
int[][] f = new int[n][m];
int r = n - 1;
for (int l = n - 1; l >= 0; l--) {
while (pairs[r][0] - pairs[l][0] > maxDiff) {
r--;
}
int i = pairs[l][1], j = pairs[r][1];
f[i][0] = j;
for (int k = 1; k < m; k++) {
f[i][k] = f[f[i][k - 1]][k - 1];
}
}
int[] ans = new int[queries.length];
for (int t = 0; t < queries.length; t++) {
int i = queries[t][0], j = queries[t][1];
if (nums[i] > nums[j]) {
int tmp = i;
i = j;
j = tmp;
}
if (i == j) {
ans[t] = 0;
continue;
}
if (nums[i] == nums[j]) {
ans[t] = 1;
continue;
}
int d = 0;
for (int k = m - 1; k >= 0; k--) {
if (nums[f[i][k]] < nums[j]) {
d |= 1 << k;
i = f[i][k];
}
}
if (nums[f[i][0]] < nums[j]) {
ans[t] = -1;
} else {
ans[t] = d + 1;
}
}
return ans;
}
}class Solution {
public:
vector<int> pathExistenceQueries(int n, vector<int>& nums, int maxDiff, vector<vector<int>>& queries) {
vector<pair<int, int>> pairs;
for (int i = 0; i < n; i++) {
pairs.emplace_back(nums[i], i);
}
sort(pairs.begin(), pairs.end());
int m = 20;
vector<vector<int>> f(n, vector<int>(m));
int r = n - 1;
for (int l = n - 1; l >= 0; l--) {
while (pairs[r].first - pairs[l].first > maxDiff) {
r--;
}
int i = pairs[l].second, j = pairs[r].second;
f[i][0] = j;
for (int k = 1; k < m; k++) {
f[i][k] = f[f[i][k - 1]][k - 1];
}
}
vector<int> ans;
for (auto& q : queries) {
int i = q[0], j = q[1];
if (nums[i] > nums[j]) {
swap(i, j);
}
if (i == j) {
ans.push_back(0);
continue;
}
if (nums[i] == nums[j]) {
ans.push_back(1);
continue;
}
int d = 0;
for (int k = m - 1; k >= 0; k--) {
if (nums[f[i][k]] < nums[j]) {
d |= 1 << k;
i = f[i][k];
}
}
if (nums[f[i][0]] < nums[j]) {
ans.push_back(-1);
} else {
ans.push_back(d + 1);
}
}
return ans;
}
};function pathExistenceQueries(
n: number,
nums: number[],
maxDiff: number,
queries: number[][],
): number[] {
const pairs: number[][] = [];
for (let i = 0; i < n; i++) {
pairs.push([nums[i], i]);
}
pairs.sort((a, b) => a[0] - b[0]);
const m = 20;
const f = Array.from({ length: n }, () => Array(m).fill(0));
let r = n - 1;
for (let l = n - 1; l >= 0; l--) {
while (pairs[r][0] - pairs[l][0] > maxDiff) {
r--;
}
let i = pairs[l][1],
j = pairs[r][1];
f[i][0] = j;
for (let k = 1; k < m; k++) {
f[i][k] = f[f[i][k - 1]][k - 1];
}
}
const ans: number[] = [];
for (const q of queries) {
let i = q[0],
j = q[1];
if (nums[i] > nums[j]) {
[i, j] = [j, i];
}
if (i === j) {
ans.push(0);
continue;
}
if (nums[i] === nums[j]) {
ans.push(1);
continue;
}
let d = 0;
for (let k = m - 1; k >= 0; k--) {
if (nums[f[i][k]] < nums[j]) {
d |= 1 << k;
i = f[i][k];
}
}
if (nums[f[i][0]] < nums[j]) {
ans.push(-1);
} else {
ans.push(d + 1);
}
}
return ans;
}func pathExistenceQueries(n int, nums []int, maxDiff int, queries [][]int) []int {
pairs := make([][2]int, n)
for i, x := range nums {
pairs[i] = [2]int{x, i}
}
sort.Slice(pairs, func(i, j int) bool {
return pairs[i][0] < pairs[j][0]
})
m := 20
f := make([][]int, n)
for i := range f {
f[i] = make([]int, m)
}
r := n - 1
for l := n - 1; l >= 0; l-- {
for pairs[r][0]-pairs[l][0] > maxDiff {
r--
}
i, j := pairs[l][1], pairs[r][1]
f[i][0] = j
for k := 1; k < m; k++ {
f[i][k] = f[f[i][k-1]][k-1]
}
}
ans := make([]int, 0, len(queries))
for _, q := range queries {
i, j := q[0], q[1]
if nums[i] > nums[j] {
i, j = j, i
}
if i == j {
ans = append(ans, 0)
continue
}
if nums[i] == nums[j] {
ans = append(ans, 1)
continue
}
d := 0
for k := m - 1; k >= 0; k-- {
if nums[f[i][k]] < nums[j] {
d |= 1 << k
i = f[i][k]
}
}
if nums[f[i][0]] < nums[j] {
ans = append(ans, -1)
} else {
ans = append(ans, d+1)
}
}
return ans
}impl Solution {
pub fn path_existence_queries(
n: i32,
nums: Vec<i32>,
max_diff: i32,
queries: Vec<Vec<i32>>,
) -> Vec<i32> {
let n = n as usize;
let mut pairs = Vec::with_capacity(n);
for (i, &x) in nums.iter().enumerate() {
pairs.push((x, i));
}
pairs.sort_unstable();
let m = 20;
let mut f = vec![vec![0; m]; n];
let mut r = n - 1;
for l in (0..n).rev() {
while pairs[r].0 - pairs[l].0 > max_diff {
r -= 1;
}
let (i, j) = (pairs[l].1, pairs[r].1);
f[i][0] = j;
for k in 1..m {
f[i][k] = f[f[i][k - 1]][k - 1];
}
}
let mut ans = Vec::with_capacity(queries.len());
for q in queries {
let (mut i, mut j) = (q[0] as usize, q[1] as usize);
if nums[i] > nums[j] {
std::mem::swap(&mut i, &mut j);
}
if i == j {
ans.push(0);
continue;
}
if nums[i] == nums[j] {
ans.push(1);
continue;
}
let mut d = 0;
for k in (0..m).rev() {
if nums[f[i][k]] < nums[j] {
d |= 1 << k;
i = f[i][k];
}
}
if nums[f[i][0]] < nums[j] {
ans.push(-1);
} else {
ans.push(d + 1);
}
}
ans
}
}Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| BFS/DFS per Query | O(Q * (V + E)) | O(V) | Small graphs or very few queries where repeated traversal cost is acceptable |
| Offline Sorting + Union-Find | O((E + Q) log E) | O(V) | Best general solution when many connectivity queries must be processed efficiently |
| Binary Search + DSU Rebuild | O(Q log E * α(V)) | O(V) | Useful when query constraints are monotonic and binary search logic is easier to reason about |
Frequently asked questions
Is Path Existence Queries in a Graph II easy or hard?
This problem is considered hard because it combines graph connectivity, offline query processing, sorting, and Union-Find optimizations. The main challenge is recognizing that repeated path searches can be replaced with incremental connectivity tracking.
Path Existence Queries in a Graph II Python/Java solution
Typical implementations use Union-Find with path compression. Python, Java, C++, and Go solutions all follow the same pattern: sort edges and queries, union eligible edges while iterating, and answer each query using DSU find operations.
What is the best approach for Path Existence Queries in a Graph II?
The most efficient approach is processing queries offline using sorting and a Union-Find (Disjoint Set Union) structure. Sort edges by constraint (such as weight) and sort queries by the same parameter. Incrementally union valid edges and answer each query with a connectivity check. This avoids repeated graph traversals and keeps each query near constant time.
How to solve Path Existence Queries in a Graph II in O((E+Q) log E)?
Sort edges by the constraint value and sort queries by their allowed limit. Iterate through queries while progressively adding edges that satisfy the limit into a Union-Find structure. For each query, check whether the two nodes belong to the same connected component. This eliminates repeated BFS or DFS traversals.
Is Path Existence Queries in a Graph II asked at Google/Amazon/Meta?
Connectivity query problems using Union-Find and offline sorting frequently appear in interviews at large tech companies such as Google, Amazon, and Meta. Variations often involve edge weight limits, dynamic connectivity, or constraint-based path validation.
What data structure is used in Path Existence Queries in a Graph II?
The core data structure is Union-Find (Disjoint Set Union). It efficiently maintains connected components while edges are added. The solution also relies on sorted arrays for edges and queries, along with adjacency or edge lists for the graph representation.
What is the time complexity of Path Existence Queries in a Graph II?
The optimal Union-Find based solution runs in O((E + Q) log E) time due to sorting edges and queries. Each union and find operation is nearly O(1) with path compression and union by rank. Space complexity is O(V) for the DSU structure and adjacency representation.