Path Existence Queries in a Graph I solution and explanation
 Google

9 more videos on this problem
 Path Existence Queries in a Graph I | Multiple Approaches | Simplified | Leetcode 3532 | MIKcodestorywithMIK · 27:16 · 6K views
 3532. Path Existence Queries in a Graph I | Leetcode Daily - PythonLeetcode Daily · 5:18 · 790 views
 3532. Path Existence Queries in a Graph ITech Courses · 9:32 · 471 views
 LeetCode 3532. Path Existence Queries in a Graph I | Union-Find | Easy | GraphLeet's Code · 17:52 · 449 views
 Daily Leetcode #2291: Jul 09, 2026 - 3532. Path Existence Queries in a Graph IProgramming Live with Larry · 11:55 · 332 views
 3532. Path Existence Queries in a Graph I (Leetcode Medium)Programming Live with Larry · 7:28 · 209 views
 Path Existence Queries in a Graph I | LeetCode 3532 | DSU | Java Code | Developer CoderDeveloper Coder · 17:33 · 209 views
 LeetCode 3532: Path Existence Queries in a Graph I | Java SolutionExpertFunda · 11:05 · 187 views
 Path Existence Queries in a Graph I | LeetCode 3532 - Pythonimpoldev · 8:12 · 160 views
 LeetCode 3532 | Path Existence Queries in a Graph I | Easy Java solution🚀 #leetcode #dsa #faangExplainedbychhavi · 7:30 · 149 views
The problem
You are given an integer n representing the number of nodes in a graph, labeled from 0 to n - 1.
You are also given an integer array nums of length n sorted in non-decreasing order, and an integer maxDiff.
An undirected edge exists between nodes i and j if the absolute difference between nums[i] and nums[j] is at most maxDiff (i.e., |nums[i] - nums[j]| <= maxDiff).
You are also given a 2D integer array queries. For each queries[i] = [ui, vi], determine whether there exists a path between nodes ui and vi.
Return a boolean array answer, where answer[i] is true if there exists a path between ui and vi in the ith query and false otherwise.
Example 1:
Input: n = 2, nums = [1,3], maxDiff = 1, queries = [[0,0],[0,1]]
Output: [true,false]
Explanation:
- Query
[0,0]: Node 0 has a trivial path to itself. - Query
[0,1]: There is no edge between Node 0 and Node 1 because|nums[0] - nums[1]| = |1 - 3| = 2, which is greater thanmaxDiff. - Thus, the final answer after processing all the queries is
[true, false].
Example 2:
Input: n = 4, nums = [2,5,6,8], maxDiff = 2, queries = [[0,1],[0,2],[1,3],[2,3]]
Output: [false,false,true,true]
Explanation:
The resulting graph is:
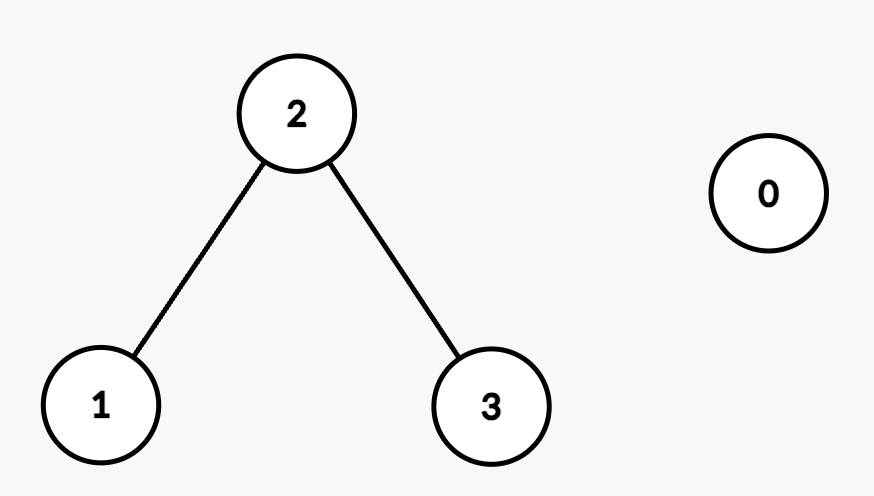
- Query
[0,1]: There is no edge between Node 0 and Node 1 because|nums[0] - nums[1]| = |2 - 5| = 3, which is greater thanmaxDiff. - Query
[0,2]: There is no edge between Node 0 and Node 2 because|nums[0] - nums[2]| = |2 - 6| = 4, which is greater thanmaxDiff. - Query
[1,3]: There is a path between Node 1 and Node 3 through Node 2 since|nums[1] - nums[2]| = |5 - 6| = 1and|nums[2] - nums[3]| = |6 - 8| = 2, both of which are withinmaxDiff. - Query
[2,3]: There is an edge between Node 2 and Node 3 because|nums[2] - nums[3]| = |6 - 8| = 2, which is equal tomaxDiff. - Thus, the final answer after processing all the queries is
[false, false, true, true].
Constraints:
1 <= n == nums.length <= 1050 <= nums[i] <= 105numsis sorted in non-decreasing order.0 <= maxDiff <= 1051 <= queries.length <= 105queries[i] == [ui, vi]0 <= ui, vi < n
Approach overview
Problem Overview: You are given a graph and multiple queries asking whether a path exists between two nodes. Each query must determine if the two vertices belong to the same connected component after considering the given edges.
Approach 1: BFS/DFS Per Query (Brute Force) (Time: O(Q * (V + E)), Space: O(V))
The most direct method is to treat each query independently. For every pair (u, v), run a graph traversal such as BFS or DFS starting from u and check if v is reachable. This uses an adjacency list representation of the graph and a visited array to avoid revisiting nodes. The approach is simple but inefficient when the number of queries is large, since the traversal cost repeats for every query. It works fine for small graphs or when queries are limited, but quickly becomes too slow in competitive programming settings.
Approach 2: Union Find with Query Grouping (Optimal) (Time: O((V + E) α(V) + Q), Space: O(V))
A better strategy is to preprocess the graph using a Disjoint Set Union structure. Iterate through all edges and union their endpoints so that nodes in the same connected component share the same parent. After building these groups, each query reduces to a constant-time check: verify whether find(u) == find(v). This works because if two nodes belong to the same DSU set, there exists some path connecting them through previously processed edges.
The key insight is that connectivity does not change between queries. Instead of recomputing reachability repeatedly, you compress the graph into components once. Path compression and union-by-rank ensure near-constant amortized time for DSU operations. This pattern appears frequently in connectivity problems involving offline queries and is a core technique in Union Find based graph algorithms.
Grouping queries also improves cache locality and avoids repeated traversals. Once components are formed, answering each query is just two parent lookups. This approach scales easily to very large graphs with hundreds of thousands of edges and queries.
Recommended for interviews: Start by explaining the BFS/DFS approach to demonstrate understanding of basic graph traversal. Then transition to the optimized solution using Union Find. Interviewers expect the DSU solution because it reduces repeated work and brings the complexity close to linear time. Mention path compression and union-by-rank to show familiarity with practical DSU optimizations.
Solution
According to the problem description, the node indices within the same connected component must be consecutive. Therefore, we can use an array g to record the connected component index for each node and a variable cnt to track the current connected component index. As we iterate through the nums array, if the difference between the current node and the previous node is greater than maxDiff, it indicates that the current node and the previous node are not in the same connected component. In this case, we increment cnt. Then, we assign the current node's connected component index to cnt.
Finally, for each query (u, v), we only need to check whether g[u] and g[v] are equal. If they are equal, it means u and v are in the same connected component, and the answer for the i-th query is true. Otherwise, the answer is false.
The complexity is O(n), and the space complexity is O(n), where n is the length of the nums array.
class Solution:
    def pathExistenceQueries(
        self, n: int, nums: List[int], maxDiff: int, queries: List[List[int]]
    ) -> List[bool]:
        g = [0] * n
        cnt = 0
        for i in range(1, n):
            if nums[i] - nums[i - 1] > maxDiff:
                cnt += 1
            g[i] = cnt
return [g[u] == g[v] for u, v in queries]class Solution {
public boolean[] pathExistenceQueries(int n, int[] nums, int maxDiff, int[][] queries) {
int[] g = new int[n];
int cnt = 0;
for (int i = 1; i < n; ++i) {
if (nums[i] - nums[i - 1] > maxDiff) {
cnt++;
}
g[i] = cnt;
}
int m = queries.length;
boolean[] ans = new boolean[m];
for (int i = 0; i < m; ++i) {
int u = queries[i][0];
int v = queries[i][1];
ans[i] = g[u] == g[v];
}
return ans;
}
}class Solution {
public:
vector<bool> pathExistenceQueries(int n, vector<int>& nums, int maxDiff, vector<vector<int>>& queries) {
vector<int> g(n);
int cnt = 0;
for (int i = 1; i < n; ++i) {
if (nums[i] - nums[i - 1] > maxDiff) {
++cnt;
}
g[i] = cnt;
}
vector<bool> ans;
for (const auto& q : queries) {
int u = q[0], v = q[1];
ans.push_back(g[u] == g[v]);
}
return ans;
}
};function pathExistenceQueries(
n: number,
nums: number[],
maxDiff: number,
queries: number[][],
): boolean[] {
const g: number[] = Array(n).fill(0);
let cnt = 0;
for (let i = 1; i < n; ++i) {
if (nums[i] - nums[i - 1] > maxDiff) {
++cnt;
}
g[i] = cnt;
}
return queries.map(([u, v]) => g[u] === g[v]);
}func pathExistenceQueries(n int, nums []int, maxDiff int, queries [][]int) (ans []bool) {
g := make([]int, n)
cnt := 0
for i := 1; i < n; i++ {
if nums[i]-nums[i-1] > maxDiff {
cnt++
}
g[i] = cnt
}
for _, q := range queries {
u, v := q[0], q[1]
ans = append(ans, g[u] == g[v])
}
return
}Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| BFS/DFS Per Query | O(Q * (V + E)) | O(V) | Small graphs or very few queries where repeated traversals are acceptable |
| Union Find (DSU) with Grouping | O((V + E) α(V) + Q) | O(V) | Best for many connectivity queries on a static graph |
Frequently asked questions
Is Path Existence Queries in a Graph I easy or hard?
The problem is generally rated Medium because it requires recognizing that repeated reachability checks can be replaced with Union Find preprocessing. The implementation is straightforward once the connectivity insight is identified.
Path Existence Queries in a Graph I Python/Java solution
Typical implementations use a Union Find class with parent and rank arrays. Python, Java, C++, Go, and TypeScript solutions follow the same pattern: union all edges first, then check if find(u) equals find(v) for each query.
How to solve Path Existence Queries in a Graph I in O(n)?
Process all edges once using a Union Find structure to build connected components. Then evaluate each query by comparing the representative parent of both nodes. Because DSU operations are amortized almost constant, the total runtime is close to linear in the number of nodes, edges, and queries.
What is the best approach for Path Existence Queries in a Graph I?
Union Find (Disjoint Set Union) is the most efficient approach. First union all edges to build connected components, then answer each query by checking whether both nodes share the same root. With path compression and union-by-rank, the complexity becomes nearly linear.
Is Path Existence Queries in a Graph I asked at Google/Amazon/Meta?
Connectivity problems using Union Find frequently appear in interviews at companies like Google, Amazon, and Meta. Variants involving graph connectivity, dynamic queries, and DSU optimizations are especially common in algorithm rounds.
What data structure is used in Path Existence Queries in a Graph I?
The key data structure is Disjoint Set Union (Union Find). It maintains groups of connected nodes and supports efficient union and find operations with path compression.
What is the time complexity of Path Existence Queries in a Graph I?
The optimal Union Find solution runs in O((V + E) α(V) + Q) time, where α(V) is the inverse Ackermann function and is effectively constant. Each query becomes an O(1) connectivity check after preprocessing.