Optimize Water Distribution in a Village solution and explanation
 Google

9 more videos on this problem
 LeetCode 1168. Optimize Water Distribution in a VillageHappy Coding · 14:17 · 4K views
 1168 Optimize Water Distribution in a VillageKelvin Chandra · 10:13 · 3K views
 LeetCode 1168. Optimize Water Distribution in a Village Explanation and Solutionhappygirlzt · 13:20 · 2K views
 LeetCode 1168. Optimize Water Distribution in a Village 中文解释 Chinese Versionhappygirlzt · 9:59 · 1K views
 Leetcode 1168 - Optimize Water DistributionThe Coachable Dev · 11:24 · 725 views
 Leetcode 1168. Optimize Water Distribution in a Village | C++ | EnglishUnofficial Sendoh · 14:25 · 485 views
 Leetcode 1168. Optimize Water Distribution in a VillageAlgorithms for Big Bucks · 11:29 · 225 views
 Optimize Water Distribution in a Village | Kruskal's Algorithm + Union Find Solution PythonEmily Bao · 16:27 · 209 views
 Leetcode 1168. Optimize water distribution in a village | Java | Kruskal's algorithmJeezy Leets · 18:37 · 118 views
 #LeetCode 1168 | Optimize Water Distribution in a Village #JavaSleepy Cracker · 17:17 · 38 views
The problem
There are n houses in a village. We want to supply water for all the houses by building wells and laying pipes.
For each house i, we can either build a well inside it directly with cost wells[i - 1] (note the -1 due to 0-indexing), or pipe in water from another well to it. The costs to lay pipes between houses are given by the array pipes where each pipes[j] = [house1j, house2j, costj] represents the cost to connect house1j and house2j together using a pipe. Connections are bidirectional, and there could be multiple valid connections between the same two houses with different costs.
Return the minimum total cost to supply water to all houses.
Example 1:
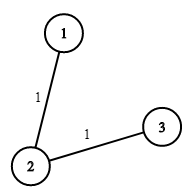
Input: n = 3, wells = [1,2,2], pipes = [[1,2,1],[2,3,1]]
Output: 3
Explanation: The image shows the costs of connecting houses using pipes.
The best strategy is to build a well in the first house with cost 1 and connect the other houses to it with cost 2 so the total cost is 3.
Example 2:
Input: n = 2, wells = [1,1], pipes = [[1,2,1],[1,2,2]]
Output: 2
Explanation: We can supply water with cost two using one of the three options:
Option 1:
  - Build a well inside house 1 with cost 1.
  - Build a well inside house 2 with cost 1.
The total cost will be 2.
Option 2:
  - Build a well inside house 1 with cost 1.
  - Connect house 2 with house 1 with cost 1.
The total cost will be 2.
Option 3:
  - Build a well inside house 2 with cost 1.
  - Connect house 1 with house 2 with cost 1.
The total cost will be 2.
Note that we can connect houses 1 and 2 with cost 1 or with cost 2 but we will always choose the cheapest option.
Constraints:
2 <= n <= 104wells.length == n0 <= wells[i] <= 1051 <= pipes.length <= 104pipes[j].length == 31 <= house1j, house2j <= n0 <= costj <= 105house1j != house2j
Approach overview
Problem Overview: You need to supply water to n houses. Each house can either build its own well with a fixed cost or connect to another house using pipes with installation costs. The goal is to supply water to every house while minimizing the total cost.
This is a classic network optimization problem. Each house is a node and each pipe is an edge with cost. The trick is modeling the option of building a well. Instead of treating wells separately, you add a virtual node (node 0) connected to every house with an edge equal to the well cost. Once modeled this way, the problem becomes finding a Minimum Spanning Tree across all nodes.
Approach 1: Kruskal's Algorithm with Union-Find (Minimum Spanning Tree) (Time: O((n + m) log(n + m)), Space: O(n + m))
Create a virtual node 0 and connect it to each house i with an edge cost equal to wells[i]. Combine these edges with the given pipe edges. Now the graph has n + 1 nodes and n + m edges. Sort all edges by cost and run Kruskal's algorithm.
Use a Union Find (Disjoint Set Union) structure to track connected components. Iterate through the sorted edges, union the endpoints if they are not already connected, and add the edge cost to the total. Once all houses belong to the same component, the MST is complete. The key insight: building a well becomes just another edge choice competing with pipe connections.
Approach 2: Prim's Algorithm with Min Heap (Default Approach) (Time: O((n + m) log n), Space: O(n + m))
This approach builds the MST incrementally using a Priority Queue. Construct an adjacency list for the graph including edges from the virtual node to each house. Start Prim's algorithm from node 0.
Push all edges from the starting node into a min heap ordered by cost. Repeatedly pop the cheapest edge that connects a new house to the growing tree. Mark houses as visited and add their outgoing edges to the heap. Continue until all houses are connected. The heap ensures the algorithm always expands the cheapest possible connection.
Recommended for interviews: Both solutions are valid since the problem is fundamentally a graph Minimum Spanning Tree problem. Kruskal's algorithm with Union-Find is often preferred because the modeling trick (adding a virtual node for wells) clearly converts the problem into a standard MST. Interviewers like this approach because it demonstrates graph modeling skills and familiarity with MST patterns. Prim's algorithm is equally efficient and sometimes simpler if you already have an adjacency list structure.
Approach 1: Kruskal's Algorithm (Minimum Spanning Tree)
We assume that there is a well with the number 0. Then we can consider the connectivity between each house and the well 0 as an edge, and the weight of each edge is the cost of building a well for that house. At the same time, we consider the connectivity between each house as an edge, and the weight of each edge is the cost of laying a pipe. In this way, we can transform this problem into finding the minimum spanning tree of an undirected graph.
We can use Kruskal's algorithm to find the minimum spanning tree of the undirected graph. First, we add an edge between the well 0 and the house to the pipes array, and then sort the pipes array in ascending order of edge weights. Then, we traverse each edge. If this edge connects different connected components, we choose this edge and merge the corresponding connected components. If the current connected component is exactly 1, then we have found the minimum spanning tree. The answer at this time is the current edge weight, and we return it.
The time complexity is O((m + n) times log (m + n)), and the space complexity is O(m + n). Here, m and n are the lengths of the pipes array and the wells array, respectively.
class Solution:
    def minCostToSupplyWater(
        self, n: int, wells: List[int], pipes: List[List[int]]
    ) -> int:
        def find(x: int) -> int:
            if p[x] != x:
                p[x] = find(p[x])
            return p[x]

        for i, w in enumerate(wells, 1):
            pipes.append([0, i, w])
        pipes.sort(key=lambda x: x[2])
        p = list(range(n + 1))
        ans = 0
        for a, b, c in pipes:
            pa, pb = find(a), find(b)
            if pa != pb:
                p[pa] = pb
                n -= 1
                ans += c
                if n == 0:
return ansclass Solution {
private int[] p;
public int minCostToSupplyWater(int n, int[] wells, int[][] pipes) {
int[][] nums = Arrays.copyOf(pipes, pipes.length + n);
for (int i = 0; i < n; i++) {
nums[pipes.length + i] = new int[] {0, i + 1, wells[i]};
}
Arrays.sort(nums, (a, b) -> a[2] - b[2]);
p = new int[n + 1];
for (int i = 0; i <= n; i++) {
p[i] = i;
}
int ans = 0;
for (var x : nums) {
int a = x[0], b = x[1], c = x[2];
int pa = find(a), pb = find(b);
if (pa != pb) {
p[pa] = pb;
ans += c;
if (--n == 0) {
return ans;
}
}
}
return ans;
}
private int find(int x) {
if (p[x] != x) {
p[x] = find(p[x]);
}
return p[x];
}
}class Solution {
public:
int minCostToSupplyWater(int n, vector<int>& wells, vector<vector<int>>& pipes) {
for (int i = 0; i < n; ++i) {
pipes.push_back({0, i + 1, wells[i]});
}
sort(pipes.begin(), pipes.end(), [](const vector<int>& a, const vector<int>& b) {
return a[2] < b[2];
});
int p[n + 1];
iota(p, p + n + 1, 0);
function<int(int)> find = [&](int x) {
if (p[x] != x) {
p[x] = find(p[x]);
}
return p[x];
};
int ans = 0;
for (const auto& x : pipes) {
int pa = find(x[0]), pb = find(x[1]);
if (pa == pb) {
continue;
}
p[pa] = pb;
ans += x[2];
if (--n == 0) {
break;
}
}
return ans;
}
};function minCostToSupplyWater(n: number, wells: number[], pipes: number[][]): number {
for (let i = 0; i < n; ++i) {
pipes.push([0, i + 1, wells[i]]);
}
pipes.sort((a, b) => a[2] - b[2]);
const p = Array(n + 1)
.fill(0)
.map((_, i) => i);
const find = (x: number): number => {
if (p[x] !== x) {
p[x] = find(p[x]);
}
return p[x];
};
let ans = 0;
for (const [a, b, c] of pipes) {
const pa = find(a);
const pb = find(b);
if (pa === pb) {
continue;
}
p[pa] = pb;
ans += c;
if (--n === 0) {
break;
}
}
return ans;
}func minCostToSupplyWater(n int, wells []int, pipes [][]int) (ans int) {
for i, w := range wells {
pipes = append(pipes, []int{0, i + 1, w})
}
sort.Slice(pipes, func(i, j int) bool { return pipes[i][2] < pipes[j][2] })
p := make([]int, n+1)
for i := range p {
p[i] = i
}
var find func(int) int
find = func(x int) int {
if p[x] != x {
p[x] = find(p[x])
}
return p[x]
}
for _, x := range pipes {
pa, pb := find(x[0]), find(x[1])
if pa == pb {
continue
}
p[pa] = pb
ans += x[2]
n--
if n == 0 {
break
}
}
return
}struct UnionFind {
p: Vec<usize>,
size: Vec<usize>,
}
impl UnionFind {
fn new(n: usize) -> Self {
let p: Vec<usize> = (0..n).collect();
let size = vec![1; n];
UnionFind { p, size }
}
fn find(&mut self, x: usize) -> usize {
if self.p[x] != x {
self.p[x] = self.find(self.p[x]);
}
self.p[x]
}
fn union(&mut self, a: usize, b: usize) -> bool {
let pa = self.find(a);
let pb = self.find(b);
if pa == pb {
false
} else if self.size[pa] > self.size[pb] {
self.p[pb] = pa;
self.size[pa] += self.size[pb];
true
} else {
self.p[pa] = pb;
self.size[pb] += self.size[pa];
true
}
}
}
impl Solution {
pub fn min_cost_to_supply_water(n: i32, wells: Vec<i32>, pipes: Vec<Vec<i32>>) -> i32 {
let n = n as usize;
let mut pipes = pipes;
for i in 0..n {
pipes.push(vec![0, (i + 1) as i32, wells[i]]);
}
pipes.sort_by(|a, b| a[2].cmp(&b[2]));
let mut uf = UnionFind::new(n + 1);
let mut ans = 0;
for pipe in pipes {
let a = pipe[0] as usize;
let b = pipe[1] as usize;
let c = pipe[2];
if uf.union(a, b) {
ans += c;
if n == 0 {
break;
}
}
}
ans
}
}Approach 2: Default Approach
class UnionFind:
    __slots__ = ("p", "size")

    def __init__(self, n):
        self.p = list(range(n))
        self.size = [1] * n

    def find(self, x: int) -> int:
        if self.p[x] != x:
            self.p[x] = self.find(self.p[x])
        return self.p[x]

    def union(self, a: int, b: int) -> bool:
        pa, pb = self.find(a), self.find(b)
        if pa == pb:
            return False
        if self.size[pa] > self.size[pb]:
            self.p[pb] = pa
            self.size[pa] += self.size[pb]
        else:
            self.p[pa] = pb
            self.size[pb] += self.size[pa]
        return True


class Solution:
    def minCostToSupplyWater(
        self, n: int, wells: List[int], pipes: List[List[int]]
    ) -> int:
        for i, w in enumerate(wells, 1):
            pipes.append([0, i, w])
        pipes.sort(key=lambda x: x[2])
        uf = UnionFind(n + 1)
        ans = 0
        for a, b, c in pipes:
            if uf.union(a, b):
                ans += c
                n -= 1
                if n == 0:
return ansclass UnionFind {
private int[] p;
private int[] size;
public UnionFind(int n) {
p = new int[n];
size = new int[n];
for (int i = 0; i < n; ++i) {
p[i] = i;
size[i] = 1;
}
}
public int find(int x) {
if (p[x] != x) {
p[x] = find(p[x]);
}
return p[x];
}
public boolean union(int a, int b) {
int pa = find(a), pb = find(b);
if (pa == pb) {
return false;
}
if (size[pa] > size[pb]) {
p[pb] = pa;
size[pa] += size[pb];
} else {
p[pa] = pb;
size[pb] += size[pa];
}
return true;
}
}
class Solution {
public int minCostToSupplyWater(int n, int[] wells, int[][] pipes) {
int[][] nums = Arrays.copyOf(pipes, pipes.length + n);
for (int i = 0; i < n; i++) {
nums[pipes.length + i] = new int[] {0, i + 1, wells[i]};
}
Arrays.sort(nums, (a, b) -> a[2] - b[2]);
UnionFind uf = new UnionFind(n + 1);
int ans = 0;
for (var x : nums) {
int a = x[0], b = x[1], c = x[2];
if (uf.union(a, b)) {
ans += c;
if (--n == 0) {
break;
}
}
}
return ans;
}
}class UnionFind {
public:
UnionFind(int n) {
p = vector<int>(n);
size = vector<int>(n, 1);
iota(p.begin(), p.end(), 0);
}
bool unite(int a, int b) {
int pa = find(a), pb = find(b);
if (pa == pb) {
return false;
}
if (size[pa] > size[pb]) {
p[pb] = pa;
size[pa] += size[pb];
} else {
p[pa] = pb;
size[pb] += size[pa];
}
return true;
}
int find(int x) {
if (p[x] != x) {
p[x] = find(p[x]);
}
return p[x];
}
private:
vector<int> p, size;
};
class Solution {
public:
int minCostToSupplyWater(int n, vector<int>& wells, vector<vector<int>>& pipes) {
for (int i = 0; i < n; ++i) {
pipes.push_back({0, i + 1, wells[i]});
}
sort(pipes.begin(), pipes.end(), [](const vector<int>& a, const vector<int>& b) {
return a[2] < b[2];
});
UnionFind uf(n + 1);
int ans = 0;
for (const auto& x : pipes) {
if (uf.unite(x[0], x[1])) {
ans += x[2];
if (--n == 0) {
break;
}
}
}
return ans;
}
};class UnionFind {
private p: number[];
private size: number[];
constructor(n: number) {
this.p = Array(n)
.fill(0)
.map((_, i) => i);
this.size = Array(n).fill(1);
}
find(x: number): number {
if (this.p[x] !== x) {
this.p[x] = this.find(this.p[x]);
}
return this.p[x];
}
union(a: number, b: number): boolean {
const pa = this.find(a);
const pb = this.find(b);
if (pa === pb) {
return false;
}
if (this.size[pa] > this.size[pb]) {
this.p[pb] = pa;
this.size[pa] += this.size[pb];
} else {
this.p[pa] = pb;
this.size[pb] += this.size[pa];
}
return true;
}
}
function minCostToSupplyWater(n: number, wells: number[], pipes: number[][]): number {
for (let i = 0; i < n; ++i) {
pipes.push([0, i + 1, wells[i]]);
}
pipes.sort((a, b) => a[2] - b[2]);
const uf = new UnionFind(n + 1);
let ans = 0;
for (const [a, b, c] of pipes) {
if (uf.union(a, b)) {
ans += c;
if (--n === 0) {
break;
}
}
}
return ans;
}type unionFind struct {
p, size []int
}
func newUnionFind(n int) *unionFind {
p := make([]int, n)
size := make([]int, n)
for i := range p {
p[i] = i
size[i] = 1
}
return &unionFind{p, size}
}
func (uf *unionFind) find(x int) int {
if uf.p[x] != x {
uf.p[x] = uf.find(uf.p[x])
}
return uf.p[x]
}
func (uf *unionFind) union(a, b int) bool {
pa, pb := uf.find(a), uf.find(b)
if pa == pb {
return false
}
if uf.size[pa] > uf.size[pb] {
uf.p[pb] = pa
uf.size[pa] += uf.size[pb]
} else {
uf.p[pa] = pb
uf.size[pb] += uf.size[pa]
}
return true
}
func minCostToSupplyWater(n int, wells []int, pipes [][]int) (ans int) {
for i, w := range wells {
pipes = append(pipes, []int{0, i + 1, w})
}
sort.Slice(pipes, func(i, j int) bool { return pipes[i][2] < pipes[j][2] })
uf := newUnionFind(n + 1)
for _, x := range pipes {
if uf.union(x[0], x[1]) {
ans += x[2]
n--
if n == 0 {
break
}
}
}
return
}Complexity comparison
| Approach | Complexity |
|---|---|
| Kruskal's Algorithm (Minimum Spanning Tree) | – |
| Default Approach | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Kruskal's Algorithm with Union-Find | O((n + m) log(n + m)) | O(n + m) | Best when edges are easy to list and sort; very common MST interview solution |
| Prim's Algorithm with Min Heap | O((n + m) log n) | O(n + m) | Preferred when using adjacency lists or when expanding the MST incrementally |
Frequently asked questions
Is Optimize Water Distribution in a Village easy or hard?
Optimize Water Distribution in a Village is categorized as a Hard problem because it requires recognizing the Minimum Spanning Tree transformation with a virtual node. Once modeled correctly, the implementation of Kruskal or Prim is standard, but the graph modeling step makes the problem challenging.
Optimize Water Distribution in a Village Python/Java solution
Most implementations use either Kruskal's algorithm with Union-Find or Prim's algorithm with a priority queue. Python solutions typically use heapq for the min heap, while Java implementations use PriorityQueue and a DSU class for Union-Find operations. Both achieve O((n + m) log n) time complexity.
How to solve Optimize Water Distribution in a Village in O(n log n)?
Use Prim's algorithm with a min heap. Represent wells as edges from a virtual node 0 to each house. Start from node 0, push edges into a priority queue, and repeatedly add the smallest cost edge connecting a new house. This builds a Minimum Spanning Tree with time complexity O((n + m) log n).
What is the best approach for Optimize Water Distribution in a Village?
The best approach models the problem as a Minimum Spanning Tree. Add a virtual node connected to every house with edge cost equal to the well cost, then run Kruskal's algorithm with Union-Find. This ensures the algorithm chooses the cheapest option between building a well or connecting via pipes. The overall time complexity is O((n + m) log(n + m)).
Is Optimize Water Distribution in a Village asked at Google/Amazon/Meta?
Minimum Spanning Tree problems similar to this one frequently appear in interviews at companies like Google, Amazon, and Meta. The question tests graph modeling, Union-Find, and MST algorithms such as Kruskal and Prim, which are common interview topics for backend and infrastructure roles.
What data structure is used in Optimize Water Distribution in a Village?
The main data structures are Union-Find (Disjoint Set Union) for Kruskal's algorithm and a Priority Queue (Min Heap) for Prim's algorithm. Both solutions operate on a graph representation of houses and pipes, and both rely on Minimum Spanning Tree techniques.
What is the time complexity of Optimize Water Distribution in a Village?
The optimal MST solutions run in O((n + m) log n) or O((n + m) log(n + m)) time depending on the algorithm used. Kruskal's algorithm requires sorting edges, while Prim's algorithm uses a priority queue to expand the tree. Both approaches use O(n + m) space for storing graph edges and structures.