Maximum Star Sum of a Graph solution and explanation
 Google

6 more videos on this problem
 Maximum Star Sum of a Graph || leetcode Biweekly 93 || Leetcode MediumBinaryMagic · 17:38 · 1K views
 Leetcode 2497 || Maximum Star Sum of a Graph || Leetcode Contest Medium || cppCoding Techniques with Komal | Newton School · 9:15 · 1K views
 2497. Maximum Star Sum of a Graph (Leetcode Medium)Programming Live with Larry · 11:27 · 808 views
 2497 Maximum Star Sum of a Graph | Leetcode Biweekly Contest 93Ashutosh sharma · 16:07 · 539 views
 leetcode 2497. Maximum Star Sum of a Graph - graph concepts and partial sumsCode-Yao · 12:07 · 518 views
 Leetcode 2497. Maximum Star Sum of a Graph | JavaJeezy Leets · 17:54 · 74 views
 Maximum Star Sum of a Graph | LinkedIn Interview Question | Graph | LeetCode 2497 | C++Programming With Niladree - PWN - Bangladesh · 10:33 · 48 views
The problem
There is an undirected graph consisting of n nodes numbered from 0 to n - 1. You are given a 0-indexed integer array vals of length n where vals[i] denotes the value of the ith node.
You are also given a 2D integer array edges where edges[i] = [ai, bi] denotes that there exists an undirected edge connecting nodes ai and bi.
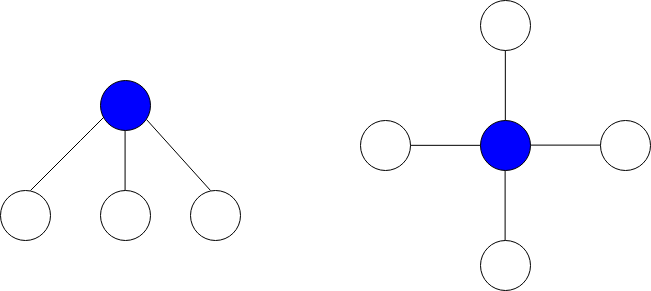
A star graph is a subgraph of the given graph having a center node containing 0 or more neighbors. In other words, it is a subset of edges of the given graph such that there exists a common node for all edges.
The image below shows star graphs with 3 and 4 neighbors respectively, centered at the blue node.
The star sum is the sum of the values of all the nodes present in the star graph.
Given an integer k, return the maximum star sum of a star graph containing at most k edges.
Example 1:
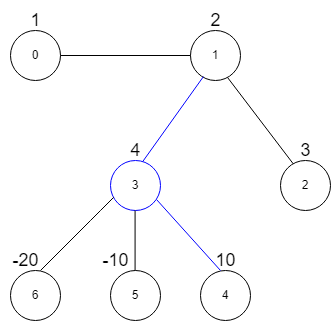
Input: vals = [1,2,3,4,10,-10,-20], edges = [[0,1],[1,2],[1,3],[3,4],[3,5],[3,6]], k = 2
Output: 16
Explanation: The above diagram represents the input graph.
The star graph with the maximum star sum is denoted by blue. It is centered at 3 and includes its neighbors 1 and 4.
It can be shown it is not possible to get a star graph with a sum greater than 16.
Example 2:
Input: vals = [-5], edges = [], k = 0
Output: -5
Explanation: There is only one possible star graph, which is node 0 itself.
Hence, we return -5.
Constraints:
n == vals.length1 <= n <= 105-104 <= vals[i] <= 1040 <= edges.length <= min(n * (n - 1) / 2, 105)edges[i].length == 20 <= ai, bi <= n - 1ai != bi0 <= k <= n - 1
Approach overview
Problem Overview: You are given a graph where each node has a value. A star consists of a center node and up to k of its neighbors. The goal is to choose neighbors that maximize the total star sum (center value + selected neighbor values). You must evaluate every node as a potential center and return the maximum possible sum.
Approach 1: Sorting and Two-Pointer Technique (O(E log E) time, O(E) space)
Build an adjacency list for the graph, then collect the values of all neighbors for each node. Sort the neighbor values in descending order so the largest contributors appear first. From the sorted list, greedily pick up to k positive values and add them to the center node’s value. A two-pointer style scan works well here: start from the largest values and stop when either k neighbors are selected or the values become non‑positive. Sorting ensures you always consider the highest-value neighbors first, which maximizes the star sum.
This approach works because negative neighbors never increase the sum, so they are ignored after sorting. The algorithm iterates through each node, sorts its neighbor values, and accumulates the best k. Time complexity is O(E log E) in the worst case due to sorting neighbor lists, while space complexity is O(E) for the adjacency representation. This method relies heavily on Sorting and greedy selection, making it straightforward to implement in most languages.
Approach 2: Hash Map for Complement Lookup (O(E log k) time, O(E) space)
Use a hash map to build the adjacency list so each node quickly maps to its neighbors. While iterating through edges, track neighbor contributions and maintain only the best k candidates for each center. A bounded structure such as a small heap or ordered container keeps the top positive values without sorting the entire list. The hash map ensures constant-time access to neighbor sets, which is helpful when the graph is large or sparsely connected.
The key idea is to limit storage to the top k positive neighbor values per node. Instead of sorting every neighbor list, maintain a structure that discards smaller values once the size exceeds k. This reduces unnecessary comparisons and keeps the runtime closer to O(E log k). The approach combines Graph traversal with hash-based adjacency storage and optional Heap (Priority Queue) optimization.
Recommended for interviews: The sorting-based greedy approach is the most commonly expected solution. It clearly demonstrates understanding of graph adjacency lists and greedy selection of the largest contributors. Mentioning the optimized variant that keeps only the top k values (using a heap or bounded container) shows stronger algorithmic thinking and awareness of performance tradeoffs.
Approach 1: Approach 1: Sorting and Two-Pointer Technique
This approach involves sorting the dataset and then using the two-pointer technique to find the desired result. Sorting helps to systematically approach the dataset, and using two pointers minimizes the need for nested loops, making the solution efficient.
def find_pairs(arr, target):
    arr.sort()
    left, right = 0, len(arr) - 1

    while left < right:
        current_sum = arr[left] + arr[right]
        if current_sum == target:
            print(f"Pair found: ({arr[left]}, {arr[right]})")
            left += 1
            right -= 1
        elif current_sum < target:
            left += 1
        else:
            right -= 1

arr = [10, 20, 35, 50, 75, 80]
target = 90
find_pairs(arr, target)import java.util.Arrays;
public class TwoPointerSolution {
public static void findPairs(int[] arr, int target) {
Arrays.sort(arr);
int left = 0, right = arr.length - 1;
while (left < right) {
int sum = arr[left] + arr[right];
if (sum == target) {
System.out.println("Pair found: (" + arr[left] + ", " + arr[right] + ")");
left++;
right--;
} else if (sum < target) {
left++;
} else {
right--;
}
}
}
public static void main(String[] args) {
int[] arr = {10, 20, 35, 50, 75, 80};
int target = 90;
findPairs(arr, target);
}
}#include <iostream>
#include <vector>
#include <algorithm>
using namespace std;
void findPairs(vector<int>& arr, int target) {
sort(arr.begin(), arr.end());
int left = 0, right = arr.size() - 1;
while (left < right) {
int sum = arr[left] + arr[right];
if (sum == target) {
cout << "Pair found: (" << arr[left] << ", " << arr[right] << ")\n";
left++;
right--;
} else if (sum < target) {
left++;
} else {
right--;
}
}
}
int main() {
vector<int> arr = {10, 20, 35, 50, 75, 80};
int target = 90;
findPairs(arr, target);
return 0;
}function findPairs(arr, target) {
arr.sort((a, b) => a - b);
let left = 0, right = arr.length - 1;
while (left < right) {
const sum = arr[left] + arr[right];
if (sum === target) {
console.log(`Pair found: (${arr[left]}, ${arr[right]})`);
left++;
right--;
} else if (sum < target) {
left++;
} else {
right--;
}
}
}
const arr = [10, 20, 35, 50, 75, 80];
const target = 90;
findPairs(arr, target);#include <stdio.h>
#include <stdlib.h>
int cmpfunc(const void *a, const void *b) {
return (*(int *)a - *(int *)b);
}
void findPairs(int *arr, int n, int target) {
qsort(arr, n, sizeof(int), cmpfunc);
int left = 0, right = n - 1;
while (left < right) {
int sum = arr[left] + arr[right];
if (sum == target) {
printf("Pair found: (%d, %d)\n", arr[left], arr[right]);
left++;
right--;
} else if (sum < target) {
left++;
} else {
right--;
}
}
}
int main() {
int arr[] = {10, 20, 35, 50, 75, 80};
int target = 90;
int n = sizeof(arr)/sizeof(arr[0]);
findPairs(arr, n, target);
return 0;
}using System;
class TwoPointerSolution {
static void FindPairs(int[] arr, int target) {
Array.Sort(arr);
int left = 0, right = arr.Length - 1;
while (left < right) {
int sum = arr[left] + arr[right];
if (sum == target) {
Console.WriteLine($"Pair found: ({arr[left]}, {arr[right]})");
left++;
right--;
} else if (sum < target) {
left++;
} else {
right--;
}
}
}
public static void Main(string[] args) {
int[] arr = { 10, 20, 35, 50, 75, 80 };
int target = 90;
FindPairs(arr, target);
}
}Python's sort method is used to order the list, facilitating the use of two pointers for evaluating sums. If a sum matches the target, the indices are updated accordingly; otherwise, the left or right pointer is adjusted based on the sum.
Time Complexity: O(n log n) owing to sorting, and O(n) for traversal, yielding overall O(n log n).
Space Complexity: O(1) since the problem uses in-place operations.
Approach 2: Approach 2: Hash Map for Complement Lookup
Another effective approach uses a hash map to track complements of numbers as you iterate through the dataset. This technique allows for constant time lookup of any complement needed to form the target sum, drastically improving efficiency over conventional looping methods.
def find_pairs(arr, target):
    num_map = {}

    for num in arr:
        complement = target - num
        if complement in num_map:
            print(f"Pair found: ({complement}, {num})")
        num_map[num] = True

arr = [10, 20, 35, 50, 75, 80]
target = 90
find_pairs(arr, target)import java.util.HashMap;
public class HashMapSolution {
public static void findPairs(int[] arr, int target) {
HashMap<Integer, Integer> map = new HashMap<>();
for (int num : arr) {
int complement = target - num;
if (map.containsKey(complement)) {
System.out.println("Pair found: (" + complement + ", " + num + ")");
}
map.put(num, num);
}
}
public static void main(String[] args) {
int[] arr = {10, 20, 35, 50, 75, 80};
int target = 90;
findPairs(arr, target);
}
}#include <iostream>
#include <unordered_map>
using namespace std;
void findPairs(int* arr, int n, int target) {
unordered_map<int, int> hashMap;
for (int i = 0; i < n; i++) {
int complement = target - arr[i];
if (hashMap.find(complement) != hashMap.end()) {
cout << "Pair found: (" << complement << ", " << arr[i] << ")\n";
}
hashMap[arr[i]] = i;
}
}
int main() {
int arr[] = {10, 20, 35, 50, 75, 80};
int target = 90;
int n = sizeof(arr) / sizeof(arr[0]);
findPairs(arr, n, target);
return 0;
}function findPairs(arr, target) {
const map = new Map();
for (const num of arr) {
const complement = target - num;
if (map.has(complement)) {
console.log(`Pair found: (${complement}, ${num})`);
}
map.set(num, true);
}
}
const arr = [10, 20, 35, 50, 75, 80];
const target = 90;
findPairs(arr, target);#include <stdio.h>
#include <stdlib.h>
#define HASH_SIZE 1000
struct Node {
int data;
struct Node* next;
};
int hash(int key) {
return abs(key) % HASH_SIZE;
}
void insert(struct Node** table, int key) {
int index = hash(key);
struct Node* newNode = (struct Node *)malloc(sizeof(struct Node));
newNode->data = key;
newNode->next = table[index];
table[index] = newNode;
}
int search(struct Node** table, int key) {
int index = hash(key);
struct Node* node = table[index];
while (node != NULL) {
if (node->data == key)
return 1;
node = node->next;
}
return 0;
}
void findPairs(int* arr, int n, int target) {
struct Node* hashTable[HASH_SIZE] = {NULL};
for (int i = 0; i < n; i++) {
int complement = target - arr[i];
if (search(hashTable, complement)) {
printf("Pair found: (%d, %d)\n", complement, arr[i]);
}
insert(hashTable, arr[i]);
}
}
int main() {
int arr[] = {10, 20, 35, 50, 75, 80};
int target = 90;
int n = sizeof(arr) / sizeof(arr[0]);
findPairs(arr, n, target);
return 0;
}using System;
using System.Collections.Generic;
class HashMapSolution {
static void FindPairs(int[] arr, int target) {
Dictionary<int, int> map = new Dictionary<int, int>();
foreach (var num in arr) {
int complement = target - num;
if (map.ContainsKey(complement)) {
Console.WriteLine($"Pair found: ({complement}, {num})");
}
map[num] = num;
}
}
public static void Main(string[] args) {
int[] arr = { 10, 20, 35, 50, 75, 80 };
int target = 90;
FindPairs(arr, target);
}
}Python's dictionary acts similarly to a hash map, storing numbers from the list and checking each for its complement. If found, it logs the discovered pair, demonstrating efficient search and insertion.
Time Complexity: O(n) given average constant time for dictionary operations.
Space Complexity: O(n) due to necessary storage in the hash map equivalent.
Approach 3: Default Approach
func maxStarSum(vals []int, edges [][]int, k int) (ans int) {
	n := len(vals)
	g := make([][]int, n)
	for _, e := range edges {
		a, b := e[0], e[1]
		if vals[b] > 0 {
			g[a] = append(g[a], vals[b])
		}
		if vals[a] > 0 {
			g[b] = append(g[b], vals[a])
		}
	}
	for _, e := range g {
		sort.Sort(sort.Reverse(sort.IntSlice(e)))
	}
	ans = math.MinInt32
	for i, v := range vals {
		for j := 0; j < min(len(g[i]), k); j++ {
			v += g[i][j]
		}
		ans = max(ans, v)
	}
	return
}Complexity comparison
| Approach | Complexity |
|---|---|
| Approach 1: Sorting and Two-Pointer Technique | Time Complexity: O(n log n) owing to sorting, and O(n) for traversal, yielding overall O(n log n). |
| Approach 2: Hash Map for Complement Lookup | Time Complexity: O(n) given average constant time for dictionary operations. |
| Default Approach | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Sorting and Two-Pointer Technique | O(E log E) | O(E) | Simple implementation when neighbor lists are small or sorting overhead is acceptable |
| Hash Map with Top-K Tracking | O(E log k) | O(E) | Large graphs where maintaining only the top k neighbors avoids repeated sorting |
Frequently asked questions
Is Maximum Star Sum of a Graph easy or hard?
Maximum Star Sum of a Graph is classified as a Medium difficulty problem. The main challenge is recognizing that only the top k positive neighbors matter and implementing an efficient way to select them using sorting or a heap.
Maximum Star Sum of a Graph Python/Java solution
A Python or Java solution builds an adjacency list, gathers neighbor values for each node, sorts them in descending order, and sums the top k positive values with the center node. The same logic translates directly to C++, JavaScript, and other languages using built‑in sorting utilities.
How to solve Maximum Star Sum of a Graph in O(n)?
Strict O(n) is difficult because neighbor values must be compared to find the top contributors. A near‑linear approach maintains a small heap of size k for each node while processing edges. This avoids full sorting and keeps the complexity closer to O(E log k), which performs well when k is small.
What is the best approach for Maximum Star Sum of a Graph?
The most practical solution builds an adjacency list and sorts neighbor values for each node. After sorting in descending order, add up to k positive neighbor values to the center node’s value. This greedy method ensures the largest contributions are selected first and runs in about O(E log E) time.
Is Maximum Star Sum of a Graph asked at Google/Amazon/Meta?
Graph problems involving greedy selection and neighbor aggregation appear frequently in interviews at companies like Google, Amazon, and Meta. Variants that combine adjacency lists with heaps or sorting are common because they test both graph representation and optimization skills.
What data structure is used in Maximum Star Sum of a Graph?
The solution typically uses an adjacency list to represent the graph, along with arrays or lists for node values. Many optimized implementations also use a heap (priority queue) to maintain the top k neighbor values efficiently.
What is the time complexity of Maximum Star Sum of a Graph?
The common greedy approach using sorted neighbor lists runs in O(E log E) time, where E is the number of edges. Each node evaluates its neighbors after sorting their values. With an optimization that keeps only the top k neighbors using a heap, the complexity improves to roughly O(E log k).