
Longest Special Path II - Solution & Explanation
Problem Statement
You are given an undirected tree rooted at node 0, with n nodes numbered from 0 to n - 1. This is represented by a 2D array edges of length n - 1, where edges[i] = [ui, vi, lengthi] indicates an edge between nodes ui and vi with length lengthi. You are also given an integer array nums, where nums[i] represents the value at node i.
A special path is defined as a downward path from an ancestor node to a descendant node in which all node values are distinct, except for at most one value that may appear twice.
Return an array result of size 2, where result[0] is the length of the longest special path, and result[1] is the minimum number of nodes in all possible longest special paths.
Example 1:
Input: edges = [[0,1,1],[1,2,3],[1,3,1],[2,4,6],[4,7,2],[3,5,2],[3,6,5],[6,8,3]], nums = [1,1,0,3,1,2,1,1,0]
Output: [9,3]
Explanation:
In the image below, nodes are colored by their corresponding values in nums.
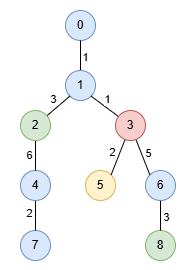
The longest special paths are 1 -> 2 -> 4 and 1 -> 3 -> 6 -> 8, both having a length of 9. The minimum number of nodes across all longest special paths is 3.
Example 2:
Input: edges = [[1,0,3],[0,2,4],[0,3,5]], nums = [1,1,0,2]
Output: [5,2]
Explanation:
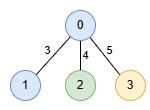
The longest path is 0 -> 3 consisting of 2 nodes with a length of 5.
Constraints:
2 <= n <= 5 * 104edges.length == n - 1edges[i].length == 30 <= ui, vi < n1 <= lengthi <= 103nums.length == n0 <= nums[i] <= 5 * 104- The input is generated such that
edgesrepresents a valid tree.
Approach Overview
Problem Overview: You are given a tree where each node has a value and edges may contribute to path length. A path is considered special if all node values on that path are unique. The task is to compute the maximum length of such a path while traversing the tree.
Approach 1: Brute Force DFS From Every Node (O(n^2) time, O(n) space)
The most direct idea is to start a Depth-First Search from every node and explore all possible downward paths. While traversing, maintain a set of values already used in the current path. If a node value appears again, stop exploring that branch. Track the path length using cumulative edge weights or node depth. This guarantees correctness but becomes expensive because each DFS may explore nearly the entire tree, leading to O(n^2) time in the worst case with O(n) recursion stack and set storage.
Approach 2: DFS with Prefix Distance + Last Occurrence Map (O(n) time, O(n) space)
The optimized approach treats the root‑to‑node traversal like a sliding window on a tree path. During a single depth-first search, maintain a prefix distance array that stores the total path length from the root to each depth. Use a hash map to record the most recent depth where each value appeared. When visiting a node, check whether its value already exists in the current path. If it does, move the left boundary of the valid window to the depth after the previous occurrence.
This technique mirrors the classic "longest substring without repeating characters" pattern but applied to a tree path instead of a linear array. The valid segment of the current DFS path always contains unique values. Using the prefix distance array, you can compute the length of the valid segment in O(1). While backtracking, restore the previous last‑seen depth for the value so other branches are unaffected.
The algorithm processes each node exactly once and performs constant‑time updates to the hash table. Combined with a single traversal of the tree, the total complexity becomes O(n) time with O(n) additional space for recursion, prefix distances, and the value index map.
Recommended for interviews: Interviewers expect the optimized DFS solution using prefix sums and a last‑occurrence map. The brute force approach shows you understand the uniqueness constraint and DFS traversal, but the prefix‑based sliding window demonstrates stronger algorithmic insight and the ability to adapt array techniques to tree paths.
Solutions for this problem are being prepared.
Try solving it yourselfDetailed Complexity Analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Brute Force DFS from Every Node | O(n^2) | O(n) | Good for understanding the constraint of unique node values and exploring all possible paths. |
| DFS with Prefix Distance and Hash Map | O(n) | O(n) | Optimal solution for large trees. Tracks last occurrence of values and maintains a sliding window along the DFS path. |
Video Solution
3486. Longest Special Path II (Leetcode Hard) • Programming Live with Larry • 285 views views
Frequently Asked Questions
Is Longest Special Path II easy or hard?
Longest Special Path II Python/Java solution
How to solve Longest Special Path II in O(n)?
What is the best approach for Longest Special Path II?
Is Longest Special Path II asked at Google/Amazon/Meta?
What data structure is used in Longest Special Path II?
What is the time complexity of Longest Special Path II?
Ready to solve this problem?
Practice Longest Special Path II with our built-in code editor and test cases.
Practice on FleetCode