
Linked List Cycle II - Solution & Explanation
Problem Statement
Given the head of a linked list, return the node where the cycle begins. If there is no cycle, return null.
There is a cycle in a linked list if there is some node in the list that can be reached again by continuously following the next pointer. Internally, pos is used to denote the index of the node that tail's next pointer is connected to (0-indexed). It is -1 if there is no cycle. Note that pos is not passed as a parameter.
Do not modify the linked list.
Example 1:
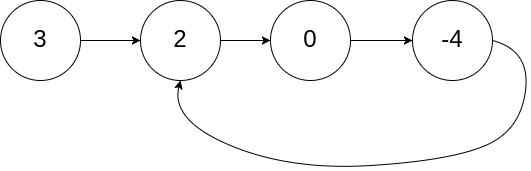
Input: head = [3,2,0,-4], pos = 1
Output: tail connects to node index 1
Explanation: There is a cycle in the linked list, where tail connects to the second node.
Example 2:
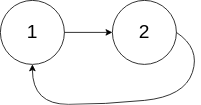
Input: head = [1,2], pos = 0
Output: tail connects to node index 0
Explanation: There is a cycle in the linked list, where tail connects to the first node.
Example 3:

Input: head = [1], pos = -1
Output: no cycle
Explanation: There is no cycle in the linked list.
Constraints:
- The number of the nodes in the list is in the range
[0, 104]. -105 <= Node.val <= 105posis-1or a valid index in the linked-list.
Follow up: Can you solve it using O(1) (i.e. constant) memory?
Approach Overview
Problem Overview: Given the head of a linked list, detect whether a cycle exists and return the node where the cycle begins. If the list has no cycle, return null. The challenge is identifying the exact entry point of the loop rather than just detecting the loop.
Approach 1: Hash Table (O(n) time, O(n) space)
This approach walks through the list while storing each visited node in a hash set. For every node, check if it already exists in the set. The first node that appears twice is the start of the cycle because traversal re-enters the loop at that point. Each step performs a constant-time hash lookup and insertion, resulting in O(n) time complexity and O(n) extra space. The implementation is straightforward and useful when clarity is preferred over memory efficiency. It relies heavily on quick membership checks using a hash table while traversing the linked list.
Approach 2: Floyd's Cycle Detection Algorithm (O(n) time, O(1) space)
This method uses the classic tortoise and hare technique with two pointers. Move slow one step at a time and fast two steps at a time. If a cycle exists, the two pointers eventually meet inside the loop. Once they meet, reset one pointer to the head and move both pointers one step at a time. The node where they meet again is the start of the cycle. The mathematical insight is that the distance from head to cycle start equals the distance from meeting point to cycle start within the loop. This technique runs in O(n) time with O(1) space and avoids additional data structures. It is a classic application of two pointers combined with linked list traversal.
Recommended for interviews: Floyd's Cycle Detection Algorithm is the expected solution in most interviews. The hash table approach shows you understand cycle detection conceptually, but the two-pointer technique demonstrates deeper algorithmic reasoning and constant-space optimization. Interviewers often follow up by asking why resetting one pointer to the head works mathematically, so understanding the distance relationship inside the cycle is valuable.
Approach 1: Floyd's Cycle Detection Algorithm
The Floyd's Cycle Detection Algorithm, also known as the tortoise and hare algorithm, is well-suited for detecting cycles in a linked list.
In this approach, two pointers (slow and fast) are initiated. The slow pointer moves one step at a time, while the fast pointer moves two steps. If a cycle is present, the fast pointer will meet the slow pointer within the cycle. Once a cycle is detected, reset one pointer to the head of the linked list and keep the other pointer at the meeting point. Move both pointers one step at a time; the node where they meet again is the cycle's start.
The C implementation sets up a tortoise (slow) and a hare (fast) pointer. In a loop, it increments each one according to their respective speeds. If a collision between slow and fast occurs, a cycle is detected. The fast pointer is then set to the head of the list, and both slow and fast point to the next pointers. When they meet again, the node is returned as the starting point of the cycle.
Complexity
Time Complexity: O(n) - The list is traversed twice at most.
Space Complexity: O(1) - No additional space apart from pointers.
Approach 2: Hash Table Approach
This approach involves using a hash table (or set) to record visited nodes. Traverse the linked list, and for each node, check if it has already been seen (exists in the hash set). If it has, a cycle is detected that starts at this node. If the end of the list is reached without seeing any node twice, the list does not contain a cycle.
Though this technique uses extra space for the data structure, it can be easier to implement and understand.
This C solution creates a hash table, inserting each visited node with a hashed pointer as the key. If a node is found in the table during traversal, it's part of the cycle's start and returned. Otherwise, the list is acyclic.
Complexity
Time Complexity: O(n) - each node is visited once.
Space Complexity: O(n) - for the hash table.
Approach 3: Two Pointers
We first use the fast and slow pointers to judge whether the linked list has a ring. If there is a ring, the fast and slow pointers will definitely meet, and the meeting node must be in the ring.
If there is no ring, the fast pointer will reach the tail of the linked list first, and return null directly.
If there is a ring, we then define an answer pointer ans to point to the head of the linked list, and then let ans and the slow pointer move forward together, moving one step at a time, until ans and the slow pointer meet, and the meeting node is the ring entrance node.
Why can this find the entrance node of the ring?
Let's assume that the distance from the head node of the linked list to the entrance of the ring is x, the distance from the entrance of the ring to the meeting node is y, and the distance from the meeting node to the entrance of the ring is z. Then the distance traveled by the slow pointer is x + y, and the distance traveled by the fast pointer is x + y + k times (y + z), where k is the number of times the fast pointer goes around the ring.
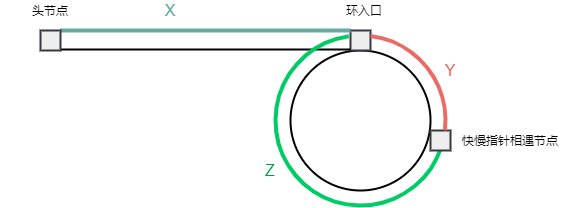
Because the speed of the fast pointer is twice that of the slow pointer, it is 2 times (x + y) = x + y + k times (y + z), which can be deduced that x + y = k times (y + z), that is x = (k - 1) times (y + z) + z.
That is to say, if we define an answer pointer ans to point to the head of the linked list, and the ans and the slow pointer move forward together, they will definitely meet at the ring entrance.
The time complexity is O(n), where n is the number of nodes in the linked list. The space complexity is O(1).
Code
Python
Java
C++
Go
TypeScript
JavaScript
Complexity Comparison
| Approach | Complexity |
|---|---|
| Floyd's Cycle Detection Algorithm | Time Complexity: O(n) - The list is traversed twice at most. |
| Hash Table Approach | Time Complexity: O(n) - each node is visited once. |
| Two Pointers | — |
Detailed Complexity Analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Hash Table | O(n) | O(n) | Simpler implementation when extra memory is acceptable |
| Floyd's Cycle Detection (Two Pointers) | O(n) | O(1) | Optimal interview solution when constant space is required |
Video Solution
LeetCode 142 | Linked List Cycle II | Algorithm Explained (Java + Whiteboard) • Xavier Elon • 25,615 views views
Watch 9 more video solutions →Frequently Asked Questions
Is Linked List Cycle II easy or hard?
How to solve Linked List Cycle II in O(n)?
What is the best approach for Linked List Cycle II?
What data structure is used in Linked List Cycle II?
What is the time complexity of Linked List Cycle II?
Linked List Cycle II Python or Java solution available?
Is Linked List Cycle II asked at Google, Amazon, or Meta?
Ready to solve this problem?
Practice Linked List Cycle II with our built-in code editor and test cases.
Practice on FleetCodeProblem Info
Table of Contents
Practice this problem
Open in Editor