Keyboard Row solution and explanation
 Google

9 more videos on this problem
 500. Keyboard Row | LEETCODE EASY | BRUTE FORCE | CODE EXPLAINERcode Explainer · 6:00 · 4K views
 500. Keyboard Row || Java || Leetcode || HindiCoding Sphere · 10:51 · 3K views
 Leetcode 500: Keyboard Row | C++Blake Wright · 6:03 · 2K views
 LeetCode 500. Keyboard Row Solution Explained - JavaAlgorithms and Data Structures Course · 3:46 · 1K views
 500. Keyboard Row || leetcode || easy question || logical questioncode Explainer · 3:47 · 989 views
 500. Keyboard Row | Leetcode | PythonAbdullah Arshed · 3:05 · 948 views
 500. Keyboard Row || LEETCODE SOLUTION || IN C++ || DATA STRUCTURE AND ALGORITHMAbhishweta Gupta · 4:54 · 855 views
 500. Keyboard Row (Leetcode Easy)Programming Live with Larry · 4:18 · 546 views
 500. Keyboard Row - Daily Leetcode (Day 43)yeetcode · 9:42 · 537 views
 How to Solve "500 Keyboard Row" on LeetCode? - JavascriptBecoming A Better Dev (with David) · 9:14 · 524 views
The problem
Given an array of strings words, return the words that can be typed using letters of the alphabet on only one row of American keyboard like the image below.
Note that the strings are case-insensitive, both lowercased and uppercased of the same letter are treated as if they are at the same row.
In the American keyboard:
- the first row consists of the characters
"qwertyuiop", - the second row consists of the characters
"asdfghjkl", and - the third row consists of the characters
"zxcvbnm".
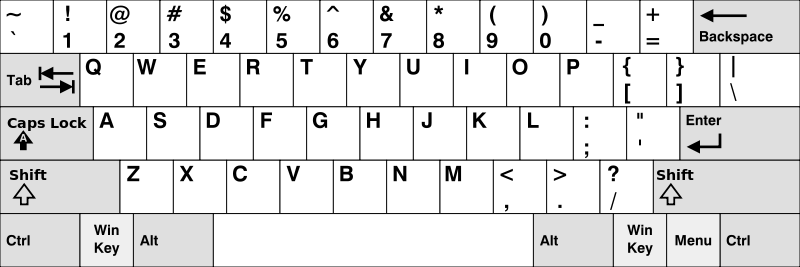
Example 1:
Input: words = ["Hello","Alaska","Dad","Peace"]
Output: ["Alaska","Dad"]
Explanation:
Both "a" and "A" are in the 2nd row of the American keyboard due to case insensitivity.
Example 2:
Input: words = ["omk"]
Output: []
Example 3:
Input: words = ["adsdf","sfd"]
Output: ["adsdf","sfd"]
Constraints:
1 <= words.length <= 201 <= words[i].length <= 100words[i]consists of English letters (both lowercase and uppercase).
Approach overview
Problem Overview: You get a list of words and need to return only those that can be typed using letters from a single row of the American keyboard. The three rows are qwertyuiop, asdfghjkl, and zxcvbnm. For each word, verify that every character belongs to the same row.
Approach 1: Using Sets for Each Keyboard Row (O(N) time, O(1) space)
Create three set objects representing the keyboard rows. Iterate through each word in the input array. Convert the word to lowercase, then check whether every character exists in one of the three sets. A simple way is to verify that the set of characters in the word is a subset of a row set. If the condition holds for any row, add the word to the result list.
The key insight is that set lookups run in constant time, so each character check is efficient. The total work is proportional to the number of characters processed across all words. This solution directly models the keyboard layout and keeps the code readable. Time complexity is O(N) where N is the total number of characters across all words, and space complexity is O(1) since the keyboard rows contain a fixed number of letters. This approach heavily relies on fast membership checks using a Hash Table-style structure.
Approach 2: Mapping Characters to Rows (O(N) time, O(1) space)
Instead of storing three sets, build a mapping from each character to its keyboard row index (for example, {'q':1, 'w':1, ..., 'a':2, ..., 'z':3}). For each word, look up the row of the first character. Then iterate through the remaining characters and verify that every character maps to the same row number. If any character belongs to a different row, discard the word.
This approach uses a single hash map for constant-time row lookup. The benefit is that each character comparison becomes a quick integer equality check after the map lookup. It avoids repeated subset checks and is easy to implement in languages like Java or JavaScript. Time complexity remains O(N) because every character is visited once, and space complexity is O(1) since the map stores only 26 lowercase letters.
The input itself is a simple Array of words, and each word is processed character by character as a String. Both approaches scale linearly with the total input size and are efficient for typical interview constraints.
Recommended for interviews: The character-to-row mapping approach is typically what interviewers expect. It shows that you can preprocess a small lookup table and perform a single pass over the input. The set-based solution is equally correct and often shorter to implement, which makes it great for quick coding rounds. Showing both demonstrates that you understand the tradeoff between direct modeling (sets) and optimized lookups (mapping).
Approach 1: Using Sets for Each Keyboard Row
This approach involves creating a set for each row of the keyboard. Each word is then checked against these sets to see if all of its letters are contained entirely within one of the sets, making use of set comparison for simplicity.
def findWords(words):
    row1 = set('qwertyuiop')
    row2 = set('asdfghjkl')
    row3 = set('zxcvbnm')

    result = []
    for word in words:
        lower_word_set = set(word.lower())
        if lower_word_set <= row1 or lower_word_set <= row2 or lower_word_set <= row3:
            result.append(word)
return result#include <stdio.h>
#include <stdbool.h>
#include <string.h>
bool canBeTypedOnSameRow(const char *word, const char *rows) {
int rowMask = 0;
while (*word) {
char c = tolower(*word);
if (strchr(rows, c) != NULL) {
rowMask |= 1;
} else {
return false;
}
word++;
}
return rowMask != 0;
}
char** findWords(char **words, int wordsSize, int* returnSize) {
static char *result[20]; // Max size according to the constraints
int resultSize = 0;
const char *rows[] = {"qwertyuiop", "asdfghjkl", "zxcvbnm"};
for (int i = 0; i < wordsSize; ++i) {
for (int j = 0; j < 3; ++j) {
if (canBeTypedOnSameRow(words[i], rows[j])) {
result[resultSize++] = words[i];
break;
}
}
}
*returnSize = resultSize;
return result;
}We use sets to represent each keyboard row and for each word, transform it into a lowercase set. By checking if the set of the word is a subset of any of the row sets, we determine if the word can be typed on one keyboard row. The subset check leverages fast set operations in Python.
Time Complexity: O(n * m), where n is the number of words, and m is the maximum length of a word. Space Complexity: O(1) additional space, not counting the space taken by the output.
Approach 2: Mapping Characters to Rows
This approach maps each character to a corresponding row number. For each word, we check the row number of every character and ensure they all match. If they do, the word can be added to the list of results.
import java.util.*;

public class KeyboardRow {
    public String[] findWords(String[] words) {
        Map<Character, Integer> charToRow = new HashMap<>();
        String[] rows = {"qwertyuiop", "asdfghjkl", "zxcvbnm"};

        for (int i = 0; i < rows.length; ++i) {
            for (char c : rows[i].toCharArray()) {
                charToRow.put(c, i);
            }
        }

        List<String> result = new ArrayList<>();
        outer: for (String word : words) {
            int rowIndex = charToRow.get(Character.toLowerCase(word.charAt(0)));
            for (char c : word.toLowerCase().toCharArray()) {
                if (charToRow.get(c) != rowIndex) {
                    continue outer;
                }
            }
            result.add(word);
        }

        return result.toArray(new String[0]);
    }
}function findWords(words) {
const rows = [
new Set('qwertyuiop'),
new Set('asdfghjkl'),
new Set('zxcvbnm')
];
const result = [];
for (const word of words) {
const lower = word.toLowerCase();
for (const row of rows) {
if (Array.from(lower).every(char => row.has(char))) {
result.push(word);
break;
}
}
}
return result;
}A map is used to first assign each character a row number. Then, for each word, we assign a row based on the first character and check each subsequent character to ensure they belong to the same row. This uses an `outer` label to break from nested loops efficiently.
Time Complexity: O(n * m), where n is the number of words, and m is the maximum length of a word. Space Complexity: O(1) additional space for the map used to store row indices.
Approach 3: Default Approach
class Solution {
public:
    vector<string> findWords(vector<string>& words) {
        string s = "12210111011122000010020202";
        vector<string> ans;
        for (auto& w : words) {
            char x = s[tolower(w[0]) - 'a'];
            bool ok = true;
            for (char& c : w) {
                if (s[tolower(c) - 'a'] != x) {
                    ok = false;
                    break;
                }
            }
            if (ok) {
                ans.emplace_back(w);
            }
        }
        return ans;
    }
};function findWords(words: string[]): string[] {
const s = '12210111011122000010020202';
const ans: string[] = [];
for (const w of words) {
const t = w.toLowerCase();
const x = s[t.charCodeAt(0) - 'a'.charCodeAt(0)];
let ok = true;
for (const c of t) {
if (s[c.charCodeAt(0) - 'a'.charCodeAt(0)] !== x) {
ok = false;
break;
}
}
if (ok) {
ans.push(w);
}
}
return ans;
}public class Solution {
public string[] FindWords(string[] words) {
string s = "12210111011122000010020202";
IList<string> ans = new List<string>();
foreach (string w in words) {
char x = s[char.ToLower(w[0]) - 'a'];
bool ok = true;
for (int i = 1; i < w.Length; ++i) {
if (s[char.ToLower(w[i]) - 'a'] != x) {
ok = false;
break;
}
}
if (ok) {
ans.Add(w);
}
}
return ans.ToArray();
}
}func findWords(words []string) (ans []string) {
s := "12210111011122000010020202"
for _, w := range words {
x := s[unicode.ToLower(rune(w[0]))-'a']
ok := true
for _, c := range w[1:] {
if s[unicode.ToLower(c)-'a'] != x {
ok = false
break
}
}
if ok {
ans = append(ans, w)
}
}
return
}Complexity comparison
| Approach | Complexity |
|---|---|
| Using Sets for Each Keyboard Row | Time Complexity: O(n * m), where n is the number of words, and m is the maximum length of a word. Space Complexity: O(1) additional space, not counting the space taken by the output. |
| Mapping Characters to Rows | Time Complexity: O(n * m), where n is the number of words, and m is the maximum length of a word. Space Complexity: O(1) additional space for the map used to store row indices. |
| Default Approach | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Using Sets for Each Keyboard Row | O(N) | O(1) | When you want a simple and readable implementation using set membership checks |
| Mapping Characters to Rows | O(N) | O(1) | Preferred in interviews for efficient lookups and a single pass per word |
Frequently asked questions
Is Keyboard Row easy or hard?
Keyboard Row is classified as an Easy problem. It mainly tests basic string iteration and the use of hash-based data structures like sets or maps. Most solutions are implemented in a few lines once the keyboard row grouping is defined.
Keyboard Row Python/Java solution
Python solutions often use sets and the subset check for concise code. Java implementations typically build a character-to-row map and verify that every letter in the word belongs to the same row. Both implementations run in O(N) time with constant extra space.
How to solve Keyboard Row in O(n)?
Build a lookup structure that tells you which keyboard row each character belongs to. Iterate through every word, record the row of the first character, and verify that all remaining characters belong to the same row. Because each character is checked once, the algorithm runs in O(N) time.
What is the best approach for Keyboard Row?
The most common approach maps each character to a keyboard row using a hash map. For each word, check whether all characters map to the same row index. This allows a single pass through each word with constant-time lookups, resulting in O(N) time where N is the total number of characters.
Is Keyboard Row asked at Google/Amazon/Meta?
Keyboard Row is an easy-level string and hash table problem often used in screening rounds or practice sets. While top companies like Google or Meta rarely ask it directly in final interviews, it appears in preparation lists and coding platforms as a warm-up problem.
What data structure is used in Keyboard Row?
Hash-based structures such as sets or hash maps are commonly used. Sets represent each keyboard row and allow constant-time membership checks, while a hash map can map each character to its row index for quick comparisons.
What is the time complexity of Keyboard Row?
The time complexity is O(N), where N is the total number of characters across all words. Each character is processed once while checking its keyboard row. Space complexity is O(1) because only a fixed set or mapping of 26 letters is stored.