K Closest Points to Origin solution and explanation
 Google

9 more videos on this problem
 K Closest Points to Origin - Heap / Priority Queue - Leetcode 973 - PythonNeetCode · 9:29 · 139K views
 K Closest Points to OriginKevin Naughton Jr. · 5:02 · 53K views
 K Closest Points to Origin | Leetcode #973Techdose · 9:18 · 25K views
 K Closest Points to Origin - Leetcode 973 - Heaps (Python)Greg Hogg · 9:47 · 11K views
 K Closest Points to Origin - LeetCode 973 - Python [O(n) time!]Deepti Talesra · 15:49 · 8K views
 K CLOSEST POINTS TO ORIGIN | LEETCODE 973 | PYTHON SOLUTIONCracking FAANG · 14:10 · 3K views
 [Java] Leetcode 973. K Closest Points to Origin [Top K Elements #3]Eric Programming · 10:26 · 3K views
 K Closest Points to Origin | K Closest Points to Origin LeetCode Java | LeetCode - 973The Code Mate · 6:52 · 3K views
 LeetCode Problem 973: K Closest Points to Origin in Java - FAANG Coding Interview - Blind 75KeyStrokes · 17:32 · 1K views
 973. K Closest Points to Origin - Heap - LeetCode - JavaScriptLeetCodeWithMonu · 11:22 · 870 views
The problem
Given an array of points where points[i] = [xi, yi] represents a point on the X-Y plane and an integer k, return the k closest points to the origin (0, 0).
The distance between two points on the X-Y plane is the Euclidean distance (i.e., √(x1 - x2)2 + (y1 - y2)2).
You may return the answer in any order. The answer is guaranteed to be unique (except for the order that it is in).
Example 1:
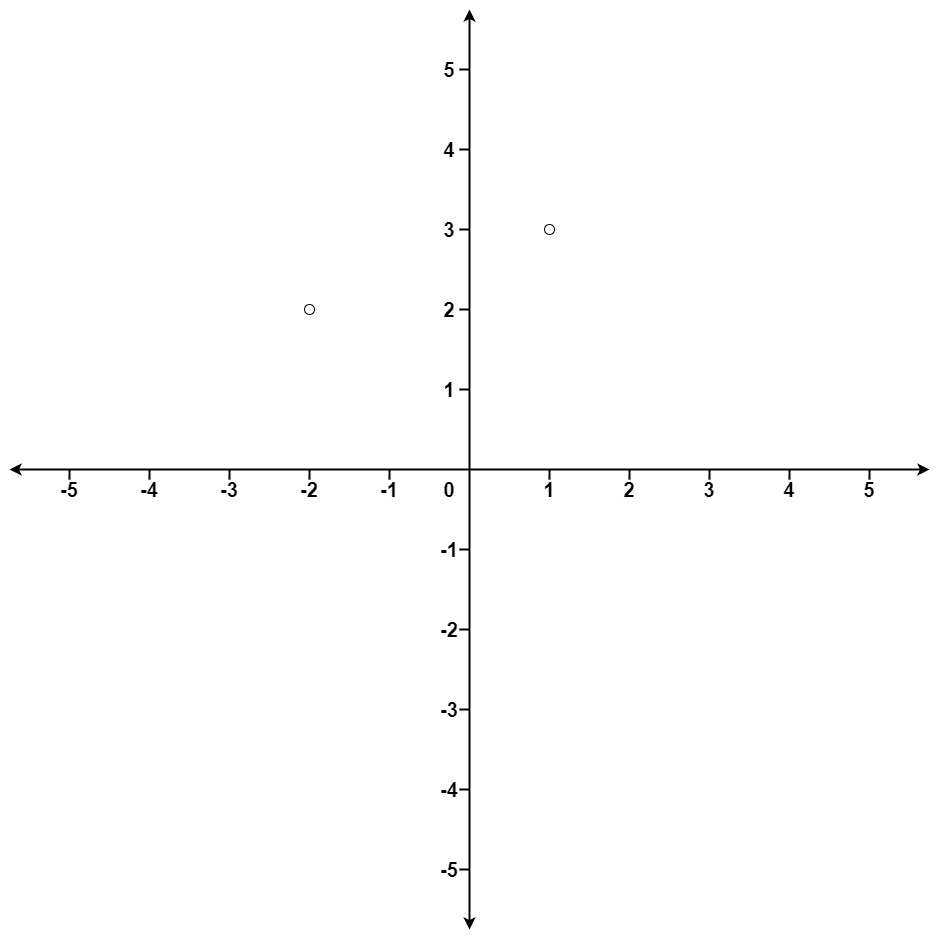
Input: points = [[1,3],[-2,2]], k = 1
Output: [[-2,2]]
Explanation:
The distance between (1, 3) and the origin is sqrt(10).
The distance between (-2, 2) and the origin is sqrt(8).
Since sqrt(8) < sqrt(10), (-2, 2) is closer to the origin.
We only want the closest k = 1 points from the origin, so the answer is just [[-2,2]].
Example 2:
Input: points = [[3,3],[5,-1],[-2,4]], k = 2
Output: [[3,3],[-2,4]]
Explanation: The answer [[-2,4],[3,3]] would also be accepted.
Constraints:
1 <= k <= points.length <= 104-104 <= xi, yi <= 104
Approach overview
Problem Overview: You are given an array of 2D points and an integer k. Each point represents (x, y) on a Cartesian plane. Return the k points closest to the origin (0,0). Distance is measured using Euclidean distance, but you only need the squared distance x*x + y*y for comparisons.
Approach 1: Sort and Select (O(n log n) time, O(1) or O(n) space)
The simplest strategy computes the squared distance for every point and sorts the array by that value. After sorting, the first k points are the closest. Sorting guarantees correct ordering but does more work than required because the entire list is ordered even though you only need the smallest k elements. This approach relies on standard sorting algorithms and is often the easiest implementation across languages.
Approach 2: Max-Heap (Priority Queue) (O(n log k) time, O(k) space)
A more efficient method maintains a max-heap of size k. Iterate through all points, compute the squared distance, and push the point into the heap. If the heap size exceeds k, remove the farthest element (the heap root). The heap always stores the k closest points seen so far. Each insertion or removal costs O(log k), which leads to O(n log k) total time. This method is common in interview problems involving streaming or partial selection and uses a heap (priority queue) to maintain the top candidates efficiently.
Approach 3: Quickselect (Average O(n) time, O(1) extra space)
Quickselect applies the partition logic from quicksort to position the k-th closest distance in the correct place. Choose a pivot, partition the points so those with smaller distances move to the left, and recursively process only the relevant side. Once the pivot index equals k, the first k elements contain the closest points (order does not matter). This technique falls under divide and conquer and avoids fully sorting the array. Average runtime is O(n), though the worst case is O(n^2). In practice it performs very well and is the optimal theoretical solution.
Recommended for interviews: Start with the sorting idea to show clarity, then move to the max-heap solution since it improves complexity to O(n log k) and is widely accepted in interviews. If the interviewer pushes for optimal performance, implement Quickselect for average O(n) time. Demonstrating both heap and selection algorithms shows strong familiarity with partial sorting problems.
Approach 1: Sort and Select
This approach leverages the simplicity of sorting the list of points based on their distance from the origin. After sorting, the first k points will be the closest ones. The key is to use the squared Euclidean distance to avoid the computational overhead of square root operations.
from typing import List

def kClosest(points: List[List[int]], k: int) -> List[List[int]]:
    points.sort(key=lambda x: x[0]**2 + x[1]**2)
return points[:k]import java.util.Arrays;
class Solution {
public int[][] kClosest(int[][] points, int k) {
Arrays.sort(points, (a, b) -> (a[0] * a[0] + a[1] * a[1]) - (b[0] * b[0] + b[1] * b[1]));
return Arrays.copyOfRange(points, 0, k);
}
}#include <vector>
#include <algorithm>
using namespace std;
vector<vector<int>> kClosest(vector<vector<int>>& points, int k) {
sort(points.begin(), points.end(), [](vector<int>& a, vector<int>& b) {
return a[0] * a[0] + a[1] * a[1] < b[0] * b[0] + b[1] * b[1];
});
return vector<vector<int>>(points.begin(), points.begin() + k);
}var kClosest = function(points, k) {
points.sort((a, b) => (a[0]**2 + a[1]**2) - (b[0]**2 + b[1]**2));
return points.slice(0, k);
};#include <stdio.h>
#include <stdlib.h>
int compare(const void *a, const void *b) {
int *pointA = *(int **)a;
int *pointB = *(int **)b;
int distA = pointA[0] * pointA[0] + pointA[1] * pointA[1];
int distB = pointB[0] * pointB[0] + pointB[1] * pointB[1];
return distA - distB;
}
int** kClosest(int** points, int pointsSize, int* pointsColSize, int k, int* returnSize, int** returnColumnSizes) {
qsort(points, pointsSize, sizeof(int*), compare);
*returnSize = k;
*returnColumnSizes = (int *)malloc(sizeof(int) * k);
for (int i = 0; i < k; i++) {
(*returnColumnSizes)[i] = 2;
}
return points;
}using System;
using System.Linq;
public class Solution {
public int[][] KClosest(int[][] points, int k) {
return points.OrderBy(point => point[0] * point[0] + point[1] * point[1]).Take(k).ToArray();
}
}This Python solution uses the sort() function with a key that computes squared distances. The first k elements post-sort are returned.
Time Complexity: O(n log n) due to sorting.
Space Complexity: O(k) for the output list.
Approach 2: Max-Heap (Priority Queue)
The Max-Heap approach uses a priority queue to maintain the k closest points seen so far. By using a max-heap, we can efficiently insert new points and potentially evict the farthest point if it is further than any encountered point, leading to a reduced time complexity for finding the k closest points.
import heapq
from typing import List

def kClosest(points: List[List[int]], k: int) -> List[List[int]]:
    maxHeap = []
    for (x, y) in points:
        distSq = x**2 + y**2
        heapq.heappush(maxHeap, (-distSq, x, y))
        if len(maxHeap) > k:
            heapq.heappop(maxHeap)
return [(x, y) for (_, x, y) in maxHeap]import java.util.PriorityQueue;
class Solution {
public int[][] kClosest(int[][] points, int k) {
PriorityQueue<int[]> maxHeap = new PriorityQueue<>((a, b) -> b[0] - a[0]);
for (int[] p : points) {
int distSq = p[0] * p[0] + p[1] * p[1];
maxHeap.offer(new int[]{distSq, p[0], p[1]});
if (maxHeap.size() > k) {
maxHeap.poll();
}
}
int[][] result = new int[k][2];
for (int i = 0; i < k; i++) {
int[] entry = maxHeap.poll();
result[i] = new int[]{entry[1], entry[2]};
}
return result;
}
}#include <vector>
#include <queue>
#include <cmath>
using namespace std;
typedef pair<int, vector<int>> pdvi;
vector<vector<int>> kClosest(vector<vector<int>>& points, int k) {
priority_queue<pdvi> maxHeap;
for (auto& p : points) {
int dist = p[0] * p[0] + p[1] * p[1];
maxHeap.push({dist, p});
if (maxHeap.size() > k) {
maxHeap.pop();
}
}
vector<vector<int>> result;
while (!maxHeap.empty()) {
result.push_back(maxHeap.top().second);
maxHeap.pop();
}
return result;
}var kClosest = function(points, k) {
let maxHeap = new MinPriorityQueue({
compare: (a, b) => b.dist - a.dist
});
for (let [x, y] of points) {
let distSq = x**2 + y**2;
maxHeap.enqueue({dist: distSq, point: [x, y]});
if (maxHeap.size() > k) {
maxHeap.dequeue();
}
}
return maxHeap.toArray().map(entry => entry.element.point);
};#include <stdio.h>
#include <stdlib.h>
#include <limits.h>
typedef struct {
int dist;
int point[2];
} Point;
int compare(const void *a, const void *b) {
return (*(Point *)b).dist - (*(Point *)a).dist; // Max-Heap on distance
}
void adjustHeap(Point *heap, int size, int i) {
int largest = i;
int left = 2 * i + 1;
int right = 2 * i + 2;
if (left < size && heap[left].dist > heap[largest].dist) largest = left;
if (right < size && heap[right].dist > heap[largest].dist) largest = right;
if (largest != i) {
Point tmp = heap[i];
heap[i] = heap[largest];
heap[largest] = tmp;
adjustHeap(heap, size, largest);
}
}
Point extractMax(Point *heap, int *size) {
if (*size <= 0) return (Point) { .dist = INT_MIN };
Point root = heap[0];
if (*size > 1) {
heap[0] = heap[*size - 1];
adjustHeap(heap, *size, 0);
}
(*size)--;
return root;
}
void insertHeap(Point *heap, int *size, Point newPoint) {
int i = (*size)++;
heap[i] = newPoint;
while (i != 0 && heap[i].dist > heap[(i - 1) / 2].dist) {
Point tmp = heap[i];
heap[i] = heap[(i - 1) / 2];
heap[(i - 1) / 2] = tmp;
i = (i - 1) / 2;
}
}
int** kClosest(int** points, int pointsSize, int* pointsColSize, int k, int* returnSize, int** returnColumnSizes) {
Point *heap = (Point *)malloc(sizeof(Point) * k);
int heapSize = 0;
for (int i = 0; i < pointsSize; i++) {
int distSq = points[i][0] * points[i][0] + points[i][1] * points[i][1];
Point point = { .dist = distSq, .point = { points[i][0], points[i][1] } };
if (heapSize < k) {
insertHeap(heap, &heapSize, point);
} else if (point.dist < heap[0].dist) {
extractMax(heap, &heapSize);
insertHeap(heap, &heapSize, point);
}
}
int** result = (int **)malloc(sizeof(int *) * k);
*returnColumnSizes = (int *)malloc(sizeof(int) * k);
for (int i = 0; i < k; i++) {
result[i] = (int *)malloc(sizeof(int) * 2);
result[i][0] = heap[i].point[0];
result[i][1] = heap[i].point[1];
(*returnColumnSizes)[i] = 2;
}
*returnSize = k;
free(heap);
return result;
}using System;
using System.Collections.Generic;
public class Solution {
public int[][] KClosest(int[][] points, int k) {
PriorityQueue<int[], int> maxHeap = new PriorityQueue<int[], int>(Comparer<int>.Create((a, b) => b - a));
foreach (var point in points) {
int distSq = point[0] * point[0] + point[1] * point[1];
maxHeap.Enqueue(new int[]{point[0], point[1]}, distSq);
if (maxHeap.Count > k) {
maxHeap.Dequeue();
}
}
var result = new List<int[]>();
while (maxHeap.Count > 0) {
result.Add(maxHeap.Dequeue());
}
return result.ToArray();
}
}The Python solution uses a max-heap (mimicked using a min-heap with negative distances) via heapq to efficiently maintain the set of k closest points to the origin.
Time Complexity: O(n log k) for heap operations.
Space Complexity: O(k) for the heap.
Approach 3: Custom Sorting
We sort all points by their distance from the origin in ascending order, and then take the first k points.
The time complexity is O(n log n), and the space complexity is O(log n). Here, n is the length of the array points.
function kClosest(points: number[][], k: number): number[][] {
    points.sort((a, b) => Math.hypot(a[0], a[1]) - Math.hypot(b[0], b[1]));
    return points.slice(0, k);
}func kClosest(points [][]int, k int) [][]int {
sort.Slice(points, func(i, j int) bool {
return math.Hypot(float64(points[i][0]), float64(points[i][1])) < math.Hypot(float64(points[j][0]), float64(points[j][1]))
})
return points[:k]
}impl Solution {
pub fn k_closest(mut points: Vec<Vec<i32>>, k: i32) -> Vec<Vec<i32>> {
points.sort_by(|a, b| {
let dist_a = f64::hypot(a[0] as f64, a[1] as f64);
let dist_b = f64::hypot(b[0] as f64, b[1] as f64);
dist_a.partial_cmp(&dist_b).unwrap()
});
points.into_iter().take(k as usize).collect()
}
}Approach 4: Priority Queue (Max Heap)
We can use a priority queue (max heap) to maintain the k closest points to the origin.
The time complexity is O(n times log k), and the space complexity is O(k). Here, n is the length of the array points.
function kClosest(points: number[][], k: number): number[][] {
    const maxQ = new MaxPriorityQueue<{ point: number[]; dist: number }>(entry => entry.dist);
    for (const [x, y] of points) {
        const dist = x * x + y * y;
        maxQ.enqueue({ point: [x, y], dist });
        if (maxQ.size() > k) {
            maxQ.dequeue();
        }
    }
    return maxQ.toArray().map(entry => entry.point);
}func kClosest(points [][]int, k int) [][]int {
maxQ := hp{}
for i, p := range points {
dist := math.Hypot(float64(p[0]), float64(p[1]))
heap.Push(&maxQ, pair{dist, i})
if len(maxQ) > k {
heap.Pop(&maxQ)
}
}
ans := make([][]int, k)
for i, p := range maxQ {
ans[i] = points[p.i]
}
return ans
}
type pair struct {
dist float64
i int
}
type hp []pair
func (h hp) Len() int { return len(h) }
func (h hp) Less(i, j int) bool {
a, b := h[i], h[j]
return a.dist > b.dist
}
func (h hp) Swap(i, j int) { h[i], h[j] = h[j], h[i] }
func (h *hp) Push(v any) { *h = append(*h, v.(pair)) }
func (h *hp) Pop() any { a := *h; v := a[len(a)-1]; *h = a[:len(a)-1]; return v }Approach 5: Binary Search
We notice that as the distance increases, the number of points increases as well. There exists a critical value such that the number of points before this value is less than or equal to k, and the number of points after this value is greater than k.
Therefore, we can use binary search to enumerate the distance. In each binary search iteration, we count the number of points whose distance is less than or equal to the current distance. If the count is greater than or equal to k, it indicates that the critical value is on the left side, so we set the right boundary equal to the current distance; otherwise, the critical value is on the right side, so we set the left boundary equal to the current distance plus one.
After the binary search is finished, we just need to return the points whose distance is less than or equal to the left boundary.
The time complexity is O(n times log M), and the space complexity is O(n). Here, n is the length of the array points, and M is the maximum value of the distance.
function kClosest(points: number[][], k: number): number[][] {
    const dist = points.map(([x, y]) => x * x + y * y);
    let [l, r] = [0, Math.max(...dist)];
    while (l < r) {
        const mid = (l + r) >> 1;
        let cnt = 0;
        for (const d of dist) {
            if (d <= mid) {
                ++cnt;
            }
        }
        if (cnt >= k) {
            r = mid;
        } else {
            l = mid + 1;
        }
    }
    return points.filter((_, i) => dist[i] <= l);
}func kClosest(points [][]int, k int) (ans [][]int) {
n := len(points)
dist := make([]int, n)
l, r := 0, 0
for i, p := range points {
dist[i] = p[0]*p[0] + p[1]*p[1]
r = max(r, dist[i])
}
for l < r {
mid := (l + r) >> 1
cnt := 0
for _, d := range dist {
if d <= mid {
cnt++
}
}
if cnt >= k {
r = mid
} else {
l = mid + 1
}
}
for i, p := range points {
if dist[i] <= l {
ans = append(ans, p)
}
}
return
}Complexity comparison
| Approach | Complexity |
|---|---|
| Sort and Select | Time Complexity: O(n log n) due to sorting. |
| Max-Heap (Priority Queue) | Time Complexity: O(n log k) for heap operations. |
| Custom Sorting | – |
| Priority Queue (Max Heap) | – |
| Binary Search | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Sort and Select | O(n log n) | O(1)–O(n) | Simple implementation when constraints are small or readability matters more than optimal performance |
| Max-Heap (Priority Queue) | O(n log k) | O(k) | Best practical approach when k is much smaller than n or when processing elements incrementally |
| Quickselect | Average O(n), Worst O(n^2) | O(1) | Optimal selection algorithm when you only need the k smallest elements without full sorting |
Frequently asked questions
Is K Closest Points to Origin easy or hard?
K Closest Points to Origin is typically rated Medium difficulty. The basic idea of comparing squared distances is straightforward, but the challenge is choosing the right algorithm. Interviewers often expect candidates to move beyond sorting and discuss heap or Quickselect optimizations.
How to solve K Closest Points to Origin in O(n)?
Use the Quickselect algorithm. Compute squared distances and apply a partition step similar to quicksort so points with smaller distances move left of the pivot. Recursively process only the side containing the k-th element. Once the pivot index reaches k, the first k elements represent the closest points in average O(n) time.
What is the best approach for K Closest Points to Origin?
Quickselect is the optimal algorithm with average O(n) time because it partially partitions the array until the k closest points are placed in the first k positions. In practice, many engineers prefer a max-heap solution with O(n log k) complexity because it is easier to implement and performs well when k is much smaller than n.
What data structure is used in K Closest Points to Origin?
The most common data structure is a max-heap (priority queue) that stores the k closest points seen so far. Each heap entry tracks the squared distance and the point itself. Quickselect solutions instead rely on array partitioning rather than an additional data structure.
What is the time complexity of K Closest Points to Origin?
The complexity depends on the approach used. Sorting all points takes O(n log n). Using a max-heap of size k takes O(n log k). Quickselect improves this to average O(n) time because it avoids sorting the entire array and only partitions around the k-th smallest distance.
K Closest Points to Origin Python or Java solution approach?
Python and Java solutions usually compute squared distances and either sort the array or maintain a max-heap of size k. Python often uses heapq while Java uses PriorityQueue with a custom comparator. Both implementations achieve O(n log k) time with O(k) extra space using the heap method.
Is K Closest Points to Origin asked at Google, Amazon, or Meta?
K Closest Points to Origin frequently appears in interviews at companies such as Amazon, Google, and Meta. It tests knowledge of heaps, partition-based selection, and distance calculations on geometric points. Interviewers often expect candidates to discuss both heap and Quickselect approaches.