Falling Squares solution and explanation

5 more videos on this problem
 花花酱 LeetCode 699. Falling Squares - 刷题找工作 EP97Hua Hua · 20:34 · 4K views
 699. Falling Squares (Leetcode Hard)Programming Live with Larry · 19:53 · 1K views
 Falling Squares Leetcode 699 (Developing Intuition)Egreat Tech · 33:18 · 635 views
 Leetcode 0699. Falling SquaresFearless Learner · 33:32 · 191 views
 LeetCode 699: Falling SquaresAlitaCode · 26:25 · 85 views
 No Sound Leetcode 699: Falling SquaresExtremeProgrammer · 1:41 · 45 views
The problem
There are several squares being dropped onto the X-axis of a 2D plane.
You are given a 2D integer array positions where positions[i] = [lefti, sideLengthi] represents the ith square with a side length of sideLengthi that is dropped with its left edge aligned with X-coordinate lefti.
Each square is dropped one at a time from a height above any landed squares. It then falls downward (negative Y direction) until it either lands on the top side of another square or on the X-axis. A square brushing the left/right side of another square does not count as landing on it. Once it lands, it freezes in place and cannot be moved.
After each square is dropped, you must record the height of the current tallest stack of squares.
Return an integer array ans where ans[i] represents the height described above after dropping the ith square.
Example 1:
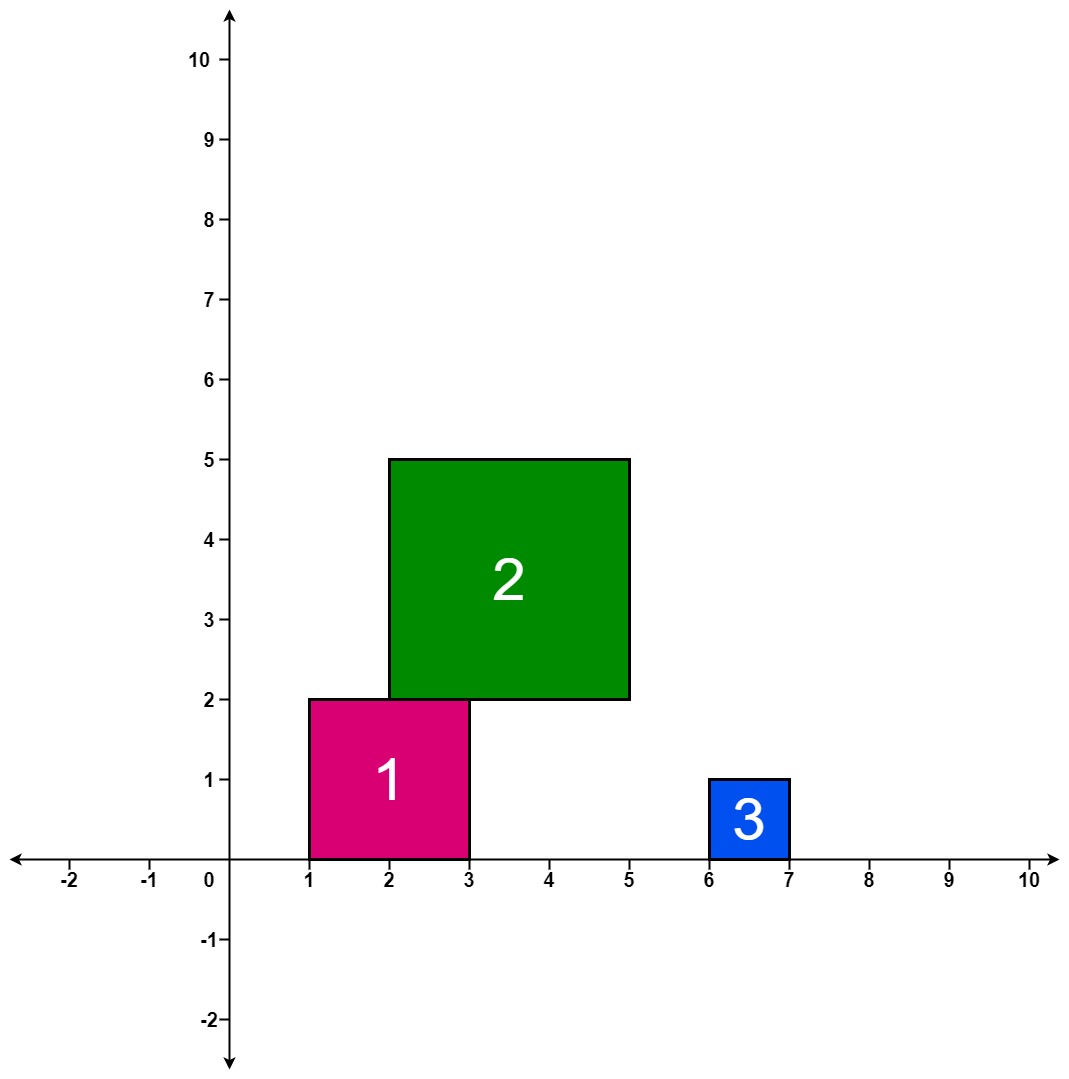
Input: positions = [[1,2],[2,3],[6,1]]
Output: [2,5,5]
Explanation:
After the first drop, the tallest stack is square 1 with a height of 2.
After the second drop, the tallest stack is squares 1 and 2 with a height of 5.
After the third drop, the tallest stack is still squares 1 and 2 with a height of 5.
Thus, we return an answer of [2, 5, 5].
Example 2:
Input: positions = [[100,100],[200,100]]
Output: [100,100]
Explanation:
After the first drop, the tallest stack is square 1 with a height of 100.
After the second drop, the tallest stack is either square 1 or square 2, both with heights of 100.
Thus, we return an answer of [100, 100].
Note that square 2 only brushes the right side of square 1, which does not count as landing on it.
Constraints:
1 <= positions.length <= 10001 <= lefti <= 1081 <= sideLengthi <= 106
Approach overview
Problem Overview: You drop squares onto a 1D number line. Each square lands on the highest structure it overlaps with, stacking vertically. After every drop, return the maximum height of the stacked structure so far.
Approach 1: Brute Force Simulation (O(n²) time, O(n) space)
Track previously placed squares and simulate each new drop. For the current square [left, size], compute its interval [left, left + size). Iterate through all earlier squares and check for interval overlap. If two intervals intersect, update the landing height using the maximum height among overlapping squares. Store the resulting height and update the running global maximum. This approach uses simple array iteration and works well for small inputs but becomes slow as the number of squares grows.
Approach 2: Using Segment Tree with Coordinate Compression (O(n log n) time, O(n) space)
Map all square boundaries to compressed coordinates and maintain heights using a segment tree. For each square, query the maximum height in its interval and place the new square on top of that height. Then update the segment tree range with the new height value. The segment tree supports fast range maximum queries and updates in O(log n), which keeps the total complexity manageable even for large inputs.
Approach 3: Hash Map Based Height Tracking (O(n²) time, O(n) space)
Instead of a structured tree, store interval heights in a hash map keyed by square index or coordinate ranges. For each new square, scan existing entries and compute overlaps to determine the highest supporting base. Update the hash map with the resulting height and track the global maximum. This method trades structured queries for simpler implementation but still requires checking overlaps against many previously stored intervals.
Approach 4: Sorting Intervals by Position (O(n²) time, O(n) space)
Sort squares by their left coordinate and process them sequentially. Maintain a list of placed intervals and compare each new square against earlier ones that may overlap in the sorted order. Sorting reduces unnecessary comparisons for non-overlapping regions, but worst‑case complexity remains quadratic because overlapping intervals still require repeated checks. This approach helps build intuition before moving to tree-based structures or an ordered set.
Recommended for interviews: The segment tree approach is the expected optimal solution. Interviewers want to see that you recognize the repeated range maximum query pattern and apply coordinate compression with a segment tree. Starting with the brute force simulation shows understanding of the stacking mechanics, but the optimized range-query solution demonstrates stronger algorithmic design.
Approach 1: Brute Force Simulation
This approach involves simulating the falling of each square by considering where each newly falling square intersects with squares that have already been dropped. We track the maximum heights over ranges and update them accordingly.
We use an array to maintain the maximum height for each position on the x-axis covered by the squares. For each square, we determine its position range on the x-axis, evaluate the highest point it will land on, update the height range, and then calculate the tallest height by comparing it to all other known heights.
def fallingSquares(positions):
    heights = []
    for left, size in positions:
        right = left + size
        base_height = 0
        for l, s, h in heights:
            if l < right and left < l + s:  # overlap
                base_height = max(base_height, h)
        current_height = base_height + size
        heights.append((left, size, current_height))
    return [max(heights[i][2] for i in range(j+1)) for j in range(len(positions))]
This solution defines a function fallingSquares that takes positions as input. For each square, it calculates the position, checks for overlaps with previously dropped squares, determines where it will land, updates the height, and maintains a list of tuples that record left position, size, and current height. The heights are calculated cumulatively, and the results are generated by iterating through the list of positions.
Time Complexity: O(n^2), where n is the number of positions, due to checking each new square against all previous squares.
Space Complexity: O(n), for storing heights.
Approach 2: Using Segment Tree
This approach optimizes the brute force simulation by utilizing a segment tree to efficiently manage and query intervals. The segment tree helps update and retrieve maximum heights for given x-ranges effectively.
We map the positions along the X-axis to a discrete set, construct a segment tree to cover those discrete positions, and then for each new square, we update the segment tree with the height of the square added to the current maximum height for its X-range. This is performed in logarithmic time due to the properties of the segment tree, enabling us to handle large input sizes more rapidly.
import java.util.*;

class Solution {
    public List<Integer> fallingSquares(int[][] positions) {
        Set<Integer> coords = new HashSet<>();
        for (int[] pos : positions) {
            coords.add(pos[0]);
            coords.add(pos[0] + pos[1] - 1);
        }
        Integer[] sortedCoords = coords.toArray(new Integer[0]);
        Arrays.sort(sortedCoords);
        Map<Integer, Integer> index = new HashMap<>();
        for (int i = 0; i < sortedCoords.length; i++) index.put(sortedCoords[i], i);

        int[] heights = new int[2 * coords.size()];
        int h = 0;
        List<Integer> ans = new ArrayList<>();

        for (int[] pos : positions) {
            int left = index.get(pos[0]), right = index.get(pos[0] + pos[1] - 1);
            int currentHeight = rangeQuery(heights, left, right, 0, 0, coords.size() - 1) + pos[1];
            h = Math.max(h, currentHeight);
            rangeUpdate(heights, left, right, 0, 0, coords.size() - 1, currentHeight);
            ans.add(h);
        }
        return ans;
    }

    private int rangeQuery(int[] st, int ql, int qr, int pos, int l, int r) {
        if (ql <= l && r <= qr) return st[pos];
        if (qr < l || r < ql) return 0;
        int mid = (l + r) / 2;
        return Math.max(
            rangeQuery(st, ql, qr, 2 * pos + 1, l, mid),
            rangeQuery(st, ql, qr, 2 * pos + 2, mid + 1, r)
        );
    }

    private void rangeUpdate(int[] st, int ul, int ur, int pos, int l, int r, int newHeight) {
        if (ul <= l && r <= ur) {
            st[pos] = Math.max(st[pos], newHeight);
            return;
        }
        if (ur < l || r < ul) return;
        int mid = (l + r) / 2;
        rangeUpdate(st, ul, ur, 2 * pos + 1, l, mid, newHeight);
        rangeUpdate(st, ul, ur, 2 * pos + 2, mid + 1, r, newHeight);
    }
}
This Java solution uses a segment tree to accomplish efficient range maximum queries and updates. The fallingSquares function first discretizes the x-coordinates for better management, then it processes each square's x-range to find the current maximum height via rangeQuery and updates this range using rangeUpdate. This allows determination of the highest structure after each square drops, maintaining optimal time complexity due to the segment tree structure.
Time Complexity: O(n log n), due to the logarithmic operations with the segment tree.
Space Complexity: O(n), for storing distinct coordinates and segment tree data structures.
Approach 3: Approach 1: Use a Hash Map for Frequency Counting
This approach involves using a hash map (or dictionary) to count the frequency of elements in the array. This will help us to easily keep track of the occurrences of each element, allowing us to efficiently determine if duplicates are present.
def contains_duplicate(nums):
    num_set = set()
    for num in nums:
        if num in num_set:
            return True
        num_set.add(num)
    return False

nums = [1, 2, 3, 4]
print(contains_duplicate(nums))import java.util.HashSet;
public class Solution {
public boolean containsDuplicate(int[] nums) {
HashSet<Integer> set = new HashSet<>();
for (int num : nums) {
if (set.contains(num)) {
return true;
}
set.add(num);
}
return false;
}
public static void main(String[] args) {
Solution solution = new Solution();
int[] nums = {1, 2, 3, 4};
System.out.println(solution.containsDuplicate(nums));
}
}#include <iostream>
#include <unordered_map>
#include <vector>
bool containsDuplicate(std::vector<int>& nums) {
std::unordered_map<int, bool> numMap;
for (int num : nums) {
if (numMap.find(num) != numMap.end()) {
return true;
}
numMap[num] = true;
}
return false;
}
int main() {
std::vector<int> nums = {1, 2, 3, 4};
std::cout << containsDuplicate(nums) << std::endl;
return 0;
}function containsDuplicate(nums) {
const numSet = new Set();
for (let num of nums) {
if (numSet.has(num)) {
return true;
}
numSet.add(num);
}
return false;
}
const nums = [1, 2, 3, 4];
console.log(containsDuplicate(nums));#include <stdio.h>
#include <stdlib.h>
#define HASH_SIZE 1000
int containsDuplicate(int* nums, int numsSize) {
int hashTable[HASH_SIZE] = {0};
for (int i = 0; i < numsSize; i++) {
int index = abs(nums[i]) % HASH_SIZE;
if (hashTable[index] != 0) {
return 1;
}
hashTable[index] = 1;
}
return 0;
}
int main() {
int nums[] = {1, 2, 3, 4};
int numsSize = sizeof(nums) / sizeof(nums[0]);
printf("%d\n", containsDuplicate(nums, numsSize));
return 0;
}using System;
using System.Collections.Generic;
class Solution {
public bool ContainsDuplicate(int[] nums) {
HashSet<int> set = new HashSet<int>();
foreach (int num in nums) {
if (set.Contains(num)) {
return true;
}
set.Add(num);
}
return false;
}
static void Main(string[] args) {
Solution solution = new Solution();
int[] nums = new int[] { 1, 2, 3, 4 };
Console.WriteLine(solution.ContainsDuplicate(nums));
}
}Using a set to store the numbers as we iterate. If we encounter a number already in the set, we identify it as a duplicate.
Time Complexity: O(n), Space Complexity: O(n)
Approach 4: Approach 2: Sorting the Array
In this approach, we first sort the array. Then we check consecutive elements. If two consecutive elements are the same, then there is a duplicate in the array.
def contains_duplicate(nums):
    nums.sort()
    for i in range(len(nums) - 1):
        if nums[i] == nums[i + 1]:
            return True
    return False

nums = [1, 2, 3, 1]
print(contains_duplicate(nums))import java.util.Arrays;
public class Solution {
public boolean containsDuplicate(int[] nums) {
Arrays.sort(nums);
for (int i = 0; i < nums.length - 1; i++) {
if (nums[i] == nums[i + 1]) {
return true;
}
}
return false;
}
public static void main(String[] args) {
Solution solution = new Solution();
int[] nums = {1, 2, 3, 1};
System.out.println(solution.containsDuplicate(nums));
}
}#include <iostream>
#include <vector>
#include <algorithm>
bool containsDuplicate(std::vector<int>& nums) {
std::sort(nums.begin(), nums.end());
for (size_t i = 0; i < nums.size() - 1; ++i) {
if (nums[i] == nums[i + 1]) {
return true;
}
}
return false;
}
int main() {
std::vector<int> nums = {1, 2, 3, 1};
std::cout << containsDuplicate(nums) << std::endl;
return 0;
}function containsDuplicate(nums) {
nums.sort((a, b) => a - b);
for (let i = 0; i < nums.length - 1; i++) {
if (nums[i] === nums[i + 1]) {
return true;
}
}
return false;
}
const nums = [1, 2, 3, 1];
console.log(containsDuplicate(nums));#include <stdio.h>
#include <stdlib.h>
int compare(const void* a, const void* b) {
return (*(int*)a - *(int*)b);
}
int containsDuplicate(int* nums, int numsSize) {
qsort(nums, numsSize, sizeof(int), compare);
for (int i = 0; i < numsSize - 1; i++) {
if (nums[i] == nums[i + 1]) {
return 1;
}
}
return 0;
}
int main() {
int nums[] = {1, 2, 3, 1};
int numsSize = sizeof(nums) / sizeof(nums[0]);
printf("%d\n", containsDuplicate(nums, numsSize));
return 0;
}using System;
class Solution {
public bool ContainsDuplicate(int[] nums) {
Array.Sort(nums);
for (int i = 0; i < nums.Length - 1; i++) {
if (nums[i] == nums[i + 1]) {
return true;
}
}
return false;
}
static void Main(string[] args) {
Solution solution = new Solution();
int[] nums = { 1, 2, 3, 1 };
Console.WriteLine(solution.ContainsDuplicate(nums));
}
}Sorting the list allows us to find duplicates by comparing each element to the next. If two adjacent elements are identical, a duplicate is present.
Time Complexity: O(n log n), Space Complexity: O(1)
Approach 5: Segment Tree
According to the problem description, we need to maintain a set of intervals that support modification and query operations. In this case, we can use a segment tree to solve the problem.
A segment tree divides the entire interval into multiple non-contiguous sub-intervals, with the number of sub-intervals not exceeding log(width), where width is the length of the interval. To update the value of an element, we only need to update log(width) intervals, and these intervals are all contained within a larger interval that includes the element. When modifying intervals, we need to use lazy propagation to ensure efficiency.
- Each node of the segment tree represents an interval;
- The segment tree has a unique root node representing the entire statistical range, such as
[1, n]; - Each leaf node of the segment tree represents a primitive interval of length 1,
[x, x]; - For each internal node
[l, r], its left child is[l, mid], and its right child is[mid + 1, r], wheremid = \frac{l + r}{2};
For this problem, the information maintained by the segment tree nodes includes:
- The maximum height
vof the blocks in the interval - Lazy propagation marker
add
Additionally, since the range of the number line is very large, up to 10^8, we use dynamic node creation.
In terms of time complexity, each query and modification has a time complexity of O(log n), and the total time complexity is O(n log n). The space complexity is O(n).
class Node {
    left: Node | null = null;
    right: Node | null = null;
    l: number;
    r: number;
    mid: number;
    v: number = 0;
    add: number = 0;

    constructor(l: number, r: number) {
        this.l = l;
        this.r = r;
        this.mid = (l + r) >> 1;
    }
}

class SegmentTree {
    private root: Node = new Node(1, 1e9);

    public modify(l: number, r: number, v: number): void {
        this.modifyNode(l, r, v, this.root);
    }

    private modifyNode(l: number, r: number, v: number, node: Node): void {
        if (l > r) {
            return;
        }
        if (node.l >= l && node.r <= r) {
            node.v = v;
            node.add = v;
            return;
        }
        this.pushdown(node);
        if (l <= node.mid) {
            this.modifyNode(l, r, v, node.left!);
        }
        if (r > node.mid) {
            this.modifyNode(l, r, v, node.right!);
        }
        this.pushup(node);
    }

    public query(l: number, r: number): number {
        return this.queryNode(l, r, this.root);
    }

    private queryNode(l: number, r: number, node: Node): number {
        if (l > r) {
            return 0;
        }
        if (node.l >= l && node.r <= r) {
            return node.v;
        }
        this.pushdown(node);
        let v = 0;
        if (l <= node.mid) {
            v = Math.max(v, this.queryNode(l, r, node.left!));
        }
        if (r > node.mid) {
            v = Math.max(v, this.queryNode(l, r, node.right!));
        }
        return v;
    }

    private pushup(node: Node): void {
        node.v = Math.max(node.left!.v, node.right!.v);
    }

    private pushdown(node: Node): void {
        if (node.left == null) {
            node.left = new Node(node.l, node.mid);
        }
        if (node.right == null) {
            node.right = new Node(node.mid + 1, node.r);
        }
        if (node.add != 0) {
            let left = node.left,
                right = node.right;
            left!.add = node.add;
            right!.add = node.add;
            left!.v = node.add;
            right!.v = node.add;
            node.add = 0;
        }
    }
}

function fallingSquares(positions: number[][]): number[] {
    const ans: number[] = [];
    const tree = new SegmentTree();
    let mx = 0;
    for (const [l, w] of positions) {
        const r = l + w - 1;
        const h = tree.query(l, r) + w;
        mx = Math.max(mx, h);
        ans.push(mx);
        tree.modify(l, r, h);
    }
    return ans;
}type node struct {
left *node
right *node
l, mid, r int
v, add int
}
func newNode(l, r int) *node {
return &node{
l: l,
r: r,
mid: (l + r) >> 1,
}
}
type segmentTree struct {
root *node
}
func newSegmentTree() *segmentTree {
return &segmentTree{
root: newNode(1, 1e9),
}
}
func (t *segmentTree) modify(l, r, v int, n *node) {
if l > r {
return
}
if n.l >= l && n.r <= r {
n.v = v
n.add = v
return
}
t.pushdown(n)
if l <= n.mid {
t.modify(l, r, v, n.left)
}
if r > n.mid {
t.modify(l, r, v, n.right)
}
t.pushup(n)
}
func (t *segmentTree) query(l, r int, n *node) int {
if l > r {
return 0
}
if n.l >= l && n.r <= r {
return n.v
}
t.pushdown(n)
v := 0
if l <= n.mid {
v = max(v, t.query(l, r, n.left))
}
if r > n.mid {
v = max(v, t.query(l, r, n.right))
}
return v
}
func (t *segmentTree) pushup(n *node) {
n.v = max(n.left.v, n.right.v)
}
func (t *segmentTree) pushdown(n *node) {
if n.left == nil {
n.left = newNode(n.l, n.mid)
}
if n.right == nil {
n.right = newNode(n.mid+1, n.r)
}
if n.add != 0 {
n.left.add = n.add
n.right.add = n.add
n.left.v = n.add
n.right.v = n.add
n.add = 0
}
}
func fallingSquares(positions [][]int) []int {
ans := make([]int, len(positions))
t := newSegmentTree()
mx := 0
for i, p := range positions {
l, w, r := p[0], p[1], p[0]+p[1]-1
h := t.query(l, r, t.root) + w
mx = max(mx, h)
ans[i] = mx
t.modify(l, r, h, t.root)
}
return ans
}Complexity comparison
| Approach | Complexity |
|---|---|
| Brute Force Simulation | Time Complexity: O(n^2), where n is the number of positions, due to checking each new square against all previous squares. |
| Using Segment Tree | Time Complexity: O(n log n), due to the logarithmic operations with the segment tree. |
| Approach 1: Use a Hash Map for Frequency Counting | Time Complexity: O(n), Space Complexity: O(n) |
| Approach 2: Sorting the Array | Time Complexity: O(n log n), Space Complexity: O(1) |
| Segment Tree | – |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Brute Force Simulation | O(n²) | O(n) | Small inputs or when first understanding the stacking logic |
| Segment Tree with Coordinate Compression | O(n log n) | O(n) | General case with large input sizes and repeated range queries |
| Hash Map Height Tracking | O(n²) | O(n) | Simpler implementation when structured trees are unnecessary |
| Sorting Intervals | O(n²) | O(n) | When preprocessing by position helps reduce comparisons |
Frequently asked questions
Is Falling Squares easy or hard?
Falling Squares is classified as a hard problem because it combines interval overlap logic with advanced data structures like segment trees. Efficient solutions require recognizing the repeated range query pattern and optimizing beyond naive simulation.
How to solve Falling Squares in O(n log n)?
Compress all unique coordinates from square boundaries and build a segment tree over those indices. For each square, query the maximum height in its interval to determine where it lands. Update that interval with the new height and keep track of the global maximum after every drop.
What is the best approach for Falling Squares?
The optimal approach uses a segment tree with coordinate compression. Each square queries the maximum height in its interval and then updates that range with the new stacked height. This reduces repeated overlap checks and runs in O(n log n) time with O(n) space.
What data structure is used in Falling Squares?
The most common data structure is a segment tree combined with coordinate compression. Some implementations also use ordered maps or ordered sets to track intervals dynamically and query overlapping ranges efficiently.
What is the time complexity of Falling Squares?
The brute force simulation takes O(n²) time because every new square checks overlap against all previous squares. The optimized solution using a segment tree performs range maximum queries and updates in O(log n), leading to an overall O(n log n) time complexity.
Falling Squares Python or Java solution approach?
Python solutions often use brute force simulation for clarity or a coordinate-compressed segment tree for efficiency. Java implementations commonly use segment trees or TreeMap-based interval tracking to support fast range maximum queries.
Is Falling Squares asked at Google, Amazon, or Meta?
Falling Squares is a known hard interval and segment tree problem that appears in interviews at companies such as Google, Amazon, and Meta. It tests knowledge of range queries, coordinate compression, and efficient interval overlap handling.