Smallest K-Length Subsequence With Occurrences of a Letter solution and explanation

5 more videos on this problem
 LeetCode 2030. Smallest K-Length Subsequence With Occurrences of a LetterHappy Coding · 22:40 · 4K views
 2030. Smallest K-Length Subsequence With Occurrences of a Letter (Leetcode Hard)Programming Live with Larry · 32:24 · 813 views
 【每日一题】LeetCode 2030. Smallest K-Length Subsequence With Occurrences of a Letter 10/16/2021Huifeng Guan · 27:25 · 774 views
 leetCode hard vs ChatGPT - how to solve "Smallest K-Length Subsequence With Occurrences of a Letter"Jimmie Johnsson · 35:13 · 204 views
 LeetCode Hard: 2030. Smallest K-Length Subsequence With Occurrences of a Letterrobzingcod · 2:33:18 · 80 views
 LeetCode 2030: Smallest K-Length Subsequence With Occurrences of a LetterAlitaCode · 29:37 · 28 views
The problem
You are given a string s, an integer k, a letter letter, and an integer repetition.
Return the lexicographically smallest subsequence of s of length k that has the letter letter appear at least repetition times. The test cases are generated so that the letter appears in s at least repetition times.
A subsequence is a string that can be derived from another string by deleting some or no characters without changing the order of the remaining characters.
A string a is lexicographically smaller than a string b if in the first position where a and b differ, string a has a letter that appears earlier in the alphabet than the corresponding letter in b.
Example 1:
Input: s = "leet", k = 3, letter = "e", repetition = 1
Output: "eet"
Explanation: There are four subsequences of length 3 that have the letter 'e' appear at least 1 time:
- "lee" (from "leet")
- "let" (from "leet")
- "let" (from "leet")
- "eet" (from "leet")
The lexicographically smallest subsequence among them is "eet".
Example 2:
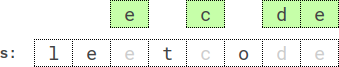
Input: s = "leetcode", k = 4, letter = "e", repetition = 2
Output: "ecde"
Explanation: "ecde" is the lexicographically smallest subsequence of length 4 that has the letter "e" appear at least 2 times.
Example 3:
Input: s = "bb", k = 2, letter = "b", repetition = 2
Output: "bb"
Explanation: "bb" is the only subsequence of length 2 that has the letter "b" appear at least 2 times.
Constraints:
1 <= repetition <= k <= s.length <= 5 * 104sconsists of lowercase English letters.letteris a lowercase English letter, and appears insat leastrepetitiontimes.
Approach overview
Problem Overview: Given a string s, you must build the lexicographically smallest subsequence of length k that contains at least repetition occurrences of a specific letter. You can remove characters but must preserve order. The challenge is balancing lexicographic minimality with the constraint that enough required letters remain.
Approach 1: Greedy Monotonic Stack (O(n) time, O(k) space)
This approach uses a monotonic stack to build the subsequence while scanning the string once. When processing each character, you try to maintain the smallest lexicographic order by popping larger characters from the stack if enough characters remain to still reach length k. At the same time, you must track how many required letter characters are still available in the remaining suffix and ensure the stack keeps enough of them to satisfy repetition. The algorithm keeps counters for remaining letters and required letters inside the stack, preventing pops that would make the constraint impossible to satisfy.
Greedy removal combined with the stack ordering ensures the resulting subsequence is minimal. Because each character is pushed and popped at most once, the runtime is linear. This pattern appears frequently in greedy string construction problems and is closely related to monotonic stack techniques used for lexicographically smallest subsequences.
Approach 2: Priority Queue (Min-Heap) Selection (O(n log n) time, O(n) space)
A more direct strategy uses a min-heap to always select the smallest possible next character within the valid index window. For each subsequence position, you consider the range of characters that still allows enough remaining positions to complete the subsequence and satisfy the required number of letter occurrences. The heap helps quickly pick the smallest candidate character. After selecting a character, you move the starting index forward and update how many required letters are still needed.
This approach mirrors the classic "smallest subsequence with constraints" strategy but relies on heap operations instead of a stack. It is easier to reason about window selection but costs O(log n) per insertion or extraction. The method is useful when implementing selection-based greedy logic or when practicing heap-driven solutions in string problems.
Recommended for interviews: The Greedy Monotonic Stack solution is what interviewers typically expect. It demonstrates control over lexicographic ordering, constraint tracking, and amortized stack operations. The heap solution shows correct reasoning but is less optimal. Explaining both signals strong problem-solving depth: brute reasoning about subsequences followed by an optimal greedy structure.
Approach 1: Greedy Stack Approach
The main idea of this approach is to use a stack to construct the subsequence while iterating over the string. You try to maintain a lexicographical order by always pushing the smallest possible character onto the stack. Restrictions are maintained by ensuring enough repetitions of the required letter remain possible, and the overall remaining length constraint is handled by potentially popping from the stack.
def smallestSubsequence(s: str, k: int, letter: str, repetition: int) -> str:
    stack = []
    letter_count = s.count(letter)
    for i, char in enumerate(s):
        while (stack and
               (len(stack) + len(s) - i > k) and
               (stack[-1] > char) and
               (stack[-1] != letter or letter_count > repetition)):
            if stack[-1] == letter:
                repetition += 1
            stack.pop()

        if len(stack) < k:
            if char == letter or k - len(stack) > repetition:
                if char == letter:
                    repetition -= 1
                stack.append(char)

        if char == letter:
            letter_count -= 1
return ''.join(stack)function smallestSubsequence(s, k, letter, repetition) {
let stack = [];
let letterCount = (s.split(letter).length - 1);
let remain = s.length;
for (let i = 0; i < s.length; i++) {
let char = s[i];
while (stack.length &&
stack.length + remain - i > k &&
stack[stack.length - 1] > char &&
(stack[stack.length - 1] != letter || letterCount > repetition)) {
if (stack.pop() == letter) repetition++;
}
if (stack.length < k) {
if (char == letter || k - stack.length > repetition) {
if (char == letter) repetition--;
stack.push(char);
}
}
if (char == letter) letterCount--;
}
return stack.join('');
}The function uses a stack-based approach to gradually build the smallest lexicographical subsequence of a desired length. In each iteration, character decisions rely on potential replacements that wouldn't violate sequence constraints, hence sometimes popping the stack. The solution takes care to always maintain clarity on meeting the required repetitions of the designated letter.
Time Complexity: O(n) because each character is processed no more than twice.
Space Complexity: O(k) for the stack.
Approach 2: Priority Queue (Min-Heap) Approach
A priority queue approach might be affected by overhead due to heap operations. However, conceptually, you enqueue characters while maintaining constraints, allowing an efficient rebuilding of potential subsequences based on priority. Managing repetitions and overall sequence constraints adds complexity.
import java.util.PriorityQueue;

public String smallestSubsequence(String s, int k, char letter, int repetition) {
    int[] letter_count = new int[s.length()];
    int lc = 0;
    for (int i = s.length() - 1; i >= 0; --i) {
        if (s.charAt(i) == letter) {
            lc++;
        }
        letter_count[i] = lc;
    }
    StringBuilder result = new StringBuilder();
    PriorityQueue<Character> pq = new PriorityQueue<>();
    int total_letter_count = 0;
    for (int i = 0; i < s.length(); ++i) {
        while (!pq.isEmpty() && result.length() + pq.size() - 1 + letter_count[i] >= k) {
            char top = pq.poll();
            result.append(top);
            total_letter_count += (top == letter ? 1 : 0);
        }
        if (result.length() < k) {
            pq.offer(s.charAt(i));
        }
    }
    return result.toString();
}#include <vector>
#include <queue>
#include <string>
using namespace std;
string smallestSubsequence(string s, int k, char letter, int repetition) {
vector<int> letter_count(s.size(), 0);
int lc = 0;
for (int i = s.size() - 1; i >= 0; --i) {
lc += (s[i] == letter);
letter_count[i] = lc;
}
string result;
priority_queue<char, vector<char>, greater<char>> pq;
int total_letter_count = 0, l_count = 0, start = 0;
for (int i = 0; i < s.size(); ++i) {
while (!pq.empty() && result.size() + pq.size() - 1 + letter_count[i] >= k) {
result += pq.top();
pq.pop();
total_letter_count += (result.back() == letter);
}
if (result.size() < k) {
pq.push(s[i]);
}
}
return result;
}The provided Java function builds the smallest subsequence with a priority queue approach, adding characters while checking conditions to meet length and repetition needs. Java's PriorityQueue aids efficient character handling toward this goal.
Time Complexity: O(n log n) because of priority queue operations in worse case.
Space Complexity: O(n) considering queue and string collective memory usage.
Complexity comparison
| Approach | Complexity |
|---|---|
| Greedy Stack Approach | Time Complexity: O(n) because each character is processed no more than twice. |
| Priority Queue (Min-Heap) Approach | Time Complexity: O(n log n) because of priority queue operations in worse case. |
Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Greedy Monotonic Stack | O(n) | O(k) | Best general solution when building lexicographically smallest subsequences with constraints |
| Priority Queue (Min-Heap) | O(n log n) | O(n) | Useful when selecting the smallest valid character from dynamic ranges |
Frequently asked questions
Is Smallest K-Length Subsequence With Occurrences of a Letter easy or hard?
LeetCode classifies this problem as Hard because it combines multiple constraints: subsequence length, lexicographic ordering, and a minimum occurrence requirement for a specific letter. The logic requires careful greedy decisions and precise bookkeeping of remaining characters.
Smallest K-Length Subsequence With Occurrences of a Letter Python/Java solution
Most implementations use a greedy stack pattern. Python and JavaScript solutions typically maintain a list as the stack and track remaining letter counts. C++ and Java implementations may use either the same stack logic or a priority queue approach depending on preference.
How to solve Smallest K-Length Subsequence With Occurrences of a Letter in O(n)?
Use a greedy monotonic stack while scanning the string. Maintain counts of how many required letters remain and how many are already in the stack. Pop characters if they make the sequence lexicographically larger and there are enough characters left to still build a length k subsequence with the required letter count.
What is the best approach for Smallest K-Length Subsequence With Occurrences of a Letter?
The optimal approach uses a greedy monotonic stack. While iterating through the string, larger characters are popped from the stack if a smaller character can produce a lexicographically smaller subsequence and enough characters remain to complete length k. Additional counters track how many required letters are still needed and how many remain in the suffix. This produces the answer in O(n) time and O(k) space.
Is Smallest K-Length Subsequence With Occurrences of a Letter asked at Google/Amazon/Meta?
Problems involving lexicographically smallest subsequences and monotonic stacks frequently appear in interviews at large tech companies such as Google, Amazon, and Meta. Variants of this problem test greedy reasoning, stack usage, and constraint tracking in string manipulation.
What data structure is used in Smallest K-Length Subsequence With Occurrences of a Letter?
The most common data structure used is a monotonic stack. It maintains the current subsequence while allowing efficient removal of larger characters when a smaller one appears. Some alternative implementations use a priority queue (min-heap) to select the next smallest valid character.
What is the time complexity of Smallest K-Length Subsequence With Occurrences of a Letter?
The optimal greedy stack solution runs in O(n) time because each character is pushed and popped from the stack at most once. Space complexity is O(k) for storing the resulting subsequence. A heap-based alternative takes O(n log n) time due to priority queue operations.