Remove Duplicates From an Unsorted Linked List solution and explanation

9 more videos on this problem
 Big Tech Coding Interview - Remove Duplicates from Unsorted Linked List - 1836AlgoJS · 4:49 · 2K views
 LeetCode Q 1836. Remove Duplicates From an Unsorted Linked ListSweet AI · 7:05 · 1K views
 1836. Remove Duplicates From an Unsorted Linked List (Leetcode Medium)Programming Live with Larry · 5:08 · 685 views
 Leetcode 1836. Remove Duplicates From an Unsorted Linked List - dict and linear traversalCode-Yao · 8:00 · 474 views
 1836. Remove Duplicates From an Unsorted Linked List - Week 2/5 Leetcode July ChallengeProgramming Live with Larry · 4:18 · 268 views
 LeetCode 1836 - Remove Duplicates From an Unsorted Linked List: A Microsoft JourneyThe Lofi Dev · 8:51 · 227 views
 1836 Remove Duplicates From an Unsorted Linked ListLeetcode and Interview Question · 7:25 · 218 views
 Leetcode Problem - Remove Duplicates From an Unsorted Linked ListShafik Quoraishee · 8:04 · 86 views
 Leetcode 1836. Remove Duplicates From an Unsorted Linked List (linked list)LetsCode · 4:16 · 37 views
 LeetCode 1836: Remove Duplicates From an Unsorted Linked ListAlitaCode · 27:22
The problem
Given the head of a linked list, find all the values that appear more than once in the list and delete the nodes that have any of those values.
Return the linked list after the deletions.
Example 1:
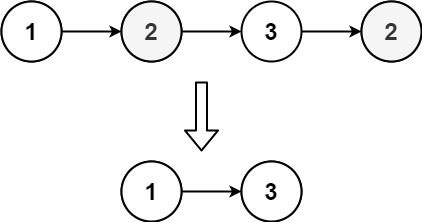
Input: head = [1,2,3,2]

Output: [1,3]

Explanation: 2 appears twice in the linked list, so all 2's should be deleted. After deleting all 2's, we are left with [1,3].
Example 2:
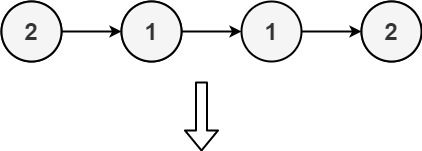
Input: head = [2,1,1,2]

Output: []

Explanation: 2 and 1 both appear twice. All the elements should be deleted.
Example 3:
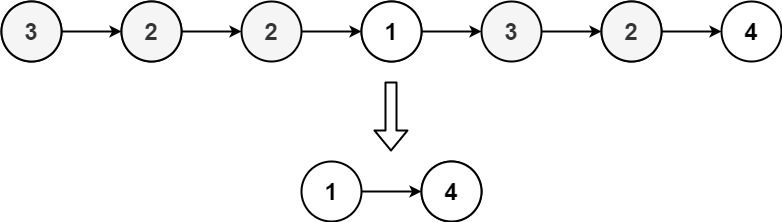
Input: head = [3,2,2,1,3,2,4]

Output: [1,4]

Explanation: 3 appears twice and 2 appears three times. After deleting all 3's and 2's, we are left with [1,4].
Constraints:
- The number of nodes in the list is in the range
[1, 105] 1 <= Node.val <= 105
Approach overview
Problem Overview: Given the head of an unsorted linked list, remove every node whose value appears more than once. Only values that occur exactly once should remain in the final list. The list is not sorted, so duplicates may appear anywhere in the structure.
Approach 1: Brute Force Comparison (O(n²) time, O(1) space)
The straightforward idea is to check every node against the rest of the list. For each node, iterate through the entire linked list and count how many times its value appears. If the count is greater than one, remove that node from the list using pointer manipulation. This approach requires two nested traversals of the list, leading to O(n²) time complexity. Space usage remains O(1) because no additional data structures are used. While inefficient for large lists, it demonstrates a solid understanding of linked list traversal and pointer updates.
Approach 2: Hash Table Frequency Counting (O(n) time, O(n) space)
The optimal solution uses a hash table to track how often each value appears. First pass: iterate through the list and store the frequency of every node value in a hash map. Each insertion or lookup in the map takes constant time on average, so the full pass costs O(n). Second pass: traverse the list again while maintaining a previous pointer. If the frequency of the current node’s value is greater than one, remove the node by updating prev.next. Otherwise, move the pointer forward.
This two-pass strategy cleanly separates counting from removal. The hash map allows constant-time frequency checks, eliminating the need for repeated scans. The total runtime becomes O(n), and the extra memory used by the map is O(n). This tradeoff is usually acceptable because the algorithm scales efficiently even for large lists.
Careful pointer handling is required when deleting nodes, especially near the head of the list. Many implementations use a dummy node before the head to simplify removal logic. The dummy node ensures that deleting the first real node does not require special-case handling.
Recommended for interviews: The hash table approach is what interviewers typically expect. It demonstrates the ability to combine hash-based frequency counting with standard linked list traversal. Mentioning the brute force solution first shows problem exploration, but implementing the O(n) hash map solution shows strong algorithmic judgment and practical engineering thinking.
Solution
We can use a hash table cnt to count the number of occurrences of each element in the linked list, and then traverse the linked list to delete elements that appear more than once.
The time complexity is O(n), and the space complexity is O(n), where n is the length of the linked list.
# Definition for singly-linked list.
# class ListNode:
#     def __init__(self, val=0, next=None):
#         self.val = val
#         self.next = next
class Solution:
    def deleteDuplicatesUnsorted(self, head: ListNode) -> ListNode:
        cnt = Counter()
        cur = head
        while cur:
            cnt[cur.val] += 1
            cur = cur.next
        dummy = ListNode(0, head)
        pre, cur = dummy, head
        while cur:
            if cnt[cur.val] > 1:
                pre.next = cur.next
            else:
                pre = cur
            cur = cur.next
return dummy.next/**
* Definition for singly-linked list.
* public class ListNode {
* int val;
* ListNode next;
* ListNode() {}
* ListNode(int val) { this.val = val; }
* ListNode(int val, ListNode next) { this.val = val; this.next = next; }
* }
*/
class Solution {
public ListNode deleteDuplicatesUnsorted(ListNode head) {
Map<Integer, Integer> cnt = new HashMap<>();
for (ListNode cur = head; cur != null; cur = cur.next) {
cnt.put(cur.val, cnt.getOrDefault(cur.val, 0) + 1);
}
ListNode dummy = new ListNode(0, head);
for (ListNode pre = dummy, cur = head; cur != null; cur = cur.next) {
if (cnt.get(cur.val) > 1) {
pre.next = cur.next;
} else {
pre = cur;
}
}
return dummy.next;
}
}/**
* Definition for singly-linked list.
* struct ListNode {
* int val;
* ListNode *next;
* ListNode() : val(0), next(nullptr) {}
* ListNode(int x) : val(x), next(nullptr) {}
* ListNode(int x, ListNode *next) : val(x), next(next) {}
* };
*/
class Solution {
public:
ListNode* deleteDuplicatesUnsorted(ListNode* head) {
unordered_map<int, int> cnt;
for (ListNode* cur = head; cur; cur = cur->next) {
cnt[cur->val]++;
}
ListNode* dummy = new ListNode(0, head);
for (ListNode *pre = dummy, *cur = head; cur; cur = cur->next) {
if (cnt[cur->val] > 1) {
pre->next = cur->next;
} else {
pre = cur;
}
}
return dummy->next;
}
};/**
* Definition for singly-linked list.
* class ListNode {
* val: number
* next: ListNode | null
* constructor(val?: number, next?: ListNode | null) {
* this.val = (val===undefined ? 0 : val)
* this.next = (next===undefined ? null : next)
* }
* }
*/
function deleteDuplicatesUnsorted(head: ListNode | null): ListNode | null {
const cnt: Map<number, number> = new Map();
for (let cur = head; cur; cur = cur.next) {
const x = cur.val;
cnt.set(x, (cnt.get(x) ?? 0) + 1);
}
const dummy = new ListNode(0, head);
for (let pre = dummy, cur = head; cur; cur = cur.next) {
if (cnt.get(cur.val)! > 1) {
pre.next = cur.next;
} else {
pre = cur;
}
}
return dummy.next;
}/**
* Definition for singly-linked list.
* type ListNode struct {
* Val int
* Next *ListNode
* }
*/
func deleteDuplicatesUnsorted(head *ListNode) *ListNode {
cnt := map[int]int{}
for cur := head; cur != nil; cur = cur.Next {
cnt[cur.Val]++
}
dummy := &ListNode{0, head}
for pre, cur := dummy, head; cur != nil; cur = cur.Next {
if cnt[cur.Val] > 1 {
pre.Next = cur.Next
} else {
pre = cur
}
}
return dummy.Next
}Complexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Brute Force Nested Traversal | O(n²) | O(1) | When extra memory cannot be used and the list size is small |
| Hash Table Frequency Count | O(n) | O(n) | General case and interview-preferred solution for unsorted lists |
Frequently asked questions
Is Remove Duplicates From an Unsorted Linked List easy or hard?
The problem is generally classified as Medium difficulty. It requires combining hash table frequency counting with careful linked list pointer manipulation, which is slightly more involved than basic traversal problems.
Remove Duplicates From an Unsorted Linked List Python/Java solution
Implement a two-pass algorithm. In the first pass, store value counts in a dictionary (Python) or HashMap (Java). In the second pass, traverse the list with a dummy node and remove any node whose frequency is greater than one.
How to solve Remove Duplicates From an Unsorted Linked List in O(n)?
Use a hash map to record how many times each value appears in the list. After building the frequency map in one traversal, iterate through the list again and delete any node whose value appears more than once. Each node is processed a constant number of times, resulting in O(n) time complexity.
What is the best approach for Remove Duplicates From an Unsorted Linked List?
The most efficient approach uses a hash table to count how many times each value appears in the linked list. First traverse the list to build a frequency map, then perform a second pass to remove nodes whose frequency is greater than one. This method runs in O(n) time with O(n) extra space.
Is Remove Duplicates From an Unsorted Linked List asked at Google/Amazon/Meta?
Linked list deduplication and frequency-based removal problems commonly appear in interviews at companies like Amazon, Google, and Meta. Variations test knowledge of hash tables, pointer manipulation, and efficient list traversal.
What data structure is used in Remove Duplicates From an Unsorted Linked List?
The optimal solution relies on a hash table (or hash map) to store value frequencies. The linked list itself is traversed while pointers are adjusted to remove nodes with duplicate values.
What is the time complexity of Remove Duplicates From an Unsorted Linked List?
The optimal solution runs in O(n) time because the linked list is traversed twice: once to count frequencies and once to remove duplicate nodes. Hash table operations are O(1) on average. A naive brute force solution would take O(n²) time due to repeated scanning of the list.