Query Batching solution and explanation
The problem
Batching multiple small queries into a single large query can be a useful optimization. Write a class QueryBatcher that implements this functionality.
The constructor should accept two parameters:
- An asynchronous function
queryMultiplewhich accepts an array of string keysinput. It will resolve with an array of values that is the same length as the input array. Each index corresponds to the value associated withinput[i]. You can assume the promise will never reject. - A throttle time in milliseconds
t.
The class has a single method.
async getValue(key). Accepts a single string key and resolves with a single string value. The keys passed to this function should eventually get passed to thequeryMultiplefunction.queryMultipleshould never be called consecutively withintmilliseconds. The first timegetValueis called,queryMultipleshould immediately be called with that single key. If aftertmilliseconds,getValuehad been called again, all the passed keys should be passed toqueryMultipleand ultimately returned. You can assume every key passed to this method is unique.
The following diagram illustrates how the throttling algorithm works. Each rectangle represents 100ms. The throttle time is 400ms.
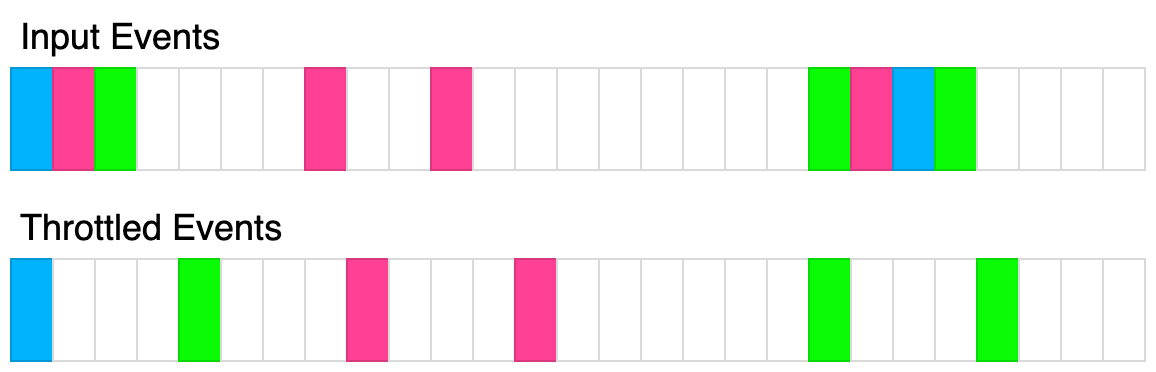
Example 1:
Input:
queryMultiple = async function(keys) {
  return keys.map(key => key + '!');
}
t = 100
calls = [
 {"key": "a", "time": 10},
 {"key": "b", "time": 20},
 {"key": "c", "time": 30}
]
Output: [
 {"resolved": "a!", "time": 10},
 {"resolved": "b!", "time": 110},
 {"resolved": "c!", "time": 110}
]
Explanation:
const batcher = new QueryBatcher(queryMultiple, 100);
setTimeout(() => batcher.getValue('a'), 10); // "a!" at t=10ms
setTimeout(() => batcher.getValue('b'), 20); // "b!" at t=110ms
setTimeout(() => batcher.getValue('c'), 30); // "c!" at t=110ms

queryMultiple simply adds an "!" to the key
At t=10ms, getValue('a') is called, queryMultiple(['a']) is immediately called and the result is immediately returned.
At t=20ms, getValue('b') is called but the query is queued
At t=30ms, getValue('c') is called but the query is queued.
At t=110ms, queryMultiple(['a', 'b']) is called and the results are immediately returned.
Example 2:
Input:
queryMultiple = async function(keys) {
  await new Promise(res => setTimeout(res, 100));
  return keys.map(key => key + '!');
}
t = 100
calls = [
 {"key": "a", "time": 10},
 {"key": "b", "time": 20},
 {"key": "c", "time": 30}
]
Output: [
  {"resolved": "a!", "time": 110},
  {"resolved": "b!", "time": 210},
  {"resolved": "c!", "time": 210}
]
Explanation:
This example is the same as example 1 except there is a 100ms delay in queryMultiple. The results are the same except the promises resolve 100ms later.
Example 3:
Input:
queryMultiple = async function(keys) {
  await new Promise(res => setTimeout(res, keys.length * 100));
  return keys.map(key => key + '!');
}
t = 100
calls = [
  {"key": "a", "time": 10},
  {"key": "b", "time": 20},
  {"key": "c", "time": 30},
  {"key": "d", "time": 40},
  {"key": "e", "time": 250}
  {"key": "f", "time": 300}
]
Output: [
  {"resolved":"a!","time":110},
  {"resolved":"e!","time":350},
  {"resolved":"b!","time":410},
  {"resolved":"c!","time":410},
  {"resolved":"d!","time":410},
  {"resolved":"f!","time":450}
]
Explanation:
queryMultiple(['a']) is called at t=10ms, it is resolved at t=110ms
queryMultiple(['b', 'c', 'd']) is called at t=110ms, it is resolved at 410ms
queryMultiple(['e']) is called at t=250ms, it is resolved at 350ms
queryMultiple(['f']) is called at t=350ms, it is resolved at 450ms
Constraints:
0 <= t <= 10000 <= calls.length <= 101 <= key.length <= 100- All keys are unique
Approach overview
Problem Overview: Query Batching asks you to process many incoming queries efficiently by grouping them into batches instead of executing each request individually. The goal is to minimize repeated work and improve throughput while still returning results for each query.
Approach 1: Naive Per-Query Execution (O(n) time, O(1) space)
The simplest strategy processes each query immediately when it arrives. Iterate through the list of requests and execute the underlying operation independently for every query. This approach is easy to implement but ignores the core optimization opportunity: multiple queries can often be processed together. If the backend call or computation is expensive, repeated execution leads to unnecessary overhead. Time complexity is O(n) and space complexity is O(1), but the constant cost of repeated calls makes it inefficient in real systems.
Approach 2: Fixed-Size Batch Processing (O(n) time, O(b) space)
A better strategy collects queries into groups of size b. Use a queue or list to accumulate incoming queries. Once the batch reaches the maximum size, execute them together using a single aggregated operation. This reduces repeated computation and network overhead. The algorithm iterates once through all queries while pushing them into the current batch and flushing when the limit is reached. Time complexity remains O(n) because every query is handled once, and auxiliary space is O(b) for the batch buffer. This approach is common in systems that process jobs using queue-based pipelines.
Approach 3: Dynamic Queue Batching (O(n) time, O(n) space)
The most flexible approach maintains a shared queue of pending queries and processes them in batches when certain conditions are met, such as reaching a size threshold or a time window. Each incoming query is appended to the queue, and a batching mechanism aggregates all pending requests before executing a single combined operation. A mapping structure can track individual responses so results can be routed back to the correct caller. This design frequently appears in high-throughput services and caching layers that rely on hash table lookups and asynchronous processing. Every query enters and leaves the queue exactly once, giving O(n) time complexity and O(n) auxiliary space.
Recommended for interviews: Start by explaining the naive per-query execution to demonstrate the baseline. Then transition to batching and describe how a queue collects requests before processing them together. Interviewers typically expect the dynamic batching design because it reflects how real distributed systems reduce repeated work and improve throughput. The optimal reasoning highlights queue management, aggregated execution, and constant-time bookkeeping using structures commonly seen in system design style problems.
The written solution for this problem is still being prepared. Try it yourself in the meantime.
Try solving it yourselfComplexity analysis
| Approach | Time | Space | When to Use |
|---|---|---|---|
| Naive Per-Query Execution | O(n) | O(1) | When batching is not supported or each query must run independently |
| Fixed-Size Batch Processing | O(n) | O(b) | When systems process requests in fixed batch sizes for throughput |
| Dynamic Queue Batching | O(n) | O(n) | General case where queries arrive asynchronously and should be aggregated efficiently |
Frequently asked questions
Is Query Batching easy or hard?
Query Batching is considered a hard problem because the challenge is not just iteration but designing an efficient batching mechanism. The solution requires reasoning about queues, batching triggers, and how to return results to individual queries while minimizing repeated work.
Query Batching Python/Java solution
A typical implementation in Python or Java maintains a list or queue for pending queries and processes them in groups. Python solutions often use lists or deque structures, while Java implementations use ArrayList or Queue interfaces to accumulate and flush batches.
How to solve Query Batching in O(n)?
Maintain a queue or list that stores pending queries. Iterate through incoming requests, append them to the batch, and trigger a combined execution when the batch limit or timing condition is reached. Since each query is inserted and removed once, the overall processing cost remains O(n).
What is the best approach for Query Batching?
The most effective solution uses a queue-based batching system. Incoming queries are appended to a shared queue and processed together when the batch reaches a threshold or trigger condition. This avoids executing the same expensive operation repeatedly and keeps overall processing at O(n) time.
Is Query Batching asked at Google/Amazon/Meta?
Batching patterns frequently appear in interviews at large tech companies because they reflect real system optimization techniques. Variations of request aggregation, job batching, and queue-based processing show up in backend, distributed systems, and system design rounds.
What data structure is used in Query Batching?
A queue is the most common structure because it preserves request order and supports efficient append and removal operations. Hash maps are often added to track responses or deduplicate queries, allowing constant-time lookups during batch execution.
What is the time complexity of Query Batching?
Most efficient implementations process each query once, giving O(n) time complexity where n is the number of queries. Additional bookkeeping such as queue insertion or hash lookups typically runs in O(1) per operation, keeping the total runtime linear.